Amazon GuardDuty

Amazon GuardDuty

Amazon GuardDuty

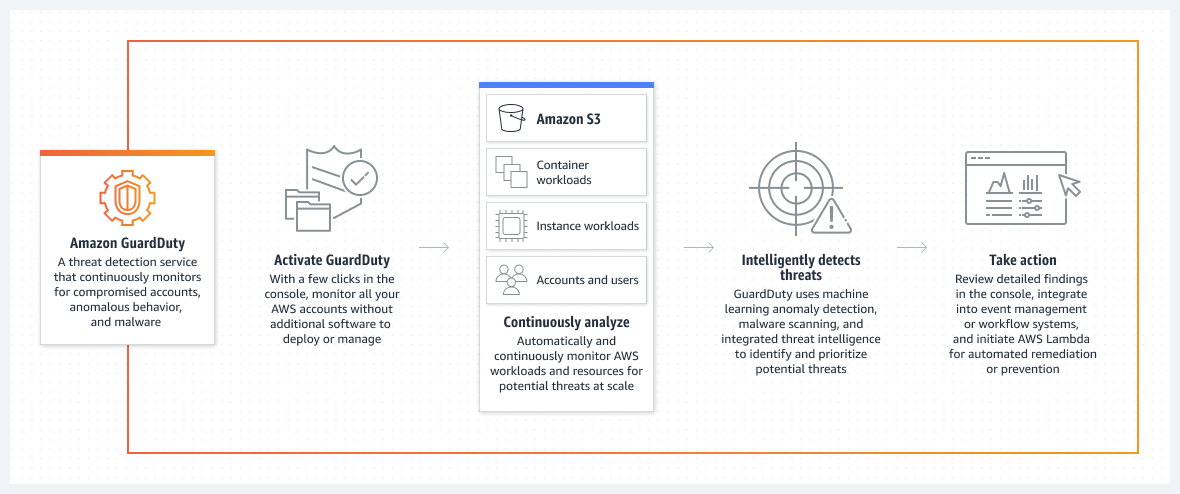
  • Amazon GuardDuty is a threat detection service that continuously monitors the AWS accounts and workloads for malicious activity and delivers detailed security findings for visibility and remediation.
  • is a continuous security monitoring service that analyzes and processes the following foundational data sources:
    • CloudTrail management event logs,
    • CloudTrail S3 data event logs,
    • DNS logs,
    • EKS audit logs,
    • VPC flow logs,
    • Amazon EBS volume data, and
    • Runtime activity from container workloads (Amazon EKS, Amazon ECS including Fargate, and Amazon EC2 instances).
  • uses threat intelligence feeds, such as lists of malicious IP addresses and domains, and machine learning to identify unexpected and potentially unauthorized and malicious activity within the AWS environment.
  • combines machine learning, anomaly detection, network monitoring, and malicious file discovery, utilizing both AWS-developed and industry-leading third-party sources to help protect workloads and data on AWS.
  • uses artificial intelligence (AI), machine learning (ML), and anomaly detection using both AWS and industry-leading threat intelligence to help protect AWS accounts, workloads, and data.
  • is a Regional service and is recommended to be enabled in all supported AWS Regions. This helps generate findings of unauthorized or unusual activity even in Regions not actively used.
  • does not look at historical data, it monitors only the activity that starts after it is enabled.
  • operates completely independent of the AWS resources and therefore has no impact on the performance or availability of the accounts or workloads.
  • GuardDuty supports
    • Suppression rules, allow the creation of very specific combinations of attributes to suppress findings. Supports wildcards (* and ?) and filtering on any finding field.
    • Trusted Entity Lists (previously Trusted IP Lists) for highly secure communication with the AWS environment. Now supports both IP addresses and domain names. Findings are not generated based on trusted entity lists.
    • Threat Entity Lists (previously Threat Lists) for known malicious IP addresses and domain names. Findings are generated based on threat entity lists.
  • Security findings are retained and made available through the GuardDuty console and APIs for 90 days, after which they are discarded.
  • Findings are assigned a severity (Critical, High, Medium, Low), and actions can be automated by integrating with Security Hub, EventBridge, Lambda, and Step Functions.
  • Amazon Detective is also tightly integrated with GuardDuty which helps perform deeper forensic and root cause investigations.
  • GuardDuty supports AWS PrivateLink (VPC endpoints) for private connectivity without traversing the public internet.
  • offers a 30-day free trial. After the free trial ends, cost is based on the volume of data analyzed.
Amazon GuardDuty

GuardDuty Protection Plans

  • GuardDuty offers multiple protection plans that can be independently enabled or disabled:
    1. Foundational GuardDuty – Core threat detection that cannot be disabled. Monitors CloudTrail management events, VPC Flow Logs, and DNS logs.
    2. S3 Protection – Monitors Amazon S3 data events for potential threats to data, such as data exfiltration and destruction.
    3. Runtime Monitoring – Monitors operating system-level events for EKS, ECS, and EC2 workloads using a GuardDuty security agent.
    4. EKS Audit Logs – Monitors Amazon EKS audit logs for potential threats to Kubernetes clusters.
    5. RDS Protection – Monitors RDS login activity for potential threats to databases. Supports Aurora MySQL, Aurora PostgreSQL (including Limitless Database), and RDS for PostgreSQL.
    6. Lambda Protection – Monitors Lambda function network activity for potential threats.
  • Each protection plan can be auto-enabled for new AWS Organizations accounts.
  • GuardDuty offers the flexibility to customize how new accounts inherit protection plans.

GuardDuty Extended Threat Detection

  • Introduced at AWS re:Invent 2024, Extended Threat Detection automatically detects multi-stage attacks that span data sources, multiple types of AWS resources, and time within an AWS account.
  • Uses sophisticated AI/ML algorithms trained at AWS scale to automatically correlate security signals and detect critical threats.
  • Enabled automatically for all GuardDuty accounts at no additional cost.
  • Correlates multiple events (called “Signals”) including API activities and GuardDuty findings to identify attack sequences.
  • Can detect weak signals that individually don’t present as clear threats but when combined reveal suspicious activity patterns.
  • Operates within a 24-hour rolling time window to detect in-progress or recent attacks.
  • All attack sequence findings are assigned Critical severity.
  • Attack sequence finding types include:
    • AttackSequence:S3/CompromisedData – Detects credential misuse leading to S3 data compromise.
    • AttackSequence:IAM/CompromisedCredentials – Detects multi-stage attacks using compromised IAM credentials.
    • AttackSequence:EKS/CompromisedCluster – Detects compromised EKS clusters (June 2025).
    • AttackSequence:EC2/CompromisedInstanceGroup – Detects compromised EC2 instance groups (December 2025).
    • AttackSequence:ECS/CompromisedCluster – Detects compromised ECS clusters (December 2025).
  • Enabling additional protection plans (S3 Protection, EKS Protection, Runtime Monitoring) widens the range of event sources and enables more comprehensive attack sequence detection.

GuardDuty Runtime Monitoring

  • Runtime Monitoring uses a lightweight GuardDuty security agent that adds visibility into runtime behavior including file access, process execution, command line arguments, and network connections.
  • Supports three resource types:
    • Amazon EKS – Uses an EKS add-on (aws-guardduty-agent) deployed on EKS clusters.
    • Amazon ECS (Fargate) – Monitors ECS workloads running on Fargate.
    • Amazon EC2 – Monitors EC2 instances using SSM-based agent deployment (GA March 2024).
  • Supports automated agent configuration that permits GuardDuty to install and manage the security agent automatically.
  • Supports inclusion/exclusion tags to control which resources get the security agent.
  • Detects threats such as crypto-mining, malicious file execution, suspicious shell creation, privilege escalation, reverse shells, and defense evasion techniques.
  • Supports Amazon EKS Auto Mode.

GuardDuty with Multiple Accounts

  • GuardDuty has multi-account management through AWS Organizations integration, which allows delegating an administrator account for the organization.
  • The delegated administrator (DA) account is a centralized account that consolidates all findings and can configure all member accounts.
  • Supports up to 50,000 member accounts through AWS Organizations (including up to 5,000 by invitation).
  • All security findings are aggregated to the administrator account for review and remediation.
  • EventBridge events are also aggregated to the administrator account.
  • Organization configuration allows auto-enabling GuardDuty and protection plans for ALL accounts, new accounts only, or no auto-enable.

GuardDuty Automated Remediation

  • GuardDuty security findings can be remediated automatically using EventBridge and AWS Lambda.
  • For example, a Lambda function can be created to modify the AWS security group rules based on security findings. For a GuardDuty finding indicating one of your EC2 instances is being probed by a known malicious IP, the address can be added through an EventBridge rule, initiating a Lambda function to automatically modify the security group rules and restrict access on that port.
  • Findings are exported to Amazon S3 for long-term storage and analysis.
  • Integrates with AWS Security Incident Response for automated triage and investigation.

GuardDuty Malware Protection

  • GuardDuty Malware Protection includes three capabilities:

Malware Protection for EC2

  • Scans EBS volumes attached to EC2 instances and container workloads for malware.
  • Creates a replica EBS volume from a snapshot and scans it for trojans, worms, crypto miners, rootkits, bots, and more.
  • Supports two scan types:
    • GuardDuty-initiated – Automatically triggered when certain GuardDuty findings are generated.
    • On-demand – Manually initiated by providing the EC2 instance ARN.
  • Supports scanning EBS volumes up to 2048 GB.
  • Supports scanning EBS volumes encrypted with AWS managed keys.
  • Supports Amazon EKS Auto Mode managed instances.

Malware Protection for S3

  • Launched June 2024, provides built-in malware scanning for objects uploaded to designated S3 buckets.
  • Automatically scans newly uploaded objects using multiple AWS-developed and industry-leading third-party malware scanning engines.
  • Supports on-demand scanning of existing S3 objects via the SendObjectMalwareScan API (November 2025).
  • Supports scanning objects up to 100 GB (increased from 5 GB in July 2025).
  • Publishes scan results to EventBridge for downstream workflows (e.g., quarantine to a separate bucket).
  • Can add tags to scanned objects indicating scan status.
  • GuardDuty automatically updates malware signatures every 15 minutes.

Malware Protection for AWS Backup

  • Launched November 2025, detects the potential presence of malware in backup resources.
  • Scans AWS Backup-protected resources including Amazon EBS snapshots, EC2 AMIs, and Amazon S3 Recovery Points.
  • Supports full and incremental scans.
  • Helps identify the last known clean backup for recovery.
  • Can automate malware scanning across the entire organization.

GuardDuty AI Workload Protection

  • Launched August 2024, GuardDuty foundational threat detection and Lambda Protection help detect threats to AI workloads built on AWS.
  • Detects when Amazon Bedrock model invocation logging is disabled (DefenseEvasion:IAMUser/BedrockLoggingDisabled finding type, November 2025).
  • Monitors for unauthorized access to AI/ML resources and data exfiltration attempts.

GuardDuty Custom Threat Detection

  • GuardDuty introduced custom Entity Lists (August 2025) that support both IP addresses and domain names for custom threat detection.
  • Replaces the legacy IP-only threat lists with more comprehensive entity-based lists.
  • Supports:
    • Trusted Entity Lists – IP addresses and domain names to suppress findings.
    • Threat Entity Lists – Known malicious IP addresses and domain names to generate findings.
  • Only the GuardDuty administrator account can manage entity lists; settings apply automatically to member accounts.
  • GuardDuty recommends using entity lists over the legacy IP address lists.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. Which AWS service makes detecting and reporting unexpected and potentially malicious activity in your AWS environment easy?
    1. AWS Shield
    2. AWS Inspector
    3. AWS GuardDuty
    4. AWS WAF
  2. A company needs to detect multi-stage attacks that span multiple AWS services and resources over time. Which GuardDuty capability should they rely on?
    1. GuardDuty Malware Protection
    2. GuardDuty Runtime Monitoring
    3. GuardDuty Extended Threat Detection
    4. GuardDuty RDS Protection
  3. Which GuardDuty protection plan monitors operating system-level events on container and EC2 workloads? (Select TWO)
    1. Runtime Monitoring
    2. S3 Protection
    3. Lambda Protection
    4. EKS Audit Logs
    5. Malware Protection for EC2
  4. A company wants to scan S3 objects for malware when they are uploaded to a bucket. Which GuardDuty feature should they enable?
    1. GuardDuty Malware Protection for EC2
    2. GuardDuty Malware Protection for S3
    3. GuardDuty S3 Protection
    4. GuardDuty Extended Threat Detection
  5. What severity level do GuardDuty Extended Threat Detection attack sequence findings receive?
    1. High
    2. Critical
    3. Medium
    4. Varies based on the attack type
  6. A security team wants to add their own threat intelligence containing both malicious domains and IP addresses to GuardDuty. What should they use?
    1. Trusted IP Lists
    2. Threat Entity Lists
    3. Suppression Rules
    4. Custom Finding Types

See also: AWS Security Lake – Centralized Security Data Lake
References

AWS Data Pipeline – ETL Workflow Orchestration

⚠️ AWS Data Pipeline – Maintenance Mode (No Longer Available to New Customers)

AWS closed new customer access to AWS Data Pipeline effective July 25, 2024. The service is now in maintenance mode — no new features or region expansions are planned.

Existing customers can continue to use the service as normal, but AWS recommends migrating to modern alternatives.

Recommended Migration Alternatives:

  • AWS Glue – Serverless data integration service for ETL, Apache Spark applications, and data orchestration with visual editors and notebooks.
  • AWS Step Functions – Serverless orchestration service for building workflows integrating 250+ AWS services with visual designer and JSON-based workflow definitions.
  • Amazon MWAA – Managed Apache Airflow service for end-to-end data pipeline orchestration with Python-based DAGs and 1,000+ pre-built operators.

See Migrating workloads from AWS Data Pipeline for detailed migration guidance.

AWS Data Pipeline

  • AWS Data Pipeline is a web service that makes it easy to automate and schedule regular data movement and data processing activities in AWS
  • helps define data-driven workflows
  • integrates with on-premises and cloud-based storage systems
  • helps quickly define a pipeline, which defines a dependent chain of data sources, destinations, and predefined or custom data processing activities
  • supports scheduling where the pipeline regularly performs processing activities such as distributed data copy, SQL transforms, EMR applications, or custom scripts against destinations such as S3, RDS, or DynamoDB.
  • ensures that the pipelines are robust and highly available by executing the scheduling, retry, and failure logic for the workflows as a highly scalable and fully managed service.

AWS Data Pipeline features

  • Distributed, fault-tolerant, and highly available
  • Managed workflow orchestration service for data-driven workflows
  • Infrastructure management service, as it will provision and terminate resources as required
  • Provides dependency resolution
  • Can be scheduled
  • Supports Preconditions for readiness checks.
  • Grants control over retries, including frequency and number
  • Native integration with S3, DynamoDB, RDS, EMR, EC2 and Redshift
  • Support for both AWS based and external on-premise resources

AWS Data Pipeline Concepts

Pipeline Definition

  • Pipeline definition helps the business logic to be communicated to the AWS Data Pipeline
  • Pipeline definition defines the location of data (Data Nodes), activities to be performed, the schedule, resources to run the activities, per-conditions, and actions to be performed

Pipeline Components, Instances, and Attempts

  • Pipeline components represent the business logic of the pipeline and are represented by the different sections of a pipeline definition.
  • Pipeline components specify the data sources, activities, schedule, and preconditions of the workflow
  • When AWS Data Pipeline runs a pipeline, it compiles the pipeline components to create a set of actionable instances and contains all the information needed to perform a specific task
  • Data Pipeline provides durable and robust data management as it retries a failed operation depending on frequency & defined number of retries

Task Runners

  • A task runner is an application that polls AWS Data Pipeline for tasks and then performs those tasks
  • When Task Runner is installed and configured,
    • it polls AWS Data Pipeline for tasks associated with activated pipelines
    • after a task is assigned to Task Runner, it performs that task and reports its status back to Pipeline.
  • A task is a discreet unit of work that the Pipeline service shares with a task runner and differs from a pipeline, which defines activities and resources that usually yields several tasks
  • Tasks can be executed either on the AWS Data Pipeline managed or user-managed resources.

Data Nodes

  • Data Node defines the location and type of data that a pipeline activity uses as source (input) or destination (output)
  • supports S3, Redshift, DynamoDB, and SQL data nodes

Databases

  • supports JDBC, RDS, and Redshift database

Activities

  • An activity is a pipeline component that defines the work to perform
  • Data Pipeline provides pre-defined activities for common scenarios like sql transformation, data movement, hive queries, etc
  • Activities are extensible and can be used to run own custom scripts to support endless combinations

Preconditions

  • Precondition is a pipeline component containing conditional statements that must be satisfied (evaluated to True) before an activity can run
  • A pipeline supports
    • System-managed preconditions
      • are run by the AWS Data Pipeline web service on your behalf and do not require a computational resource
      • Includes source data and keys check for e.g. DynamoDB data, table exists or S3 key exists or prefix not empty
    • User-managed preconditions
      • run on user defined and managed computational resources
      • Can be defined as Exists check or Shell command

Resources

  • A resource is a computational resource that performs the work that a pipeline activity specifies
  • supports AWS Data Pipeline-managed and self-managed resources
  • AWS Data Pipeline-managed resources include EC2 and EMR, which are launched by the Data Pipeline service only when they’re needed
  • Self managed on-premises resources can also be used, where a Task Runner package is installed which continuously polls the AWS Data Pipeline service for work to perform
  • Resources can run in the same region as their working data set or even on a region different than AWS Data Pipeline
  • Resources launched by AWS Data Pipeline are counted within the resource limits and should be taken into account

Actions

  • Actions are steps that a pipeline takes when a certain event like success, or failure occurs.
  • Pipeline supports SNS notifications and termination action on resources

Migration to Modern Alternatives

AWS recommends migrating existing Data Pipeline workloads to one of the following services based on your use case:

Migrate to AWS Glue

  • Best for serverless ETL workloads, Apache Spark-based processing, and data integration
  • Supports visual editors, notebooks, and crawlers for data discovery
  • Natively supports DynamoDB export/import (common Data Pipeline use case)
  • Includes data quality, sensitive data detection, and Data Catalog capabilities
  • Ideal when migrating pipelines built from pre-defined Data Pipeline templates (e.g., DynamoDB to S3 export)

Migrate to AWS Step Functions

  • Best for orchestrating multi-service workflows with visual designer
  • Integrates with 250+ AWS services and 11,000+ actions out-of-the-box
  • Uses Amazon States Language (JSON-based), similar to Data Pipeline’s JSON definitions
  • Cost-effective with per-task granularity pricing
  • Supports on-premises resources via AWS Systems Manager Run Command
  • Ideal for workloads requiring EC2, EMR, or Lambda orchestration

Migrate to Amazon MWAA (Managed Apache Airflow)

  • Best for complex workflow orchestration using Python-based DAGs
  • Provides 1,000+ pre-built operators covering AWS and non-AWS services
  • Rich UI for observability, restarts, backfills, and lineage tracking
  • Fully managed, open source (Apache Airflow) for maximum portability
  • Ideal for teams already using Airflow or needing advanced orchestration features

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  • Note: AWS Data Pipeline is in maintenance mode and unlikely to appear on newer exam versions. However, questions about data orchestration concepts may reference modern alternatives like AWS Glue, Step Functions, or Amazon MWAA.
  1. An International company has deployed a multi-tier web application that relies on DynamoDB in a single region. For regulatory reasons they need disaster recovery capability in a separate region with a Recovery Time Objective of 2 hours and a Recovery Point Objective of 24 hours. They should synchronize their data on a regular basis and be able to provision the web application rapidly using CloudFormation. The objective is to minimize changes to the existing web application, control the throughput of DynamoDB used for the synchronization of data and synchronize only the modified elements. Which design would you choose to meet these requirements?
    1. Use AWS data Pipeline to schedule a DynamoDB cross region copy once a day. Create a ‘Lastupdated’ attribute in your DynamoDB table that would represent the timestamp of the last update and use it as a filter. (Refer Blog Post)
    2. Use EMR and write a custom script to retrieve data from DynamoDB in the current region using a SCAN operation and push it to DynamoDB in the second region. (No Schedule and throughput control)
    3. Use AWS data Pipeline to schedule an export of the DynamoDB table to S3 in the current region once a day then schedule another task immediately after it that will import data from S3 to DynamoDB in the other region. (With AWS Data pipeline the data can be copied directly to other DynamoDB table)
    4. Send each item into an SQS queue in the second region; use an auto-scaling group behind the SQS queue to replay the write in the second region. (Not Automated to replay the write)

    Note: For new implementations, consider DynamoDB Global Tables for cross-region replication, or AWS Glue for scheduled ETL workloads.

  2. Your company produces customer commissioned one-of-a-kind skiing helmets combining nigh fashion with custom technical enhancements. Customers can show off their Individuality on the ski slopes and have access to head-up-displays, GPS rear-view cams and any other technical innovation they wish to embed in the helmet. The current manufacturing process is data rich and complex including assessments to ensure that the custom electronics and materials used to assemble the helmets are to the highest standards. Assessments are a mixture of human and automated assessments you need to add a new set of assessment to model the failure modes of the custom electronics using GPUs with CUD across a cluster of servers with low latency networking. What architecture would allow you to automate the existing process using a hybrid approach and ensure that the architecture can support the evolution of processes over time?
    1. Use AWS Data Pipeline to manage movement of data & meta-data and assessments. Use an auto-scaling group of G2 instances in a placement group. (Involves mixture of human assessments)
    2. Use Amazon Simple Workflow (SWF) to manage assessments, movement of data & meta-data. Use an autoscaling group of G2 instances in a placement group. (Human and automated assessments with GPU and low latency networking)
    3. Use Amazon Simple Workflow (SWF) to manage assessments movement of data & meta-data. Use an autoscaling group of C3 instances with SR-IOV (Single Root I/O Virtualization). (C3 and SR-IOV won’t provide GPU as well as Enhanced networking needs to be enabled)
    4. Use AWS data Pipeline to manage movement of data & meta-data and assessments use auto-scaling group of C3 with SR-IOV (Single Root I/O virtualization). (Involves mixture of human assessments)

    Note: For modern implementations, AWS Step Functions has largely replaced SWF for workflow orchestration including human-in-the-loop tasks. Current GPU instances include P4, P5, and G5 families.

References

AWS Lake Formation

AWS Lake Formation

AWS Lake Formation

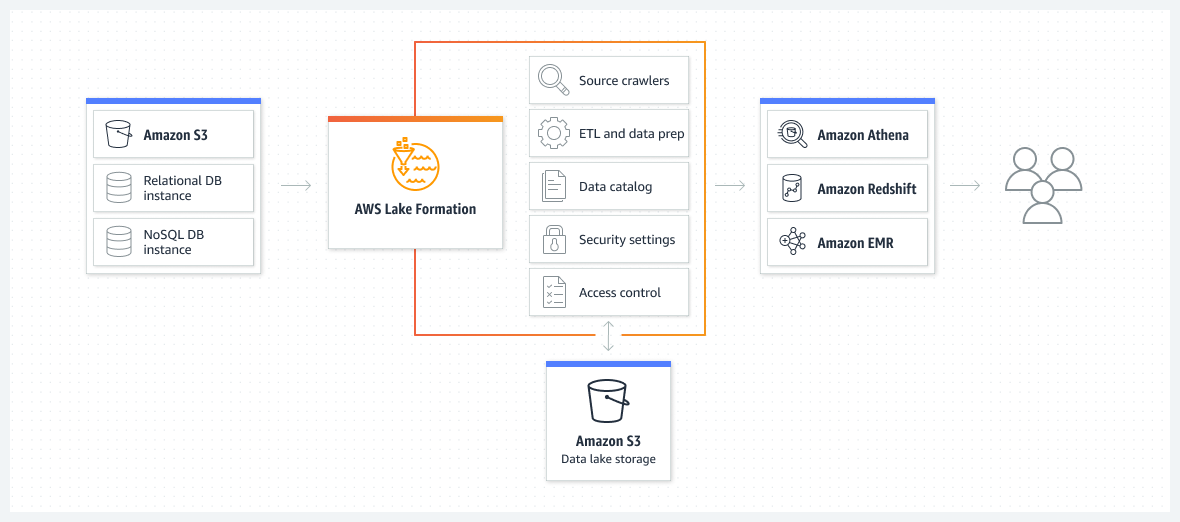
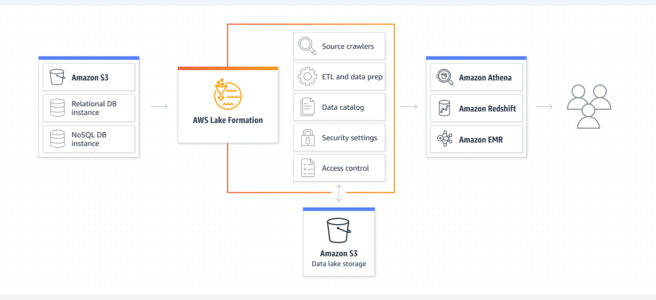
  • AWS Lake Formation easily creates secure data lakes, making data available for wide-ranging analytics.
  • is an integrated data lake service that helps to discover, ingest, clean, catalog, transform, and secure data and make it available for analysis and ML.
  • automatically manages access to the registered data in S3 through services including AWS Glue, Athena, Redshift, QuickSight, and EMR to ensure compliance with your defined policies.
  • helps configure and manage your data lake without manually integrating multiple underlying AWS services.
  • can manage data ingestion through AWS Glue. Data is automatically classified, and relevant data definitions, schema, and metadata are stored in the central Glue Data Catalog. Once the data is in the S3 data lake, access policies, including table-and-column-level access controls can be defined, and encryption for data at rest enforced.
  • uses a shared infrastructure with AWS Glue, including console controls, ETL code creation and job monitoring, blueprints to create workflows for data ingest, the same data catalog, and a serverless architecture.
  • integrates with IAM so authenticated users and roles can be automatically mapped to data protection policies that are stored in the data catalog. The IAM integration also supports Microsoft Active Directory or LDAP to federate into IAM using SAML.
  • helps centralize data access policy controls. Users and roles can be defined to control access, down to the table and column level.
  • supports private endpoints in the VPC and records all activity in AWS CloudTrail for network isolation and auditability.
  • is part of the Amazon SageMaker Lakehouse architecture (announced at re:Invent 2024), which unifies data across S3 data lakes, S3 Tables, and Redshift data warehouses with consistent Lake Formation permissions across all analytics and ML engines.

AWS Lake Formation

Lake Formation Fine-Grained Access Control (FGAC)

  • Lake Formation provides fine-grained access control at database, table, column, row, and cell levels.
  • Column-Level Security – restrict access to specific columns within a table.
  • Row-Level Security – define data filters with row filter expressions to restrict rows returned in query results.
  • Cell-Level Security – combine column-level and row-level security using data cell filters to restrict access at the cell level.
  • Data filters define both the columns that a user has access to and the rows that match a filter expression.
  • Fine-grained permissions are enforced across Athena, Redshift Spectrum, EMR, and AWS Glue ETL jobs.
  • Supports Open Table Formats (OTFs) including Apache Iceberg, Apache Hudi, and Delta Lake with table, row, column, and cell-level permissions.

Lake Formation Tag-Based Access Control (LF-TBAC)

  • LF-TBAC provides a scalable way to manage permissions using LF-Tags (key-value pairs) assigned to Data Catalog resources.
  • Instead of defining policies per named resource, data stewards create LF-Tags based on business needs and attach them to databases, tables, and columns.
  • Permissions are granted to principals based on matching LF-Tags, enabling automatic access as new resources are tagged.
  • Supports cross-account data sharing using AWS Resource Access Manager (RAM).
  • LF-Tag Expressions (Nov 2024) – save and reuse LF-Tag expressions to grant permissions on Data Catalog resources, reducing policy management overhead.
  • Supports tag-based access control for federated catalogs including Amazon S3 Tables, Amazon Redshift data warehouses, and federated data sources (DynamoDB, SQL Server, Snowflake).

Lake Formation Attribute-Based Access Control (ABAC)

  • (April 2025) – Lake Formation allows granting permissions to principals with matching attributes on Data Catalog resources.
  • Extends beyond tag-based controls to match principal attributes for fine-grained authorization.

Lake Formation Hybrid Access Mode

  • (September 2023) – provides flexibility to selectively enable Lake Formation permissions for specific databases and tables in the Data Catalog.
  • Both Lake Formation permissions and IAM permissions can control access to the same data simultaneously.
  • Opted-in principals require both Lake Formation permissions and IAM permissions, while non-opted-in principals continue accessing data using only IAM permissions.
  • Enables incremental migration to Lake Formation without interrupting existing users or workloads.
  • Integrates with Amazon DataZone (April 2024) – allows publishing and sharing Glue tables through DataZone without requiring prior Lake Formation registration.

Lake Formation Cross-Account Data Sharing

  • Share Data Catalog databases and tables across AWS accounts within or outside an AWS Organization.
  • Share with entire AWS accounts or directly with IAM principals in another account.
  • Supports cross-account sharing using both tag-based access control and named resource methods.
  • Uses AWS Resource Access Manager (RAM) for cross-account grants.
  • (Feb 2026) – Enhanced cross-account sharing allows sharing hundreds of thousands of tables across accounts for multi-account analytics environments at scale.
  • RetainSharingOnAccountLeaveOrganization parameter – keeps resource shares in place when accounts change organizations.
  • Enables building a data mesh architecture with producer accounts, central governance accounts, and consumer accounts.

Lake Formation Credential Vending

  • Provides temporary credentials to users, services, or applications for short-term access to Amazon S3 data.
  • Supports integration with third-party services and engines through credential vending API operations.
  • (June 2026) – Lake Formation extends table permissions to access underlying data files in S3 directly, using the GetTemporaryDataLocationCredentials() API.
  • Provides a single set of permissions for both SQL queries and direct file access using existing Lake Formation table grants.
  • Eliminates the need to maintain separate S3 bucket policies or IAM role policies for file-level access.
  • Supports auditable credential vending with IAM Identity Center user context in CloudTrail events (July 2024).

Lake Formation Multi-Catalog and Federated Catalogs

  • (December 2024) – AWS Glue Data Catalog allows creating federated catalogs to unify data across:
    • Amazon S3 data lakes
    • Amazon Redshift data warehouses
    • Operational databases (Amazon DynamoDB)
    • Third-party data sources (Snowflake, MySQL, etc.)
  • Lake Formation permissions apply consistently across all federated catalogs.
  • New permissions added: CREATE_CATALOG and SUPER_USER for catalog-level access control.

Lake Formation with Amazon S3 Tables

  • (March 2025) – S3 Tables can be integrated and cataloged as AWS Glue Data Catalog objects and registered as Lake Formation data locations.
  • Enables Lake Formation governance over S3 Tables using the same permission model as standard data lake tables.
  • Supports building cross-account data mesh architectures with S3 Tables where producer, governance, and consumer accounts operate independently.

Lake Formation with Open Table Formats

  • Supports managing access permissions for Apache Iceberg, Apache Hudi, and Delta Lake tables.
  • Enforces table, row, column, and cell-level permissions on OTF-based tables.
  • Apache Iceberg has the best integration with AWS Glue ETL via Lake Formation permissions, including full SQL support.
  • AWS Glue Data Catalog provides managed compaction for Iceberg tables to improve query performance.
  • Supports catalog federation for remote Apache Iceberg tables stored in external Iceberg catalogs.

Governed Tables (Deprecated)

⚠️ DEPRECATED: Lake Formation Governed Tables were deprecated effective December 31, 2024. All Governed Table APIs stopped working after February 17, 2025.

Migration: AWS recommends using open source transactional table formats — Apache Iceberg (recommended), Apache Hudi, or Delta Lake — which provide ACID transactions, time-travel queries, and automatic compaction natively.

  • Governed Tables previously provided ACID transactions, automatic data compaction, and time-travel queries within Lake Formation.
  • These capabilities are now fully supported through Apache Iceberg tables in the AWS Glue Data Catalog.

Lake Formation Blueprints and Workflows

  • Blueprints define the source data target and schedule for loading data into the data lake.
  • Workflows encapsulate complex multi-job ETL activities, generating AWS Glue crawlers, jobs, and triggers.
  • Lake Formation executes and tracks a workflow as a single entity.
  • Supports both on-demand and scheduled workflow execution.
  • Workflows are visible in the Glue console as a directed acyclic graph (DAG).
  • Blueprint types include Database Snapshot and Incremental Database.

Lake Formation Data Catalog Views

  • (November 2023) – create views in the AWS Glue Data Catalog that reference up to 10 tables.
  • Views can be created using SQL editors for Athena or Redshift, or via AWS Glue APIs (August 2024).
  • Lake Formation permissions can be applied to views for fine-grained access control.

Lake Formation Cross-Region Data Access

  • Supports querying Data Catalog tables across AWS Regions.
  • Access data in other Regions using Athena, EMR, and AWS Glue ETL by creating resource links pointing to source databases and tables.

Lake Formation Integration with IAM Identity Center

  • (November 2023) – integrates with IAM Identity Center for workforce identity federation.
  • Users and groups managed in Identity Center can access Data Catalog resources with Lake Formation permissions enforced.
  • Supports trusted identity propagation for analytics queries.

Lake Formation Key Integrations

  • Amazon SageMaker Lakehouse – unified lakehouse architecture with Lake Formation as the governance layer for all analytics and ML workloads.
  • Amazon DataZone – data management service that uses Lake Formation for access control and governance when sharing data assets.
  • Amazon Athena – serverless queries with Lake Formation FGAC enforced.
  • Amazon Redshift / Redshift Spectrum – data sharing governed by Lake Formation permissions and LF-Tags.
  • Amazon EMR – Spark, Hive, and Presto jobs with table, row, column, and cell-level security via Lake Formation.
  • AWS Glue ETL – fine-grained access control enforced in ETL jobs.
  • Amazon QuickSight – BI dashboards with Lake Formation permissions.
  • Amazon SageMaker Feature Store – supports fine-grained access control through Lake Formation for ML feature pipelines.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. A company needs to centrally manage fine-grained access control for its data lake stored in Amazon S3. Data analysts should only see rows relevant to their department when querying tables via Amazon Athena. Which approach should be used?
    1. Create separate S3 buckets per department and use S3 bucket policies
    2. Use AWS Lake Formation data filters with row-level security expressions
    3. Create separate Athena workgroups with IAM policies per department
    4. Use S3 Access Points with different policies per department
  2. A data engineering team wants to migrate to Lake Formation for permission management but cannot disrupt existing workloads that use IAM-based access to Glue Data Catalog tables. Which feature should they use?
    1. Lake Formation tag-based access control
    2. Lake Formation hybrid access mode
    3. Lake Formation credential vending
    4. Lake Formation cross-account sharing
  3. An organization has 50 analytics teams across 20 AWS accounts that need to share and govern hundreds of thousands of tables centrally. Which Lake Formation capability best supports this at scale?
    1. S3 bucket policies with cross-account access
    2. Lake Formation cross-account data sharing with LF-Tag-based access control
    3. AWS RAM resource shares without Lake Formation
    4. IAM roles with assume-role policies per account
  4. A company uses Apache Iceberg tables stored in Amazon S3 and needs to enforce column-level and cell-level security for different user groups querying via Athena and EMR. Which service provides this capability?
    1. S3 Access Grants
    2. AWS Glue Data Quality
    3. AWS Lake Formation with data cell filters
    4. Amazon Macie with data classification
  5. A data science team needs to access the underlying S3 data files directly for an ML training pipeline, but the tables are governed by Lake Formation permissions. Previously they had to maintain separate S3 bucket policies. Which new feature eliminates this overhead?
    1. S3 Access Points
    2. Lake Formation credential vending with GetTemporaryDataLocationCredentials API
    3. IAM Identity Center direct S3 access
    4. AWS Glue Data Catalog resource policies
  6. A company previously used Lake Formation Governed Tables for ACID transactions in their data lake. After the deprecation in December 2024, which is the AWS-recommended replacement? (Select TWO)
    1. Amazon DynamoDB transactions
    2. Apache Iceberg tables in the Glue Data Catalog
    3. Amazon Aurora with S3 export
    4. Apache Hudi tables with Lake Formation permissions
    5. Amazon Redshift Serverless
Show Answer

Answers: –

  • B – Lake Formation data filters support row-level security to restrict rows returned based on filter expressions.
  • B – Hybrid access mode allows selective enablement of Lake Formation permissions without disrupting existing IAM-based access.
  • B – LF-TBAC with cross-account sharing scales to hundreds of thousands of tables across multiple accounts.
  • C – Lake Formation supports fine-grained access control (including cell-level security) for Apache Iceberg and other open table formats.
  • B – The GetTemporaryDataLocationCredentials API vends temporary credentials scoped to S3 locations, providing unified permissions for both SQL queries and direct file access.
  • B, D – AWS recommends migrating to open table formats (Apache Iceberg preferred, Hudi also supported) which provide ACID transactions natively with Lake Formation permission support.
  • References

    AWS Resource Access Manager – RAM

    AWS Resource Access Manager – RAM

    • AWS Resource Access Manager – RAM helps secure sharing of the AWS resources created in one AWS account with other AWS accounts.
    • Using RAM, with multiple AWS accounts, a resource can be created once and made usable by those other accounts.
    • For an account managed by AWS Organizations, resources can be shared with all the other accounts in the organization or only those accounts contained by one or more specified organizational units (OUs).
    • Resources can also be shared with specific AWS accounts by account ID, regardless of whether the account is part of an organization.
    • RAM supports sharing resources with IAM roles and users in addition to accounts and organizations.
    • RAM supports AWS PrivateLink, allowing you to connect directly to RAM using an interface VPC endpoint for secure private access without traversing the public internet.

    RAM Benefits

    • Reduces operational overhead
      • Create a resource once, and then use AWS RAM to share that resource with other accounts. This eliminates the need to provision duplicate resources in every account, which reduces operational overhead.
    • Provides security and consistency
      • Simplify security management for the shared resources by using a single set of policies and permissions.
      • Supports both AWS managed permissions and customer managed permissions for fine-grained access control over shared resources.
    • Provides visibility and auditability
      • AWS RAM provides comprehensive visibility into shared resources and accounts through the integration with CloudWatch and CloudTrail.

    RAM Key Features

    • Customer Managed Permissions
      • In addition to AWS managed permissions, RAM supports customer managed permissions that allow you to author and maintain fine-grained resource access controls for supported resource types.
      • Customer managed permissions let you define exactly which actions a consumer can perform on shared resources.
      • You can create, view, and manage permission versions through the RAM console or APIs.
    • RetainSharingOnAccountLeaveOrganization (Feb 2026)
      • New resource share configuration that maintains resource sharing continuity when accounts move between AWS Organizations.
      • When enabled, RAM treats organization accounts as external accounts, requiring explicit invitation acceptance and preserving resource access during account transitions.
      • Useful for organizations undergoing mergers, acquisitions, or restructuring to maintain uninterrupted access to shared resources.
      • Security teams can use SCPs to enforce this configuration organization-wide.
    • Service Principal Sharing
      • You can associate service principals to resource shares, allowing specified AWS services to manage necessary actions for customer resources on your behalf.
    • AWS PrivateLink Support (Sept 2024)
      • RAM supports interface VPC endpoints via AWS PrivateLink, enabling private connectivity to RAM APIs without traversing the public internet.

    RAM vs Resource-based Policies

    • Resources can be shared with an Organization or OU without having to enumerate every one of the AWS account IDs.
    • Users can see the resources shared with them directly in the originating AWS service console and API operations as if those resources were directly in the user’s account.
    • Owners of a resource can see which principals have access to each individual resource that they have shared.
    • RAM initiates an invitation process for resources shared with an account that isn’t part of the organization. Sharing within an organization doesn’t require an invitation and is auto-accepted.
    • RAM supports customer managed permissions for fine-grained access, while resource-based policies are defined per resource at the service level.

    RAM Supported Resources

    • Amazon API Gateway (domain names) – Added Nov 2024
    • Amazon Application Recovery Controller (ARC) (clusters, plans)
    • AWS App Mesh – Deprecated: EOL Sept 30, 2026. Migrate to Amazon VPC Lattice or ECS Service Connect.
    • AWS AppSync (GraphQL APIs)
    • Amazon Aurora
    • AWS Backup (logically air-gapped vaults) – Added Aug 2024
    • Amazon Bedrock (custom models) – Added Aug 2024
    • AWS Billing and Cost Management (views, dashboards) – Added Dec 2024/Aug 2025
    • AWS Cloud Map (namespaces) – Added Aug 2025
    • AWS Cloud WAN
    • Amazon CloudFront (VPC Origins) – Added Oct 2025
    • AWS CloudHSM (backups) – Added Jun 2024
    • AWS CodeBuild
    • AWS CodeConnections (code connections) – Added Mar 2025
    • Amazon DataZone
    • Amazon EC2 (Dedicated Hosts, Capacity Reservations, placement groups)
    • EC2 Image Builder
    • Elastic Load Balancing (trust stores) – Added Aug 2024
    • AWS End User Messaging SMS – Added Sept 2024
    • Amazon FSx for OpenZFS (snapshots)
    • AWS Glue
    • AWS License Manager
    • AWS Marketplace Catalog (entities)
    • AWS Migration Hub Refactor Spaces
    • Multi-party Approval (approval teams) – Added Jun 2025
    • AWS Network Firewall (policies, rule groups, firewalls)
    • Oracle Database@AWS (Exadata infrastructure, ODB networks) – Added Jun 2025
    • AWS Outposts
    • AWS Private Certificate Authority (AWS Private CA)
    • AWS Resource Explorer (views)
    • AWS Resource Groups
    • Amazon Route 53 (Resolver rules, query logs, DNS Firewall rule groups, Resolver Profiles)
    • Amazon S3 (Access Grants Instance)
    • Amazon S3 on Outposts
    • Amazon SageMaker AI (pipelines, lineage groups, Feature Store, Model Cards, Model Registry, JumpStart Hubs, Partner Apps, Catalog)
    • AWS Service Catalog AppRegistry
    • AWS Systems Manager (Incident Manager, Parameter Store advanced parameters, deny-access policies)
    • Amazon VPC (subnets, transit gateways, prefix lists, traffic mirroring targets, IPAM pools, IPAM resource discoveries, security groups)
    • Amazon VPC Lattice (services, service networks, resource configurations)
    • AWS Verified Access (groups)

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. A company has multiple AWS accounts managed by AWS Organizations. The networking team wants to share a set of VPC subnets with the development team’s accounts to allow them to launch resources in a shared VPC. Which approach requires the LEAST operational overhead?
      1. Create VPC peering connections between each account
      2. Use AWS Resource Access Manager to share the subnets with the development OU
      3. Use resource-based policies on each subnet to grant cross-account access
      4. Create duplicate VPCs in each development account

      Answer: b – RAM allows sharing subnets with an entire OU, eliminating the need to manage individual account IDs or duplicate resources.

    2. An organization is restructuring and moving AWS accounts between different AWS Organizations. They need to ensure shared resources remain accessible during the transition. Which RAM feature should they use?
      1. Customer managed permissions
      2. Service principal sharing
      3. RetainSharingOnAccountLeaveOrganization configuration
      4. Resource-based policies

      Answer: c – The RetainSharingOnAccountLeaveOrganization configuration (Feb 2026) maintains resource sharing continuity when accounts move between organizations.

    3. A security team wants to control exactly which actions a consumer account can perform on shared AWS Network Firewall rule groups. What should they use?
      1. AWS managed permissions in RAM
      2. Customer managed permissions in RAM
      3. IAM resource-based policies
      4. Service Control Policies (SCPs)

      Answer: b – Customer managed permissions in RAM allow fine-grained control over exactly which actions consumers can perform on shared resources.

    4. Which of the following resources can be shared using AWS RAM? (Select THREE)
      1. Amazon VPC security groups
      2. Amazon Bedrock custom models
      3. Amazon DynamoDB tables
      4. AWS CloudHSM backups
      5. Amazon SQS queues

      Answer: a, b, d – VPC security groups (Oct 2024), Bedrock custom models (Aug 2024), and CloudHSM backups (Jun 2024) are all shareable via RAM. DynamoDB tables and SQS queues are not supported.

    5. A company wants to share an Amazon VPC Lattice resource configuration representing an internal RDS database with another AWS account so it can be accessed privately via VPC endpoints. Which service facilitates this sharing?
      1. AWS PrivateLink directly
      2. VPC Peering
      3. AWS Resource Access Manager (RAM)
      4. AWS Transit Gateway

      Answer: c – VPC Lattice resource configurations are shared via AWS RAM. Once shared, the consumer can access the resource privately using VPC endpoints via PrivateLink.

    References

    AWS Elastic Map Reduce – EMR

    AWS EMR – Elastic MapReduce

    • Amazon EMR – Elastic MapReduce is a web service that utilizes a hosted Hadoop framework running on the web-scale infrastructure of EC2 and S3.
    • enables businesses, researchers, data analysts, and developers to easily and cost-effectively process vast amounts of data.
    • uses Apache Hadoop as its distributed data processing engine, which is an open-source, Java software that supports data-intensive distributed applications running on large clusters of commodity hardware
    • provides data processing, interactive analysis, and machine learning using open-source frameworks such as Apache Spark, Apache Hive, Presto/Trino, and Apache Flink.
    • is ideal for problems that necessitate fast and efficient processing of large amounts of data.
    • helps focus on crunching, transforming, and analyzing data without having to worry about time-consuming set-up, the management, or tuning of Hadoop clusters, the compute capacity, or open-source applications.
    • can help perform data-intensive tasks for applications such as web indexing, data mining, log file analysis, machine learning, financial analysis, scientific simulation, bioinformatics research, etc
    • provides web service interface to launch the clusters and monitor processing-intensive computation on clusters.
    • workloads can be deployed using EC2, Elastic Kubernetes Service (EKS), or on-premises AWS Outposts.
    • seamlessly supports On-Demand, Spot, and Reserved Instances.
    • EMR launches all nodes for a given cluster in the same AZ, which improves performance as it provides a higher data access rate.
    • EMR supports different EC2 instance types including Standard, High CPU, High Memory, Cluster Compute, High I/O, High Storage, and AWS Graviton-based instances for improved price-performance.
    • EMR pricing is per-second with a one-minute minimum charge per instance.
    • EMR integrates with CloudTrail to record AWS API calls
    • EMR features a performance-optimized runtime that is 100% API-compatible with open-source Apache Spark, executing up to 4.5x faster than open-source equivalents.
    • EMR supports building open, transactional data lakes with Apache Spark and Apache Iceberg, delivering 2.7x faster Iceberg write performance.
    • EMR Serverless helps run big data frameworks such as Apache Spark and Apache Hive without configuring, managing, and scaling clusters.
    • EMR Studio is an IDE that helps data scientists and data engineers to develop, visualize, and debug data engineering and data science applications written in R, Python, Scala, and PySpark.
    • EMR Notebooks are now available as EMR Studio Workspaces in the console. AWS recommends using EMR Studio instead.

    EMR Architecture

    • EMR uses industry-proven, fault-tolerant Hadoop software as its data processing engine.
    • Hadoop is an open-source, Java software that supports data-intensive distributed applications running on large clusters of commodity hardware
    • Hadoop splits the data into multiple subsets and assigns each subset to more than one EC2 instance. So, if an EC2 instance fails to process one subset of data, the results of another Amazon EC2 instance can be used.
    • EMR consists of Master node, one or more Slave nodes
      • Master Node Or Primary Node
        • Master node or Primary node manages the cluster by running software components to coordinate the distribution of data and tasks among other nodes for processing.
        • Primary node tracks the status of tasks and monitors the health of the cluster.
        • Every cluster has a primary node, and it’s possible to create a single-node cluster with only the primary node.
        • EMR supports multiple primary nodes (High Availability) to eliminate the single point of failure. If one primary node fails, Amazon EMR automatically fails over to a standby primary node and replaces the failed node with a new one.
        • Multi-primary node clusters are supported with EMR releases 5.36.1, 5.36.2, 6.8.1, 6.9.1, 6.10.1, 6.11.1, 6.12.0, and higher.
        • For single primary node clusters, if the master node goes down, the EMR cluster will be terminated and the job needs to be re-executed.
      • Slave Nodes – Core nodes and Task nodes
        • Core nodes
          • with software components that host persistent data using Hadoop Distributed File System (HDFS) and run Hadoop tasks
          • Multi-node clusters have at least one core node.
          • can be increased in an existing cluster
        • Task nodes
          • only run Hadoop tasks and do not store data in HDFS.
          • can be increased or decreased in an existing cluster.
        • EMR is fault tolerant for slave failures and continues job execution if a slave node goes down.
        • Currently, EMR does not automatically provision another node to take over failed slaves
    • EMR supports Bootstrap actions which allow
      • users a way to run custom set-up prior to the execution of the cluster.
      • can be used to install software or configure instances before running the cluster

    EMR Storage

    • Hadoop Distributed File System (HDFS)
      • HDFS is a distributed, scalable file system for Hadoop.
      • HDFS distributes the data it stores across instances in the cluster, storing multiple copies of data on different instances to ensure that no data is lost if an individual instance fails.
      • HDFS is ephemeral storage that is reclaimed when you terminate a cluster.
      • HDFS is useful for caching intermediate results during MapReduce processing or for workloads that have significant random I/O.
    • EMR File System – EMRFS
      • EMR File System (EMRFS) helps extend Hadoop to add the ability to directly access data stored in S3 as if it were a file system like HDFS.
      • You can use either HDFS or S3 as the file system in your cluster. Most often, S3 is used to store input and output data and intermediate results are stored in HDFS.
    • Local file system
      • Local file system refers to a locally connected EC2 pre-attached disk instance store storage.
      • Data on instance store volumes persists only during the lifecycle of its Amazon EC2 instance.
    • Storing data on S3 provides several benefits
      • inherent features high availability, durability, lifecycle management, data encryption, and archival of data to Glacier
      • cost-effective as storing data in S3 is cheaper as compared to HDFS with the replication factor
      • ability to use Transient EMR cluster and shutdown the clusters after the job is completed, with data being maintained in S3
      • ability to use Spot instances and not having to worry about losing the spot instances at any time.
      • provides data durability from any HDFS node failures, where node failures exceed the HDFS replication factor
      • data ingestion with high throughput data stream to S3 is much easier than ingesting to HDFS

    EMR Security

    • EMR cluster starts with different security groups for Master and Cluster nodes
      • Master security group
        • has a port open for communication with the service.
        • has an SSH port open to allow direct SSH into the instances, using the key specified at the startup.
      • Cluster security group
        • only allows interaction with the master instance
        • SSH to the slave nodes can be done by doing SSH to the master node and then to the slave node
      • Security groups can be configured with different access rules

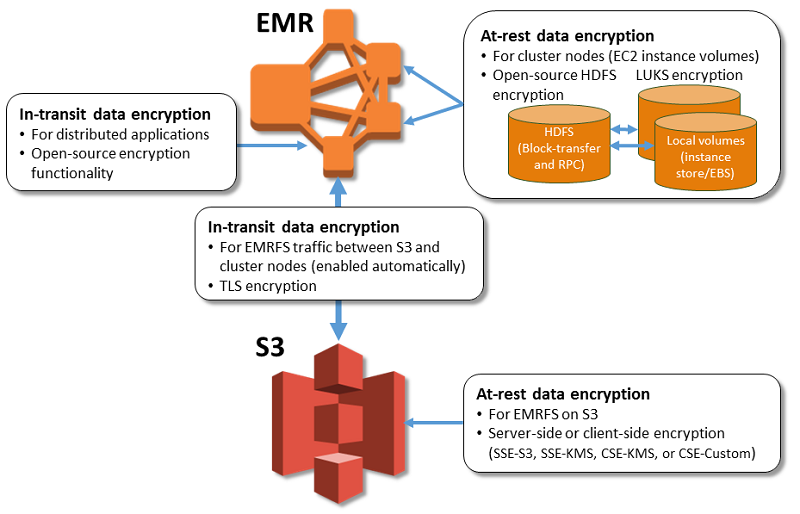
    EMR Security Encryption

    • EMR always uses HTTPS to send data between S3 and EC2.
    • EMR enables the use of security configuration
      • which helps to encrypt data at rest, data in transit, or both
      • can be used to specify settings for S3 encryption with EMR file system (EMRFS), local disk encryption, and in-transit encryption
      • is stored in EMR rather than the cluster configuration making it reusable
      • gives the flexibility to choose from several options, including keys managed by AWS KMS, keys managed by S3, and keys and certificates from custom providers that you supply.
    • At-rest Encryption for S3 with EMRFS
      • EMRFS supports Server-side (SSE-S3, SSE-KMS) and Client-side encryption (CSE-KMS or CSE-Custom)
      • S3 SSE and CSE encryption with EMRFS are mutually exclusive; either one can be selected but not both
      • Transport layer security (TLS) encrypts EMRFS objects in-transit between EMR cluster nodes & S3
    • At-rest Encryption for Local Disks
      • Open-source HDFS Encryption
        • HDFS exchanges data between cluster instances during distributed processing, and also reads from and writes data to instance store volumes and the EBS volumes attached to instances
        • Open-source Hadoop encryption options are activated
          • Secure Hadoop RPC is set to “Privacy”, which uses Simple Authentication Security Layer (SASL).
          • Data encryption on HDFS block data transfer is set to true and is configured to use AES 256 encryption.
      • EBS Volume Encryption
        • EBS Encryption
          • EBS encryption option encrypts the EBS root device volume and attached storage volumes.
          • EBS encryption option is available only when you specify AWS KMS as your key provider.
        • LUKS
          • EC2 instance store volumes (except boot/root volumes) and the attached EBS volumes can be encrypted using LUKS.
    • In-Transit Data Encryption
      • Encryption artifacts used for in-transit encryption in one of two ways:
        • either by providing a zipped file of certificates that you upload to S3,
        • or by referencing a custom Java class that provides encryption artifacts
    • EMR block public access prevents a cluster in a public subnet from launching when any security group associated with the cluster has a rule that allows inbound traffic from anywhere (public access) on a port, unless the port has been specified as an exception.
    • EMR Runtime Roles help manage access control for each job or query individually, instead of sharing the EMR instance profile of the cluster.
    • EMR IAM service roles help perform actions on your behalf when provisioning cluster resources, running applications, dynamically scaling resources, and creating and running EMR Notebooks.
    • SSH clients can use an EC2 key pair or Kerberos to authenticate to cluster instances.
    • Lake Formation based access control can be applied to Spark, Hive, and Presto jobs that you submit to the EMR clusters.
    • Lake Formation supports table, row, column, and cell-level access control with Apache Iceberg on EMR.

    EMR Cluster Types

    • EMR has two cluster types, transient and persistent
    • Transient EMR Clusters
      • Transient EMR clusters are clusters that shut down when the job or the steps (series of jobs) are complete
      • Transient EMR clusters can be used in situations
        • where total number of EMR processing hours per day < 24 hours and its beneficial to shut down the cluster when it’s not being used.
        • using HDFS as your primary data storage.
        • job processing is intensive, iterative data processing.
    • Persistent EMR Clusters
      • Persistent EMR clusters continue to run after the data processing job is complete
      • Persistent EMR clusters can be used in situations
        • frequently run processing jobs where it’s beneficial to keep the cluster running after the previous job.
        • processing jobs have an input-output dependency on one another.
        • In rare cases when it is more cost effective to store the data on HDFS instead of S3

    EMR Managed Scaling

    • EMR Managed Scaling automatically increases or decreases the number of instances or units in a cluster based on workload.
    • EMR continuously evaluates cluster metrics to make scaling decisions that optimize clusters for cost and speed.
    • Available with EMR version 5.30.0 and higher (except 6.0.0).
    • Managed scaling only works with YARN applications such as Spark, Hadoop, Hive, and Flink. It does not support applications that are not based on YARN, such as Presto and HBase.
    • Managed Scaling Parameters:
      • Minimum (MinimumCapacityUnits) – Lower boundary of allowed EC2 capacity.
      • Maximum (MaximumCapacityUnits) – Upper boundary of allowed EC2 capacity.
      • On-Demand limit (MaximumOnDemandCapacityUnits) – Upper boundary for On-Demand market type; splits allocation between On-Demand and Spot.
      • Maximum core nodes (MaximumCoreCapacityUnits) – Upper boundary for core node type; splits allocation between core and task nodes.
    • Advanced Scaling (November 2024) provides a utilization-performance slider (values: 1, 25, 50, 75, 100) to configure desired resource utilization or performance levels.
      • Setting a higher value optimizes for performance.
      • Setting a lower value optimizes for resource conservation.
      • Setting value to 50 balances performance and resource conservation.
    • Managed scaling supports Node Labels (EMR 7.2.0+) allowing instances to be labeled by market type (ON_DEMAND, SPOT) or node type (CORE, TASK) for improved scaling decisions.
    • Managed scaling is Spark shuffle data aware – only scales down under-utilized instances that don’t contain actively used shuffle data.

    EMR Instance Fleets

    • Instance fleets provide a flexible approach to provisioning EC2 instances, allowing specification of up to 30 EC2 instance types per node type (via CLI/API) with allocation strategies.
    • Instance fleets automatically manage the mix of instance types to meet specified target capacities for On-Demand and Spot.
    • Allows selection of multiple subnets for different Availability Zones, enabling Amazon EMR to optimally launch clusters.
    • On-Demand Allocation Strategies:
      • Prioritized – Define a priority order for instance types for precise control.
      • Lowest-price – Selects the lowest-priced instance type from available options.
    • Spot Allocation Strategies:
      • Price-capacity optimized – Selects instances with lowest price while considering available capacity.
      • Capacity-optimized-prioritized – Respects instance type priorities on a best-effort basis.
      • Capacity-optimized – Selects instances from the most available capacity pools.
      • Lowest-price – Selects the lowest-priced Spot Instances.
      • Diversified – Distributes instances across all pools.
    • Enhanced Subnet Selection reduces cluster launch failures from IP address shortage by evaluating available IPs across subnets to select the optimal subnet for launching all instance fleets.
    • High Availability Instance Fleets combines multi-primary node HA architecture with instance fleet flexibility for long-running clusters.

    EMR Serverless

    • EMR Serverless helps run big data frameworks such as Apache Spark and Apache Hive without configuring, managing, and scaling clusters.
    • currently supports Apache Spark and Apache Hive engines.
    • automatically determines the resources that the application needs and gets these resources to process the jobs, and releases the resources when the jobs finish.
    • minimum and maximum number of concurrent workers and the vCPU and memory configuration for workers can be specified.
    • supports multiple AZs and provides resilience to AZ failures.
    • An EMR Serverless application internally uses workers to execute your workloads and it offers two options for workers
      • On-demand workers
        • are launched only when needed for a job and are released automatically when the job is complete.
        • scales the application up or down based on the workload, so you don’t have to worry about over- or under-provisioning resources.
        • takes up to 120 seconds to determine the required resources and provision them.
        • distributes jobs across multiple AZs by default, but each job runs only in one AZ.
        • automatically runs your job in another healthy AZ, if an AZ fails.
      • Pre-initialized workers
        • are an optional feature where you can keep workers ready to respond in seconds.
        • It effectively creates a warm pool of workers for an application which allows jobs to start instantly, making it ideal for iterative applications and time-sensitive jobs.
        • submits job in a healthy AZ from the specified subnets. Application needs to be restarted to switch to another healthy AZ, if an AZ becomes impaired.
    • Serverless Storage (re:Invent 2025)
      • Eliminates the need to configure local disks for Apache Spark workloads.
      • Stores intermediate data in fully managed serverless storage that scales automatically.
      • Enables Spark to release compute workers immediately when idle, reducing compute costs by up to 20%.
      • Eliminates job failures from disk capacity constraints.
    • Streaming Jobs (June 2024)
      • Supports continuous processing on streaming data with built-in job resiliency.
      • Provides real-time monitoring, enhanced log management, and integration with streaming connectors.
    • Spark Connect on EMR Serverless (May 2026)
      • Supports interactive sessions enabling development and running of Apache Spark applications from managed notebooks in Amazon SageMaker Unified Studio, Jupyter, and VS Code.
      • Each Spark Connect session has its own AWS resource with a unique ARN, enabling per-session IAM permissions, tag-based cost allocation, and audit through CloudTrail.

    EMR Studio

    • EMR Studio is an IDE that helps data scientists and data engineers to develop, visualize, and debug data engineering and data science applications written in R, Python, Scala, and PySpark.
    • is a fully managed application with single sign-on, fully managed Jupyter Notebooks, automated infrastructure provisioning, and the ability to debug jobs without logging into the AWS Console or cluster.
    • supports AWS IAM Authentication from the console or federated access from your identity provider (IdP) via AWS IAM Identity Center.
    • supports interactive analytics on Amazon EMR Serverless (from release 6.14), allowing EMR Serverless applications as compute in addition to EMR on EC2 and EMR on EKS.
    • EMR Studio is integrated with Amazon SageMaker Unified Studio, providing a unified data and compute experience for analytics workflows.

    EMR Notebooks

    • EMR Notebooks provide a managed environment, based on Jupyter Notebook, that allows data scientists, analysts, and developers to prepare and visualize data, collaborate with peers, build applications, and perform interactive analysis using EMR clusters.
    • EMR Notebooks are now available as EMR Studio Workspaces in the console. AWS recommends using EMR Studio instead of EMR Notebooks. The option to create new notebooks in the old EMR console has been turned off.
    • Users can create serverless notebooks directly from the console, attach them to an existing shared EMR cluster, or provision a cluster directly from the console and build Spark applications and run interactive queries.
    • Notebooks are auto-saved to S3 buckets, and can be retrieved from the console to resume work.
    • Notebooks can be detached and attached to new clusters.
    • Notebooks are prepackaged with the libraries found in the Anaconda repository, allowing you to import and use these libraries in the notebooks code and use them to manipulate data and visualize results.

    EMR with Apache Iceberg

    • Amazon EMR natively supports Apache Iceberg from version 6.5.0 and later, enabling open, transactional data lakes on S3.
    • Apache Iceberg provides ACID transactions, schema evolution, time travel, and partition evolution for data lake tables.
    • Apache Iceberg v3 (EMR 7.12+, November 2025) introduces:
      • Deletion Vectors – Optimized delete files that speed up data pipelines and reduce data compaction costs.
      • Row Lineage – Better tracking for row-level changes, strengthening governance and compliance.
      • More granular data access control for enhanced data security.
    • EMR delivers 2.7x faster Iceberg write performance compared to open-source equivalents.
    • Supports table, row, column, and cell-level access control with Apache Iceberg through AWS Lake Formation.
    • Fine-grained access control using Lake Formation is available for EMR on EKS from EMR 7.7 and higher.

    Apache Spark 4.0 on EMR

    • Apache Spark 4.0.2 is generally available on Amazon EMR (May 2026) across EMR Serverless, EMR on EC2, and EMR on EKS.
    • Key features of Spark 4.0 on EMR:
      • VARIANT data type – Native support for semi-structured JSON data handling without complex parsing.
      • ANSI SQL compliance – Standard SQL support eliminating the need for Spark-specific syntax.
      • Apache Iceberg v3 table format – Native support for the latest Iceberg capabilities.
      • Spark Connect – Decoupled architecture allowing interactive development from local IDEs while using EMR for execution.
      • transformWithState API – Enables building stateful streaming applications in a serverless environment.
    • EMR optimized runtime runs Spark 4.0 workloads up to 4.5x faster than open-source Apache Spark.
    • Apache Spark Upgrade Agent (re:Invent 2025)
      • AI-powered agent that accelerates Spark version upgrades through automated code analysis and transformation.
      • Works directly within your IDE, analyzing code, applying fixes, and validating results.
      • Supports PySpark and Scala applications on EMR on EC2 and EMR Serverless.
      • Converts complex upgrade processes that typically take months into weeks.
      • Includes data quality validation to detect schema differences and value-level statistical drifts.

    EMR on EKS

    • Amazon EMR on EKS is a deployment option that allows running open-source big data frameworks such as Apache Spark and Apache Flink on Amazon Elastic Kubernetes Service (EKS) clusters with the EMR runtime.
    • Provides the same EMR benefits (managed versions of Spark, automatic provisioning, performance-optimized runtime) on EKS that are available on EC2.
    • Supports Apache Flink on EKS (GA June 2024) for scalable, reliable stream processing.
    • Supports fine-grained access control for Iceberg tables using Lake Formation integration (EMR 7.7+).
    • Available as EMR on EKS release 7.9.0 (latest as of 2025).
    • Integrated with Amazon SageMaker Unified Studio for unified analytics workflows.

    EMR Release Lifecycle and Support

    • 24-Month Standard Support (July 2024) – Each Amazon EMR release receives 24 months of standard support including fixes for critical security, bugs, and data corruption issues.
    • After standard support ends, releases enter end-of-support where no further patches are provided.
    • Amazon EMR 3.10 and lower cannot create new clusters (since December 2023).
    • AWS strongly recommends using the latest EMR release (EMR 7.13.0 as of 2026) for all new clusters.
    • Managed Policies v2 – EMR is deprecating existing managed policies (v1) in favor of scoped-down v2 policies aligned with AWS best practices.

    EMR Best Practices

    • Data Migration
      • Two tools – S3DistCp and DistCp – can be used to move data stored on the local (data center) HDFS storage to S3, from S3 to HDFS and between S3 and local disk (non HDFS) to S3
      • AWS Direct Connect can also be considered for moving data with consistent bandwidth and reduced latency for large-scale transfers.
    • Data Collection
      • Apache Flume is a distributed, reliable, and available service for efficiently collecting, aggregating, & moving large amounts of log data
      • Flume agents can be installed on the data sources (web-servers, app servers etc) and data shipped to the collectors which can then be stored in persistent storage like S3 or HDFS
    • Data Aggregation
      • Data aggregation refers to techniques for gathering individual data records (for e.g. log records) and combining them into a large bundle of data files i.e. creating a large file from small files
      • Hadoop, on which EMR runs, generally performs better with fewer large files compared to many small files
      • Hadoop splits the file on HDFS on multiple nodes, while for the data in S3 it uses the HTTP Range header query to split the files which helps improve performance by supporting parallelization
      • Log collectors like Flume and Fluentd can be used to aggregate data before copying it to the final destination (S3 or HDFS)
      • Data aggregation has following benefits
        • Improves data ingest scalability by reducing the number of times needed to upload data to AWS
        • Reduces the number of files stored on S3 (or HDFS), which inherently helps provide better performance when processing data
        • Provides a better compression ratio as compressing large, highly compressible files is often more effective than compressing a large number of smaller files.
    • Data compression
      • Data compression can be used at the input as well as intermediate outputs from the mappers
      • Data compression helps
        • Lower storage costs
        • Lower bandwidth cost for data transfer
        • Better data processing performance by moving less data between data storage location, mappers, and reducers
        • Better data processing performance by compressing the data that EMR writes to disk, i.e. achieving better performance by writing to disk less frequently
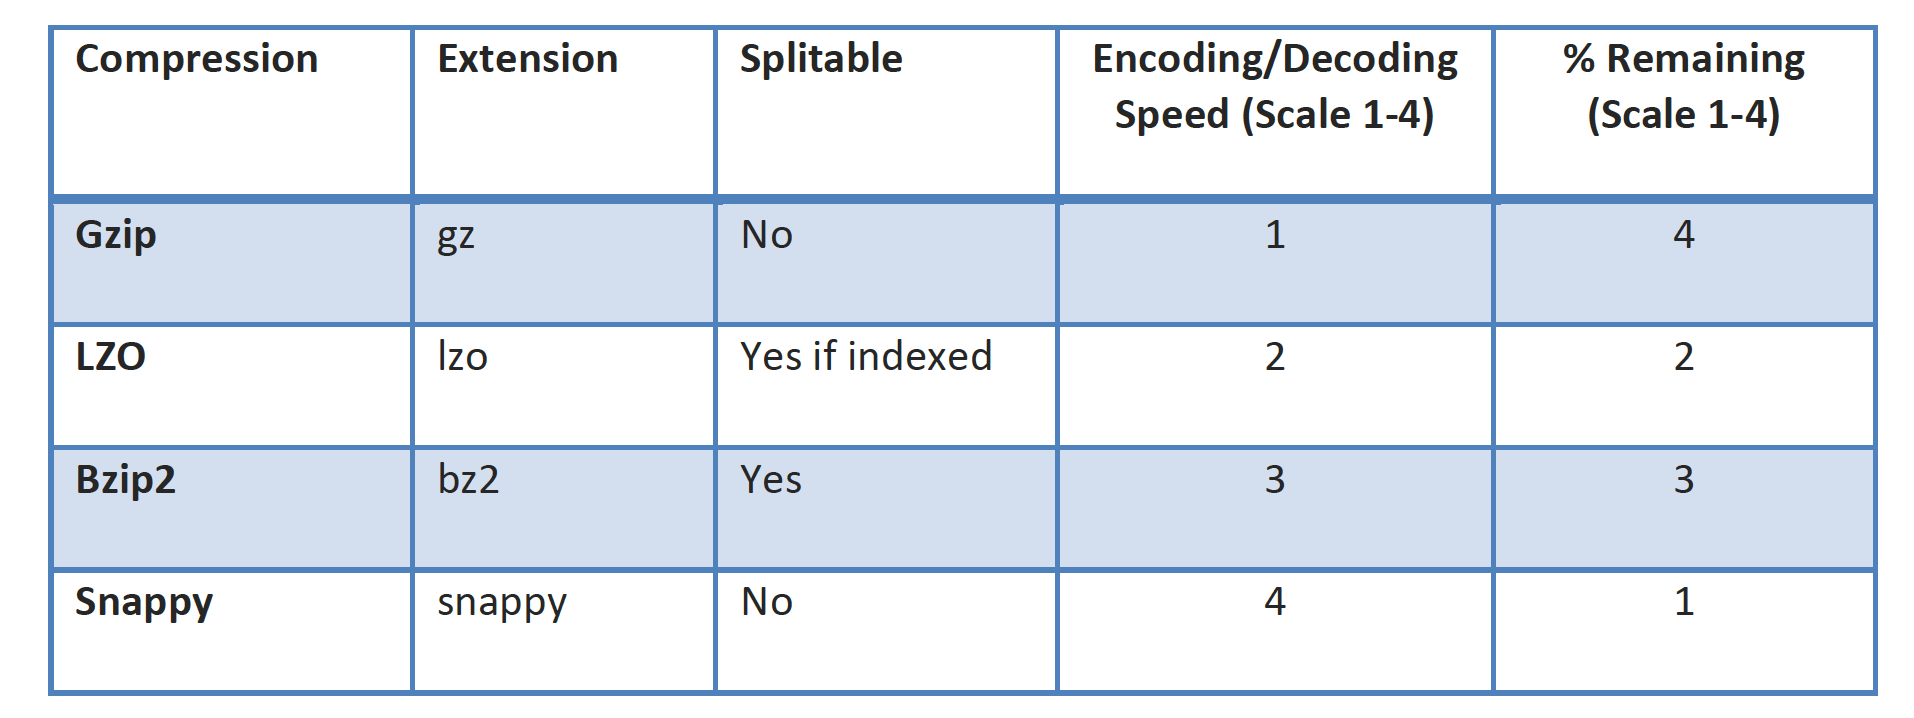
      • Data Compression can have an impact on Hadoop data splitting logic as some of the compression techniques like gzip do not support it
      • Data Compression Techniques
    • Data Partitioning
      • Data partitioning helps in data optimizations and lets you create unique buckets of data and eliminate the need for a data processing job to read the entire data set
      • Data can be partitioned by
        • Data type (time series)
        • Data processing frequency (per hour, per day, etc.)
        • Data access and query pattern (query on time vs. query on geo location)
    • Cost Optimization
      • AWS offers different pricing models for EC2 instances
        • On-Demand instances
          • are a good option if using transient EMR jobs or if the EMR hourly usage is less than 17% of the time
        • Reserved instances
          • are a good option for persistent EMR cluster or if the EMR hourly usage is more than 17% of the time as is more cost effective
        • Spot instances
          • can be a cost effective mechanism to add compute capacity (up to 90% discount vs On-Demand)
          • can be used where the data persists on S3
          • can be used to add extra task capacity with Task nodes
          • is not suited for Master node, as if it is lost the cluster is lost and Core nodes (data nodes) as they host data and if lost needs to be recovered to rebalance the HDFS cluster
          • less than 5% of Spot workloads are interrupted (with a two-minute warning)
      • Architecture pattern can be used,
        • Run master node on On-Demand or Reserved Instances (if running persistent EMR clusters).
        • Run a portion of the EMR cluster on core nodes using On-Demand or Reserved Instances and
        • the rest of the cluster on task nodes using Spot Instances.
      • Use Graviton-based instances (e.g., m7g, c7g, r7g, r8g) for improved price-performance.
      • Use Instance Fleets with allocation strategies for optimal capacity and cost management.
      • Use EMR Managed Scaling to automatically right-size clusters.
      • Consider EMR Serverless for variable workloads to pay only for resources used.

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. You require the ability to analyze a large amount of data, which is stored on Amazon S3 using Amazon Elastic Map Reduce. You are using the cc2.8xlarge instance type, who’s CPUs are mostly idle during processing. Which of the below would be the most cost efficient way to reduce the runtime of the job? [PROFESSIONAL]
      1. Create smaller files on Amazon S3.
      2. Add additional cc2.8xlarge instances by introducing a task group.
      3. Use smaller instances that have higher aggregate I/O performance.
      4. Create fewer, larger files on Amazon S3.
    2. A customer’s nightly EMR job processes a single 2-TB data file stored on Amazon Simple Storage Service (S3). The Amazon Elastic Map Reduce (EMR) job runs on two On-Demand core nodes and three On-Demand task nodes. Which of the following may help reduce the EMR job completion time? Choose 2 answers
      1. Use three Spot Instances rather than three On-Demand instances for the task nodes.
      2. Change the input split size in the MapReduce job configuration.
      3. Use a bootstrap action to present the S3 bucket as a local filesystem.
      4. Launch the core nodes and task nodes within an Amazon Virtual Cloud.
      5. Adjust the number of simultaneous mapper tasks.
      6. Enable termination protection for the job flow.
    3. Your department creates regular analytics reports from your company’s log files. All log data is collected in Amazon S3 and processed by daily Amazon Elastic Map Reduce (EMR) jobs that generate daily PDF reports and aggregated tables in CSV format for an Amazon Redshift data warehouse. Your CFO requests that you optimize the cost structure for this system. Which of the following alternatives will lower costs without compromising average performance of the system or data integrity for the raw data? [PROFESSIONAL]
      1. Use reduced redundancy storage (RRS) for PDF and CSV data in Amazon S3. Add Spot instances to Amazon EMR jobs. Use Reserved Instances for Amazon Redshift. (Only Spot instances impacts performance)
      2. Use reduced redundancy storage (RRS) for all data in S3. Use a combination of Spot instances and Reserved Instances for Amazon EMR jobs. Use Reserved instances for Amazon Redshift (Combination of the Spot and reserved with guarantee performance and help reduce cost. Also, RRS would reduce cost and guarantee data integrity, which is different from data durability)
      3. Use reduced redundancy storage (RRS) for all data in Amazon S3. Add Spot Instances to Amazon EMR jobs. Use Reserved Instances for Amazon Redshift (Only Spot instances impacts performance)
      4. Use reduced redundancy storage (RRS) for PDF and CSV data in S3. Add Spot Instances to EMR jobs. Use Spot Instances for Amazon Redshift. (Spot instances impacts performance and Spot instance not available for Redshift)
    4. A research scientist is planning for the one-time launch of an Elastic MapReduce cluster and is encouraged by her manager to minimize the costs. The cluster is designed to ingest 200TB of genomics data with a total of 100 Amazon EC2 instances and is expected to run for around four hours. The resulting data set must be stored temporarily until archived into an Amazon RDS Oracle instance. Which option will help save the most money while meeting requirements? [PROFESSIONAL]
      1. Store ingest and output files in Amazon S3. Deploy on-demand for the master and core nodes and spot for the task nodes.
      2. Optimize by deploying a combination of on-demand, RI and spot-pricing models for the master, core and task nodes. Store ingest and output files in Amazon S3 with a lifecycle policy that archives them to Amazon Glacier. (Master and Core must be RI or On Demand. Cannot be Spot)
      3. Store the ingest files in Amazon S3 RRS and store the output files in S3. Deploy Reserved Instances for the master and core nodes and on-demand for the task nodes. (Need better durability for ingest file. Spot instances can be used for task nodes for cost saving. RI will not provide cost saving in this case)
      4. Deploy on-demand master, core and task nodes and store ingest and output files in Amazon S3 RRS (Input should be in S3 standard, as re-ingesting the input data might end up being more costly then holding the data for limited time in standard S3)
    5. Your company sells consumer devices and needs to record the first activation of all sold devices. Devices are not activated until the information is written on a persistent database. Activation data is very important for your company and must be analyzed daily with a MapReduce job. The execution time of the data analysis process must be less than three hours per day. Devices are usually sold evenly during the year, but when a new device model is out, there is a predictable peak in activation’s, that is, for a few days there are 10 times or even 100 times more activation’s than in average day. Which of the following databases and analysis framework would you implement to better optimize costs and performance for this workload? [PROFESSIONAL]
      1. Amazon RDS and Amazon Elastic MapReduce with Spot instances.
      2. Amazon DynamoDB and Amazon Elastic MapReduce with Spot instances.
      3. Amazon RDS and Amazon Elastic MapReduce with Reserved instances.
      4. Amazon DynamoDB and Amazon Elastic MapReduce with Reserved instances
    6. A company runs daily ETL jobs on an EMR cluster processing data stored in S3. The cluster uses a single primary node and frequently fails during peak processing. The team wants to improve cluster resilience while maintaining cost efficiency. Which combination of actions should they take? (Choose 2)
      1. Enable multiple primary nodes for high availability to eliminate the single point of failure.
      2. Move all data from S3 to HDFS for faster processing.
      3. Use instance fleets with the capacity-optimized allocation strategy for Spot task nodes.
      4. Use a single large instance type for all nodes to simplify management.
      5. Disable managed scaling to prevent automatic changes during processing.
    7. A data engineering team needs to run Apache Spark jobs that vary significantly in resource requirements throughout the day. They want to minimize costs while ensuring jobs complete within SLA. Which EMR deployment option best meets these requirements?
      1. EMR on EC2 with Reserved Instances for all nodes.
      2. EMR on EC2 with On-Demand Instances and manual scaling.
      3. EMR Serverless, which automatically provisions and releases resources based on workload demands.
      4. EMR on EKS with a fixed number of pods.
    8. A company wants to build an open data lakehouse using Apache Iceberg on Amazon EMR. They need ACID transactions, time travel queries, and the ability to efficiently handle record-level deletes on petabyte-scale data. Which EMR configuration best supports these requirements?
      1. EMR 6.5.0 with Iceberg v1 using copy-on-write tables.
      2. EMR 7.6.0 with Iceberg v2 using merge-on-read tables.
      3. EMR 7.12+ with Iceberg v3 using deletion vectors for efficient deletes and row lineage for tracking.
      4. EMR Serverless without Iceberg, using S3 versioning for time travel.

    References

    Amazon S3 Replication – CRR & SRR Configuration

    S3 Replication

    Amazon S3 Replication

    • S3 Replication enables automatic, asynchronous copying of objects across S3 buckets in the same or different AWS regions.
    • S3 Replication supports two types:
      • Live Replication – automatically replicates new and updated objects as they are written to the source bucket.
      • On-Demand Replication (Batch Replication) – replicates existing objects from the source bucket to destination buckets on demand.
    • S3 Cross-Region Replication (CRR) is used to copy objects across S3 buckets in different AWS Regions.
    • S3 Same-Region Replication (SRR) is used to copy objects across S3 buckets in the same AWS Region.
    • S3 Replication supports two-way (bidirectional) replication between two or more buckets in the same or different AWS Regions.
    • S3 Replication helps to
      • Replicate objects while retaining metadata (creation time, version IDs, ACLs)
      • Replicate objects into different storage classes (including S3 Glacier, Deep Archive)
      • Maintain object copies under different ownership (owner override option)
      • Keep objects stored over multiple AWS Regions
      • Replicate objects within 15 minutes (with S3 Replication Time Control)
      • Sync buckets, replicate existing objects, and retry previously failed replications (with Batch Replication)
      • Replicate objects and fail over to a bucket in another AWS Region (with Multi-Region Access Points)
    • S3 can replicate all or a subset of objects with specific key name prefixes or object tags
    • S3 encrypts all data in transit across AWS regions using SSL
    • Object replicas in the destination bucket are exact replicas of the objects in the source bucket with the same key names and the same metadata.
    • Objects may be replicated to a single destination bucket or multiple destination buckets.
    • Cross-Region Replication can be useful for the following scenarios:-
      • Compliance requirement to have data backed up across regions
      • Minimize latency to allow users across geography to access objects
      • Operational reasons compute clusters in two different regions that analyze the same set of objects
    • Same-Region Replication can be useful for the following scenarios:-
      • Aggregate logs into a single bucket
      • Configure live replication between production and test accounts
      • Abide by data sovereignty laws to store multiple copies

    S3 Replication

    S3 Replication Requirements

    • Source and destination buckets must be versioning-enabled
    • For CRR, the source and destination buckets must be in different AWS Regions.
    • The source bucket owner must have the source and destination AWS Regions enabled for their account. The destination bucket owner must have the destination Region enabled for their account.
    • S3 must have permission to replicate objects from that source bucket to the destination bucket on your behalf.
    • If the source bucket owner also owns the object, the bucket owner has full permission to replicate the object. If not, the object owner must grant the bucket owner READ and READ_ACP permissions with the object ACL.
    • Setting up cross-region replication in a cross-account scenario (where the source and destination buckets are owned by different AWS accounts), the destination bucket owner must grant the source bucket owner permissions to replicate objects with a bucket policy.
    • If the source bucket has S3 Object Lock enabled, the destination buckets must also have S3 Object Lock enabled. Additional permissions s3:GetObjectRetention and s3:GetObjectLegalHold are required on the IAM role.
    • Destination buckets cannot be configured as Requester Pays buckets.

    S3 Batch Replication

    • S3 Batch Replication allows you to replicate existing objects to different buckets as an on-demand operation.
    • Live replication (CRR/SRR) only replicates new objects created after the replication rule is configured. Batch Replication addresses the gap for pre-existing objects.
    • Use cases for Batch Replication:
      • Backfill newly created buckets with existing objects from another bucket
      • Retry failed replications – replicate objects with a replication status of FAILED
      • Migrate data across accounts while preserving metadata and version IDs
      • Add new buckets to your data lake by replicating existing objects to new destinations
      • Replicate replicas – replicate objects that were created by another replication rule (not possible with live replication)
    • Batch Replication uses S3 Batch Operations jobs and provides a completion report when finished.
    • S3 RTC does not apply to Batch Replication; it is tracked via S3 Batch Operations.

    S3 Replication Time Control (S3 RTC)

    • S3 Replication Time Control (RTC) provides a predictable replication time backed by a Service Level Agreement (SLA).
    • S3 RTC replicates 99.99% of new objects within 15 minutes after upload, with the majority replicated in seconds.
    • S3 RTC is backed by an SLA with a commitment to replicate 99.9% of objects within 15 minutes during any billing month.
    • S3 RTC, by default, includes S3 Replication Metrics and S3 Event Notifications.
    • S3 RTC is available in all AWS Regions including AWS GovCloud (US) Regions.
    • Delete marker replication does not adhere to the 15-minute SLA granted by S3 RTC.

    S3 Two-Way Replication (Bidirectional)

    • S3 Replication supports two-way (bidirectional) replication between two or more buckets in the same or different AWS Regions.
    • Replica Modification Sync enables replicating metadata changes (ACLs, object tags, Object Lock settings) made to replica objects back to the source.
    • Replica Modification Sync must be enabled on both buckets for bidirectional metadata synchronization.
    • Two-way replication is essential for:
      • Building shared datasets across multiple AWS Regions
      • Keeping data synchronized during failover with S3 Multi-Region Access Points
      • Making applications highly available even during Regional traffic disruptions
    • To set up two-way replication, create replication rules in both directions between the source and destination buckets.

    S3 Multi-Region Access Points with Replication

    • S3 Multi-Region Access Points provide a single global endpoint that routes S3 requests to the bucket closest to the requester.
    • Multi-Region Access Points include failover controls to shift S3 data request traffic between AWS Regions within minutes.
    • Supports active-active and active-passive configurations:
      • Active-Active – Traffic is distributed to multiple active Regions. If disruption occurs, traffic is automatically redirected.
      • Active-Passive – An active Region services all requests; a passive Region is on standby for failover.
    • Multi-Region Access Points require Cross-Region Replication (CRR) to be configured so that objects are available regardless of which bucket receives the request.
    • Two-way replication rules should be configured with Multi-Region Access Points to keep all objects and metadata in sync during failover.
    • Multi-Region Access Points accelerate performance by routing requests via AWS Global Accelerator, reducing latency by up to 60%.

    S3 Replication Metrics and Notifications

    • S3 Replication provides detailed metrics and notifications to monitor replication status between buckets.
    • Replication metrics available in S3 console and Amazon CloudWatch:
      • Bytes Pending – total size of objects pending replication
      • Operations Pending – total number of operations pending replication
      • Replication Latency – maximum time to replicate
      • Operations Failed Replication – per-minute count of objects that failed to replicate
    • S3 Replication metrics are automatically enabled with S3 Replication Time Control (RTC).
    • S3 Event Notifications provide replication events:
      • s3:Replication:OperationFailedReplication
      • s3:Replication:OperationMissedThreshold
      • s3:Replication:OperationReplicatedAfterThreshold
      • s3:Replication:OperationNotTracked
    • Failure notifications do NOT require S3 RTC to be enabled.
    • Notifications can be sent to Amazon SNS, Amazon SQS, or AWS Lambda to diagnose configuration issues.

    S3 Replication – Replicated & Not Replicated

    • Only new objects created after you add a replication configuration are replicated by live replication. Use S3 Batch Replication to replicate existing objects.
    • Objects encrypted using:
      • SSE-S3 (S3 managed keys) – replicated by default
      • SSE-KMS (AWS KMS keys) – replicated when the replication rule is configured with KMS key specification
      • DSSE-KMS (Dual-layer server-side encryption) – supported for replication
      • SSE-C (Customer-provided keys) – supported for replication (added October 2022)
    • S3 replicates only objects in the source bucket for which the bucket owner has permission to read objects and read ACLs.
    • Any object ACL updates are replicated, although there can be some delay before S3 can bring the two in sync.
    • S3 does NOT replicate objects in the source bucket for which the bucket owner does not have permission.
    • Updates to bucket-level S3 subresources are NOT replicated, allowing different bucket configurations on the source and destination buckets.
    • Only customer actions are replicated & actions performed by lifecycle configuration are NOT replicated.
    • Replication chaining is NOT allowed – objects that are replicas created by another replication rule are NOT replicated by live replication. Use Batch Replication to replicate replicas.
    • S3 does NOT replicate the delete marker by default. However, you can enable delete marker replication in non-tag-based rules to replicate delete markers.
      • Delete marker replication is NOT supported for tag-based replication rules.
      • Delete markers added by S3 Lifecycle expiration rules are NOT replicated even with delete marker replication enabled.
    • S3 does NOT replicate deletion by object version ID. This protects data from malicious deletions.

    S3 Replication with Encryption

    • Starting January 5, 2023, Amazon S3 applies server-side encryption with S3 managed keys (SSE-S3) as the base level of encryption for every bucket.
    • SSE-S3 encrypted objects are replicated by default with no additional configuration.
    • SSE-KMS encrypted objects require specifying the destination KMS key in the replication rule. The IAM role must have kms:Decrypt permission on the source key and kms:Encrypt on the destination key.
    • DSSE-KMS (dual-layer encryption with KMS keys) is supported for replication.
    • SSE-C encrypted objects are supported for replication since October 2022. S3 automatically replicates newly uploaded SSE-C objects if eligible per replication configuration.
    • Note: Starting April 2026, SSE-C is disabled by default on all new S3 general purpose buckets. Applications requiring SSE-C must explicitly enable it via the PutBucketEncryption API.

    S3 on Outposts Replication

    • S3 Replication on AWS Outposts enables automatic replication of S3 objects across different Outposts or between buckets on the same Outpost.
    • Available at no additional cost in all AWS Regions where AWS Outposts racks are available (since March 2023).
    • Helps meet local data residency requirements while providing data redundancy.
    • S3 on Outposts does NOT support replicating delete markers for tag-based rules.
    • Existing Object Replication is NOT supported for S3 on Outposts buckets.

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. A company needs to replicate millions of existing objects from a source S3 bucket to a new destination bucket in another region. They also need to replicate any new objects going forward. What combination of features should they use?
      1. Enable Cross-Region Replication for new objects and use S3 Batch Replication for existing objects
      2. Use S3 Batch Replication only, as it handles both existing and new objects
      3. Enable Cross-Region Replication with Replication Time Control
      4. Use AWS DataSync to copy existing objects and CRR for new objects
      Show Answer

      Answer: a – CRR handles new objects automatically, while Batch Replication is the managed way to replicate existing objects on demand.

    2. A company requires that all replicated objects arrive at the destination bucket within 15 minutes and needs an SLA guarantee. Which feature should they enable?
      1. S3 Cross-Region Replication with Transfer Acceleration
      2. S3 Replication Time Control (S3 RTC)
      3. S3 Same-Region Replication with CloudWatch alarms
      4. S3 Multi-Region Access Points
      Show Answer

      Answer: b – S3 RTC replicates 99.99% of objects within 15 minutes and is backed by an SLA guaranteeing 99.9% within 15 minutes.

    3. A company wants to build a highly available multi-region application using S3. They need automatic failover of S3 data requests if a region becomes unavailable. What should they configure?
      1. CRR with CloudFront distribution
      2. S3 Multi-Region Access Points with two-way replication and failover controls
      3. SRR with Route 53 failover routing
      4. S3 Batch Operations with Lambda triggers
      Show Answer

      Answer: b – S3 Multi-Region Access Points with failover controls and two-way CRR provide a single global endpoint with the ability to shift traffic between regions.

    4. Which of the following statements about S3 Replication are correct? (Choose 3)
      1. Live replication automatically replicates objects that existed before the replication rule was configured
      2. Versioning must be enabled on both source and destination buckets
      3. S3 Batch Replication can replicate replicas that were created by another replication rule
      4. Delete markers are replicated by default
      5. SSE-C encrypted objects are supported for replication
      Show Answer

      Answer: b, c, e – Live replication does NOT replicate pre-existing objects (a is wrong). Delete markers are NOT replicated by default (d is wrong). Versioning is required, Batch Replication can replicate replicas, and SSE-C is supported since October 2022.

    5. A company uses two-way replication between two S3 buckets. They want metadata changes (ACLs and tags) made to replica objects to be synchronized back to the source. What must they enable?
      1. S3 Replication Time Control on both buckets
      2. Replica Modification Sync on both buckets
      3. S3 Batch Replication with metadata preservation
      4. S3 Object Lock on both buckets
      Show Answer

      Answer: b – Replica Modification Sync must be enabled on both buckets to replicate metadata changes (ACLs, tags, Object Lock settings) bidirectionally.

    6. Which S3 Replication metrics can be monitored via Amazon CloudWatch? (Choose 3)
      1. Bytes Pending replication
      2. Operations Pending replication
      3. Number of buckets with replication enabled
      4. Operations Failed Replication
      5. Cost of data transfer for replication
      Show Answer

      Answer: a, b, d – S3 Replication metrics include Bytes Pending, Operations Pending, Replication Latency, and Operations Failed Replication. Number of buckets and cost are not replication metrics.

    References

    Amazon S3 Event Notifications

    S3 Event Notifications

    • S3 notification feature enables notifications to be triggered when certain events happen in the bucket.
    • Notifications are enabled at the Bucket level.
    • Notifications can be configured to be filtered by the prefix and suffix of the key name of objects. However, filtering rules cannot be defined with overlapping prefixes, overlapping suffixes, or prefix and suffix overlapping.
    • S3 event notifications are designed to be delivered at least once. Typically, event notifications are delivered in seconds but can sometimes take a minute or longer.
    • Event notifications are not guaranteed to arrive in the same order that the events occurred. On rare occasions, S3’s retry mechanism might cause duplicate event notifications for the same object event.

    Supported Event Types

    • S3 can publish the following events:
      • New Object Created events (s3:ObjectCreated:*)
        • Can be enabled for Put, Post, Copy, or CompleteMultipartUpload operations
        • You will not receive event notifications from failed operations
      • Object Removal events (s3:ObjectRemoved:*)
        • Can publish delete events for object deletion (s3:ObjectRemoved:Delete) or insertion of delete marker (s3:ObjectRemoved:DeleteMarkerCreated)
        • You will not receive event notifications from automatic deletes from lifecycle configurations or from failed operations.
      • Restore Object events (s3:ObjectRestore:*)
        • Restoration of objects archived to S3 Glacier Flexible Retrieval, S3 Glacier Deep Archive, S3 Intelligent-Tiering Archive Access tier, or Deep Archive Access tier
        • s3:ObjectRestore:Post – restoration initiated
        • s3:ObjectRestore:Completed – restoration completed
        • s3:ObjectRestore:Delete – temporary restored copy expired
      • S3 Lifecycle Expiration events (s3:LifecycleExpiration:*)
        • s3:LifecycleExpiration:Delete – object in unversioned bucket is deleted or object version permanently deleted by lifecycle
        • s3:LifecycleExpiration:DeleteMarkerCreated – lifecycle creates a delete marker when a current version of an object in a versioned bucket is deleted
      • S3 Lifecycle Transition events (s3:LifecycleTransition)
        • Object transitioned to another S3 storage class by a lifecycle configuration
      • S3 Intelligent-Tiering Automatic Archival events (s3:IntelligentTiering)
        • Object within S3 Intelligent-Tiering moved to the Archive Access tier or Deep Archive Access tier
      • Object Tagging events (s3:ObjectTagging:*)
        • s3:ObjectTagging:Put – tag added or updated on an object
        • s3:ObjectTagging:Delete – tag removed from an object
      • Object ACL PUT events (s3:ObjectAcl:Put)
        • ACL is set on an object or existing ACL is changed
        • An event is not generated when a request results in no change to an object’s ACL
      • Object Annotation events (s3:ObjectAnnotation:*) (New – 2025)
        • s3:ObjectAnnotation:Put – annotation created or updated via PutObjectAnnotation
        • s3:ObjectAnnotation:Delete – annotation deleted via DeleteObjectAnnotation
        • GetObjectAnnotation and ListObjectAnnotations do not send event notifications
      • Replication events (s3:Replication:*)
        • For replication configurations with S3 Replication metrics or S3 Replication Time Control (S3 RTC) enabled
        • s3:Replication:OperationFailedReplication – object failed to replicate
        • s3:Replication:OperationMissedThreshold – replication exceeded 15-minute S3 RTC threshold
        • s3:Replication:OperationReplicatedAfterThreshold – object replicated after 15-minute threshold
        • s3:Replication:OperationNotTracked – object no longer tracked by replication metrics
      • Reduced Redundancy Storage (RRS) object lost events (s3:ReducedRedundancyLostObject)
        • Can be used to reproduce/recreate the Object
        • Note: RRS is no longer recommended. Standard S3 is more cost-effective with higher durability (99.999999999% vs 99.99%). Consider migrating to S3 Standard or other storage classes.

    Supported Event Destinations

    • S3 can publish events to the following destinations:
      • SNS topic
        • Only Standard SNS topics are supported (SNS FIFO is not allowed)
      • SQS queue
        • Only Standard SQS queues are supported (SQS FIFO queues are not supported as a direct S3 event notification destination)
        • To send S3 events to SQS FIFO queues, use Amazon EventBridge as an intermediary
      • AWS Lambda function
      • Amazon EventBridge
        • Unlike other destinations, enabling EventBridge sends all events (no need to select specific event types)
        • EventBridge rules can then route events to over 20 targets including Lambda, Kinesis, Step Functions, SQS, SNS, etc.
        • Supports advanced content-based filtering on event attributes (object size, time range, key prefix, etc.)
    • Only one destination type can be specified per event notification configuration (except EventBridge which receives all events when enabled).
    • For S3 to be able to publish events to the destination, the S3 principal should be granted the necessary permissions.

    Amazon EventBridge Integration

    • Amazon EventBridge provides a more powerful event routing mechanism compared to traditional S3 event notifications.
    • When EventBridge is enabled on a bucket, all events are sent to EventBridge automatically – no need to specify individual event types.
    • EventBridge supports additional event types beyond SNS/SQS/Lambda:
      • Object Storage Class Changed
      • Object Access Tier Changed
      • Object Restore Expired
      • Object ACL Updated
      • Object Tags Added/Deleted
      • Object Annotation Created/Removed
    • Key Advantages over SNS/SQS/Lambda destinations:
      • Content-based filtering – filter by any attribute in the event (object size, key pattern, metadata)
      • Multiple targets – single rule can route to multiple targets
      • Over 20 supported targets including Lambda, Step Functions, SQS, SNS, Kinesis, ECS tasks, API destinations
      • Archive and replay – ability to archive events and replay them later
      • Schema discovery – auto-detect event schemas
      • No need for separate notification configurations per event type
    • EventBridge and traditional S3 event notifications (SNS/SQS/Lambda) can be configured simultaneously on the same bucket.

    Event Notification Key Points

    • Notification configuration is stored in the notification subresource associated with the bucket.
    • If notifications write to the same bucket that triggers the notification, it could cause an execution loop. Use two buckets or configure the trigger with a specific prefix for incoming objects.
    • Event notifications do not alert for automatic deletes from lifecycle policies (use s3:LifecycleExpiration events instead).
    • Failed operations do not generate event notifications.

    S3 Event Notifications

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. A company uses S3 to store images. When an image is uploaded, a Lambda function must be triggered to generate thumbnails. What is the MOST efficient approach?
      1. Configure CloudWatch Events to monitor S3 uploads and trigger Lambda
      2. Configure S3 Event Notification with s3:ObjectCreated:* event to invoke the Lambda function
      3. Use a scheduled Lambda function to poll S3 for new objects
      4. Use S3 Batch Operations to process new images
      Show Answer

      Answer: b – S3 Event Notifications can directly invoke Lambda functions when objects are created. This is the most efficient event-driven approach.

    2. A development team needs to send S3 object creation events to an SQS FIFO queue for ordered processing. Which approach should they use?
      1. Configure S3 Event Notification directly to the SQS FIFO queue
      2. Enable Amazon EventBridge on the bucket and create a rule to route events to the SQS FIFO queue
      3. Use SNS FIFO topic as intermediary between S3 and SQS FIFO
      4. Configure S3 Event Notification to Lambda, which forwards to SQS FIFO
      Show Answer

      Answer: b – SQS FIFO queues are not supported as a direct S3 event notification destination. Amazon EventBridge can route S3 events to SQS FIFO queues. SNS FIFO is also not supported as S3 event destination.

    3. An application needs to be notified when objects are transitioned to Glacier by S3 Lifecycle rules, and separately when objects are deleted by lifecycle expiration. Which event types should be configured?
      1. s3:ObjectRemoved:Delete and s3:ObjectRestore:Post
      2. s3:LifecycleTransition and s3:LifecycleExpiration:Delete
      3. s3:ObjectCreated:Copy and s3:ObjectRemoved:*
      4. s3:IntelligentTiering and s3:ObjectRemoved:Delete
      Show Answer

      Answer: b – s3:LifecycleTransition fires when lifecycle transitions objects to another storage class. s3:LifecycleExpiration:Delete fires when lifecycle deletes objects. s3:ObjectRemoved:Delete does NOT fire for lifecycle deletions.

    4. A company wants to filter S3 events by object size and route them to different Lambda functions – small objects to one function and large objects to another. Which approach supports this?
      1. Configure two S3 Event Notification rules with different prefix filters
      2. Enable Amazon EventBridge and create content-based filtering rules
      3. Use SNS with message filtering policies
      4. Configure S3 Event Notification to SQS and use Lambda to filter
      Show Answer

      Answer: b – Amazon EventBridge supports content-based filtering on any event attribute including object size, time range, and metadata fields. S3 Event Notifications natively only support prefix and suffix filtering on key names.

    5. Which of the following are valid S3 event notification destinations? (Choose 3)
      1. Amazon SNS FIFO topic
      2. Amazon SQS Standard queue
      3. AWS Lambda function
      4. Amazon EventBridge
      5. Amazon SQS FIFO queue
      Show Answer

      Answer: b, c, d – S3 event notifications support SNS Standard topics, SQS Standard queues, Lambda functions, and Amazon EventBridge. SNS FIFO and SQS FIFO are not supported as direct S3 event notification destinations.

    References

    Amazon S3 Static Website Hosting

    S3 Static Website Hosting

    📌 AWS Recommendation (October 2024): AWS now recommends using AWS Amplify Hosting to host static website content stored on S3. Amplify Hosting is a fully managed service that deploys your websites on a globally available CDN powered by Amazon CloudFront, with built-in HTTPS, custom domains, redirects, and custom headers. See AWS Amplify Hosting section below.

    • Amazon S3 can be used for Static Website hosting with Client-side scripts.
    • S3 does not support server-side scripting.
    • S3, in conjunction with Route 53, supports hosting a website at the root domain which can point to the S3 website endpoint
    • S3 website endpoints do not support HTTPS or access points. Use Amazon CloudFront to serve HTTPS traffic.
    • For S3 website hosting the content should be made publicly readable which can be provided using a bucket policy.
    • Since April 2023, all new S3 buckets have Block Public Access enabled and ACLs disabled by default. To use S3 static website hosting, Block Public Access must be explicitly disabled and a bucket policy must be configured for public read access.
    • Users can configure the index, and error document as well as configure the conditional routing of an object name
    • S3 supports up to 50 routing rules per website configuration for conditional redirects.
    • Requester Pays buckets do not allow access through the website endpoint. Any request to such a bucket will receive a 403 – Access Denied response.
    • If the S3 bucket is encrypted using SSE-KMS, the website endpoint cannot serve the content. Use CloudFront with Origin Access Control (OAC) instead.
    • S3 website endpoint domains are registered in the Public Suffix List (PSL). If setting sensitive cookies, use the __Host- prefix for CSRF protection.

    S3 Website Endpoints

    • S3 provides two types of endpoints:
      • REST API endpoint (s3.amazonaws.com) – Supports HTTPS, access points, OAC
      • Website endpoint (s3-website-region.amazonaws.com or s3-website.region.amazonaws.com) – Supports only HTTP, no access points, no OAC
    • Website endpoint formats:
      • http://bucket-name.s3-website-Region.amazonaws.com (dash format)
      • http://bucket-name.s3-website.Region.amazonaws.com (dot format)
    • Website endpoints return HTML error documents for 4xx errors, while REST API endpoints return XML error responses.
    • Website endpoints support index documents and redirects; REST API endpoints do not.

    S3 Static Website with CloudFront

    • CloudFront is the recommended approach to add HTTPS support, caching, and global distribution to S3-hosted websites.
    • Two approaches to use CloudFront with S3:
      • S3 REST API endpoint as origin with OAC (Recommended) – Keeps the bucket private; CloudFront uses Origin Access Control to authenticate requests to S3.
      • S3 website endpoint as custom origin – Bucket must be publicly accessible; does not support OAC/OAI. Can restrict access using a custom Referer header.
    • Origin Access Control (OAC) is the current best practice for securing S3 origins with CloudFront (replaces the legacy OAI).
      • OAI creation was deprecated in 2024.
      • As of March 2026, new CloudFront distributions can only use OAC.
      • OAC supports SSE-KMS encrypted objects, SigV4, and all AWS regions.
      • OAC requires S3 Object Ownership set to “Bucket owner enforced” (default for new buckets).
    • CloudFront Functions can handle URL rewriting (e.g., appending index.html to directory paths) when using the REST API endpoint with OAC, providing website-endpoint-like behavior while keeping the bucket private.
    • AWS Shield Standard is automatically included with every CloudFront distribution at no extra cost for DDoS protection.

    AWS Amplify Hosting (Recommended Alternative)

    • AWS Amplify Hosting is a fully managed service for hosting static websites, officially recommended by AWS as of October 2024 for static content stored on S3.
    • Key benefits over S3 website hosting:
      • Built-in HTTPS with free SSL/TLS certificates
      • Global CDN powered by Amazon CloudFront
      • Custom domain configuration with automatic DNS setup
      • Custom headers and redirects without additional services
      • Atomic deployments and instant cache invalidation
      • No need to disable Block Public Access on S3 bucket
    • Amplify Hosting can deploy directly from an S3 general purpose bucket by selecting the location of objects within the bucket.
    • Does not support cross-account S3 bucket access.
    • Simplifies the setup compared to manually configuring S3 + CloudFront + Route 53 + ACM.

    Security Best Practices

    • Prefer CloudFront + OAC or Amplify Hosting over making S3 buckets publicly accessible.
    • Keep Block Public Access enabled whenever possible; use CloudFront OAC to grant access to the distribution only.
    • If public access is required (S3 website endpoint), use a bucket policy (not ACLs) to grant read access, as ACLs are disabled by default on new buckets.
    • Enable access logging to track website requests.
    • Use CloudFront with WAF for additional security controls like geo-restriction, rate limiting, and IP filtering.

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. Company ABCD is currently hosting their corporate site in an Amazon S3 bucket with Static Website Hosting enabled. Currently, when visitors go to http://www.companyabcd.com the index.html page is returned. Company C now would like a new page welcome.html to be returned when a visitor enters http://www.companyabcd.com in the browser. Which of the following steps will allow Company ABCD to meet this requirement? Choose 2 answers.
      1. Upload an html page named welcome.html to their S3 bucket
      2. Create a welcome subfolder in their S3 bucket
      3. Set the Index Document property to welcome.html
      4. Move the index.html page to a welcome subfolder
      5. Set the Error Document property to welcome.html
    2. A company wants to host a static website on AWS with HTTPS support using a custom domain. The website files are stored in an S3 bucket. Which combination of services provides the MOST secure and recommended architecture? Choose 2 answers.
      1. Enable S3 static website hosting and use the website endpoint directly
      2. Use CloudFront with Origin Access Control (OAC) and the S3 REST API endpoint as origin
      3. Use CloudFront with Origin Access Identity (OAI)
      4. Keep S3 Block Public Access enabled on the bucket
      5. Disable server-side encryption on the bucket
    3. A developer needs to host a static single-page application on AWS. The requirements include HTTPS, a custom domain, atomic deployments, and minimal operational overhead. Which approach requires the LEAST configuration effort?
      1. S3 static website hosting with CloudFront and ACM certificate
      2. AWS Amplify Hosting with S3 as the source
      3. S3 static website hosting with Route 53 alias record
      4. EC2 instance with Nginx serving static files
    4. An organization hosts a static website on S3 using the website endpoint. They want to ensure only CloudFront can access the S3 content while keeping the bucket private. However, they need S3 website features like index documents for subdirectories. What is the recommended solution?
      1. Use OAC with the S3 website endpoint
      2. Use CloudFront with the S3 REST API endpoint, OAC, and a CloudFront Function for URL rewriting
      3. Use OAI with the S3 website endpoint
      4. Make the bucket public and use a custom Referer header
    5. A company created a new S3 bucket and enabled static website hosting. However, users are receiving 403 Forbidden errors when accessing the website. What is the MOST likely cause? (Choose 2)
      1. S3 Block Public Access is still enabled on the bucket (default for new buckets since April 2023)
      2. The bucket does not have versioning enabled
      3. No bucket policy has been configured to allow public read access
      4. The index document has not been uploaded
      5. The bucket is using SSE-S3 encryption

    References

    Amazon MSK – Managed Kafka Streaming Service

    Managed Streaming for Apache Kafka – MSK

    • Managed Streaming for Apache Kafka – MSK is an AWS streaming data service that manages Apache Kafka infrastructure and operations.
    • Apache Kafka
      • is an open-source, high-performance, fault-tolerant, and scalable streaming data store platform for building real-time streaming data pipelines and applications.
      • stores streaming data in a fault-tolerant way, providing a buffer between producers and consumers.
      • stores events as a continuous series of records and preserves the order in which the records were produced.
      • runs as a cluster and stores data records in topics, which are partitioned and replicated across one or more brokers that can be spread across multiple AZs for high availability.
      • allows many data producers and multiple consumers that can process data from Kafka topics on a first-in-first-out basis, preserving the order data were produced.
    • makes it easy for developers and DevOps managers to run Kafka applications and Kafka Connect connectors on AWS, without the need to become experts in operating Kafka.
    • operates, maintains, and scales Kafka clusters, provides enterprise-grade security features out of the box, and has built-in AWS integrations that accelerate development of streaming data applications.
    • always runs within a VPC managed by the MSK and is available to your own selected VPC, subnet, and security group when the cluster is setup.
    • IP addresses from the VPC are attached to the MSK resources through elastic network interfaces (ENIs), and all network traffic stays within the AWS network and is not accessible to the internet by default.
    • supports dual-stack connectivity (IPv4 and IPv6) for both MSK Provisioned and MSK Serverless clusters, enabling clients to connect using either protocol.
    • integrates with CloudWatch for monitoring, metrics, and logging.
    • offers two cluster types:
      • MSK Provisioned – you select, manage, and manually scale cluster capacity (broker type, number, and storage).
      • MSK Serverless – capacity is automatically provisioned and scaled without managing compute or storage.
    • supports Topic Management APIs (CreateTopic, UpdateTopic, DeleteTopic) allowing topic management via AWS CLI, SDKs, CloudFormation, and the console without requiring Kafka admin clients.

    MSK Provisioned – Broker Types

    • MSK Provisioned offers two broker types: Standard brokers and Express brokers.

    Standard Brokers

    • Standard brokers are the traditional MSK broker type using Apache Kafka’s native storage engine.
    • You must provision and manage EBS storage volumes attached to each broker.
    • Support all Apache Kafka versions available on MSK.
    • Available in 2-AZ and 3-AZ configurations.
    • Support Graviton3-based M7g instances, providing up to 29% more throughput and up to 24% lower costs compared to previous generation instances.

    Express Brokers

    • Express brokers are a new broker type (GA at re:Invent 2024) designed for higher throughput, faster scaling, and simplified operations.
    • Key benefits include:
      • No storage management – elastic, virtually unlimited, pay-as-you-go storage with no provisioning or sizing needed.
      • Higher throughput – up to 3x more throughput per broker (e.g., 500 MBps ingress on m7g.16xlarge Express vs. ~154 MBps on equivalent Standard broker).
      • Faster scaling – scale clusters and move partitions up to 20x faster than Standard brokers.
      • Faster recovery – 90% faster recovery from broker failures compared to standard Apache Kafka brokers.
      • No maintenance windows – Amazon MSK automatically updates cluster hardware on an ongoing basis.
      • Pre-configured best practices – includes guardrails on critical Kafka configurations, throughput quotas, and capacity reservations for background operations.
      • Intelligent Rebalancing – supports 180x faster partition rebalancing operations.
    • Express brokers are only available in 3-AZ configurations.
    • Support Apache Kafka versions 3.6, 3.8, and 3.9.
    • Support KRaft mode (ZooKeeper-free) from Apache Kafka version 3.9 onwards.
    • Work with Apache Kafka APIs but don’t yet fully support KStreams API.
    • Data is distributed across three AZs by default with replication factor of 3 and minimum in-sync replicas of 2.

    MSK Serverless

    • MSK Serverless is a cluster type that helps run Kafka clusters without having to manage compute and storage capacity.
    • automatically provisions and scales capacity while managing the partitions in your topic, so you can stream data without thinking about right-sizing or scaling clusters.
    • offers throughput-based pricing, so you pay only for the data volume you stream and retain.
    • fully manages partitions, including monitoring and moving them to even load across a cluster.
    • creates 2 replicas for each partition and places them in different AZs. Additionally, MSK Serverless automatically detects and recovers failed backend resources to maintain high availability.
    • encrypts all traffic in transit and all data at rest using Key Management Service (KMS).
    • allows clients to connect over a private connection using AWS PrivateLink without exposing the traffic to the public internet.
    • offers IAM Access Control for both client authentication and authorization to Kafka resources such as topics.
    • supports dual-stack connectivity (IPv4 and IPv6).
    • is fully compatible with Apache Kafka, allowing use of any compatible client applications to produce and consume data.

    MSK Tiered Storage

    • Tiered Storage offers a virtually unlimited, low-cost remote storage tier in addition to the high-performance local storage tier on MSK Provisioned clusters.
    • makes it cost-effective to retain data for longer durations (days, weeks, or months) in Apache Kafka without increasing local broker storage.
    • data is first stored in the performance-optimized primary (local) storage tier and is automatically tiered into the low-cost remote storage tier based on retention policies.
    • consumers can transparently read data from both tiers using the same Kafka APIs without application changes.
    • can save 50% or more on storage costs compared to provisioning all data on local broker storage.
    • can be enabled with a few clicks for new or existing clusters.
    • improves cluster resiliency by reducing local storage pressure and simplifying broker replacement.
    • supported on Apache Kafka version 3.6.0 and later.
    • Note: Express brokers include built-in elastic, virtually unlimited storage and do not require separate tiered storage configuration.

    MSK Replicator

    • MSK Replicator is a fully managed feature that enables reliable replication of streaming data across Amazon MSK clusters in different or the same AWS Regions.
    • eliminates the need to write custom code, manage infrastructure, or set up cross-region networking for replication.
    • supports both active-active and active-passive cluster topologies for high availability and disaster recovery.
    • Key use cases:
      • Business continuity and disaster recovery – replicate data to a secondary region; if the primary region is degraded, redirect applications to the secondary region.
      • Multi-Region applications – serve global clients with reduced latency by having data copies in multiple geographies.
      • Data aggregation – aggregate data from multiple clusters for centralized analytics.
      • Partner data sharing – share streaming data with partners across accounts/regions.
      • Migration – migrate from Standard brokers to Express brokers using MSK Replicator.
    • provides automatic asynchronous replication with topic data, consumer group offsets, and topic configurations.
    • both source and target clusters must be in the same AWS account.
    • available in most AWS Regions and expanding continuously.

    MSK Connect

    • MSK Connect is a feature that makes it easy to stream data to and from Apache Kafka clusters using Kafka Connect connectors.
    • uses Kafka Connect versions 2.7.1 or 3.7.x open-source frameworks.
    • deploys fully managed connectors that move data into or pull data from popular data stores like Amazon S3, Amazon OpenSearch Service, and databases.
    • provisions the required resources, continuously monitors connector health and delivery state, patches underlying hardware, and auto-scales connectors to match throughput changes.
    • eliminates the need to provision and maintain Kafka Connect cluster infrastructure.
    • supports updating connector configurations without needing to delete and recreate connectors (Jan 2025).
    • supports worker configuration management – delete worker configurations, tag resources, and manage worker configurations and custom plugins using AWS CloudFormation for CI/CD automation (Mar 2024).
    • supports cross-account access to MSK clusters using IAM authentication.
    • supports dual-stack networking (IPv4 + IPv6) for connectors.
    • offers two capacity modes:
      • Provisioned – you specify the number of workers.
      • Auto-scaled – MSK Connect automatically adjusts the number of workers based on workload.

    Multi-VPC Private Connectivity

    • Multi-VPC private connectivity is a managed solution that simplifies networking for multi-VPC and cross-account connectivity to MSK clusters.
    • powered by AWS PrivateLink, keeping all traffic within the AWS network.
    • allows Apache Kafka clients in different VPCs or different AWS accounts to privately connect to an MSK cluster without complex networking setup (VPC peering, transit gateway, etc.).
    • supports all authentication mechanisms: IAM Access Control, SASL/SCRAM, and TLS certificate authentication (Sep 2024 expansion).
    • the cluster owner can enable/disable private connectivity for one or more auth schemes.
    • the cluster must be in ACTIVE state to configure multi-VPC connectivity.

    MSK Security

    • MSK uses EBS server-side encryption and KMS keys to encrypt storage volumes.
    • Clusters have encryption in transit enabled via TLS for inter-broker communication. For provisioned clusters, you can opt out of using encryption in transit when a cluster is created.
    • MSK clusters running Kafka version 2.5.1 or greater support TLS in-transit encryption between Kafka brokers and ZooKeeper nodes.
    • For provisioned clusters, you have three options:
      • IAM Access Control for both AuthN/Z (recommended),
      • TLS certificate authentication (CA) for AuthN and access control lists for AuthZ
      • SASL/SCRAM for AuthN and access control lists for AuthZ.
    • MSK recommends using IAM Access Control as it defaults to least privilege access and is the most secure option.
    • For serverless clusters, IAM Access Control is used for both authentication and authorization.
    • Multi-VPC private connectivity (PrivateLink) enables secure cross-VPC and cross-account access while keeping traffic on the AWS network.

    MSK Monitoring and Operations

    • MSK integrates with Amazon CloudWatch for cluster-level and broker-level metrics.
    • supports three monitoring levels: DEFAULT, PER_BROKER, and PER_TOPIC_PER_BROKER (increasing levels of granularity).
    • supports sending broker logs to CloudWatch Logs, Amazon S3, and Amazon Data Firehose.
    • supports Open Monitoring with Prometheus-compatible metrics endpoint for integration with third-party monitoring tools (Grafana, Datadog, etc.).
    • AI Agent Skills (Jun 2026) – Amazon MSK now offers AI Agent Skills to help developers operate MSK efficiently and accelerate migrations to MSK.
    • Topic Management APIs (Feb 2026) – CreateTopic, UpdateTopic, and DeleteTopic APIs enable topic management via AWS CLI, SDKs, AWS CloudFormation, and the MSK console without setting up Kafka admin clients.

    AWS Certification Exam Practice Questions

    • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
    • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
    • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
    • Open to further feedback, discussion and correction.
    1. A company needs a managed Apache Kafka service to ingest real-time clickstream data from its website. The data will be consumed by multiple downstream analytics applications. The solution must be highly available, support encryption at rest and in transit, and require minimal operational overhead. Which AWS service should the solutions architect recommend?
      1. Amazon Kinesis Data Streams
      2. Amazon MSK Provisioned with Standard brokers
      3. Amazon MSK Serverless
      4. Self-managed Apache Kafka on Amazon EC2

      Answer: c. MSK Serverless provides a fully managed Kafka experience with automatic scaling, built-in encryption at rest and in transit, and minimal operational overhead.

    2. A streaming data application requires consistently high throughput of 1.5 GBps ingress across 3 brokers and needs to scale rapidly during daily peak traffic periods. The team wants to minimize storage management overhead. Which MSK configuration best meets these requirements?
      1. MSK Provisioned with Standard brokers and auto-scaling storage
      2. MSK Provisioned with Express brokers
      3. MSK Serverless
      4. MSK Provisioned with Standard brokers and tiered storage

      Answer: b. Express brokers provide up to 3x more throughput per broker (500 MBps per m7g.16xlarge), scale up to 20x faster, include elastic pay-as-you-go storage, and eliminate storage management overhead.

    3. A company operates MSK clusters in us-east-1 and needs to implement a disaster recovery strategy with a secondary cluster in eu-west-1. The solution must automatically replicate topic data, consumer group offsets, and topic configurations with minimal custom code. Which approach should the company use?
      1. Deploy MirrorMaker2 on Amazon EC2 instances across regions
      2. Use Amazon MSK Replicator
      3. Use AWS Database Migration Service (DMS)
      4. Configure S3 Cross-Region Replication with MSK tiered storage

      Answer: b. MSK Replicator provides fully managed, automatic asynchronous replication of topic data, consumer group offsets, and topic configurations across MSK clusters in different regions without custom code or infrastructure management.

    4. A development team needs to stream data from an MSK cluster to Amazon OpenSearch Service for near-real-time search and analytics. The team wants a managed solution that auto-scales with throughput changes and does not require managing Kafka Connect infrastructure. Which solution meets these requirements?
      1. Deploy Kafka Connect on Amazon ECS with auto-scaling
      2. Use Amazon MSK Connect with an OpenSearch sink connector
      3. Use Amazon Data Firehose with MSK as source
      4. Write a custom AWS Lambda consumer function

      Answer: b. MSK Connect provides fully managed Kafka Connect connectors with auto-scaling capability, eliminating the need to provision or manage Kafka Connect cluster infrastructure.

    5. An organization has Apache Kafka clients in multiple VPCs across different AWS accounts that need to connect to a centralized MSK cluster. The traffic must stay within the AWS network and not traverse the public internet. Which MSK feature addresses this requirement?
      1. MSK public access with TLS encryption
      2. VPC peering between all accounts
      3. Multi-VPC private connectivity (powered by AWS PrivateLink)
      4. AWS Transit Gateway with MSK

      Answer: c. Multi-VPC private connectivity uses AWS PrivateLink to provide managed cross-VPC and cross-account connectivity, keeping all traffic within the AWS network without complex networking setup.

    6. A company wants to retain 90 days of streaming data in their MSK cluster for compliance purposes but wants to minimize storage costs. The majority of consumers only read data from the last 24 hours. Which MSK feature should they enable?
      1. MSK Express brokers with elastic storage
      2. MSK Tiered Storage
      3. Amazon S3 archival via MSK Connect
      4. Increase EBS volume size on Standard brokers

      Answer: b. MSK Tiered Storage provides a low-cost remote storage tier for older data while keeping recent data on high-performance local storage, reducing storage costs by 50% or more while maintaining transparent consumer access.

    7. Which authentication methods are supported by Amazon MSK Provisioned clusters? (Choose THREE)
      1. IAM Access Control
      2. SASL/SCRAM
      3. TLS certificate authentication (mutual TLS)
      4. Amazon Cognito User Pools
      5. LDAP/Active Directory directly

      Answer: a, b, c. MSK Provisioned supports IAM Access Control (recommended), SASL/SCRAM, and TLS certificate authentication (CA) for client authentication.

    8. A data engineering team is migrating from Standard brokers to Express brokers in Amazon MSK to improve performance. Which statements about Express brokers are correct? (Choose THREE)
      1. Express brokers are available in 2-AZ and 3-AZ configurations
      2. Express brokers eliminate storage provisioning and management
      3. Express brokers recover 90% faster from failures
      4. Express brokers have no maintenance windows
      5. Express brokers support all Apache Kafka versions available on MSK

      Answer: b, c, d. Express brokers provide elastic storage (no provisioning), 90% faster recovery, and no maintenance windows. They are only available in 3-AZ configurations and support Kafka versions 3.6, 3.8, and 3.9.

    References