Machine Learning Concepts – Cheat Sheet

Machine Learning Concepts

📋 Certification Relevance (Updated June 2026)

This post covers Machine Learning concepts relevant for:

  • AWS Certified AI Practitioner (AIF-C01) — Domain 1: AI and ML Fundamentals (20%)
  • AWS Certified Machine Learning Engineer – Associate (MLA-C01) — Domain 2: ML Model Development (26%)
  • AWS Certified Generative AI Developer – Professional (New in 2026)

Note: The AWS Certified Machine Learning – Specialty exam was retired on March 31, 2026. It has been replaced by the ML Engineer Associate and the new Generative AI Developer Professional certifications.

This post covers some of the basic Machine Learning concepts mostly relevant for the AWS AI and Machine Learning certification exams.

Machine Learning Lifecycle
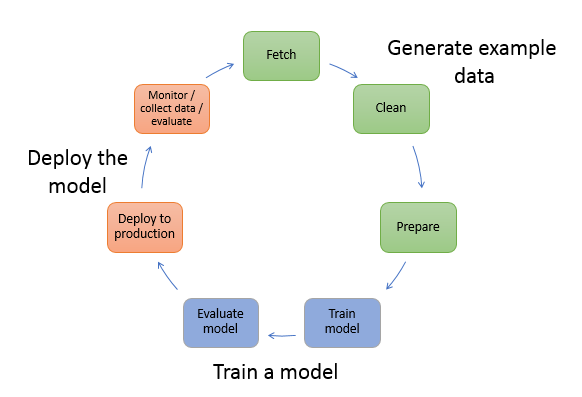
Data Processing and Exploratory Analysis

  • To train a model, you need data.
  • Type of data that depends on the business problem that you want the model to solve (the inferences that you want the model to generate).
  • Process data includes data collection, data cleaning, data split, data exploring, preprocessing, transformation, formatting etc.

Feature Selection and Engineering

  • helps improve model accuracy and speed up training
  • remove irrelevant data inputs using domain knowledge for e.g. name
  • remove features which has same values, very low correlation, very little variance or lot of missing values
  • handle missing data using mean values or imputation
  • combine features which are related for e.g. height and age to height/age
  • convert or transform features to useful representation for e.g. date to day or hour
  • standardize data ranges across features

Missing Data

  • do nothing
  • remove the feature with lot of missing data points
  • remove samples with missing data, if the feature needs to be used
  • Impute using mean/median value
    • no impact and the dataset is not skewed
    • works with numerical values only. Do not use for categorical features.
    • doesn’t factor correlations between features
  • Impute using (Most Frequent) or (Zero/Constant) Values
    • works with categorical features
    • doesn’t factor correlations between features
    • can introduce bias
  • Impute using k-NN, Multivariate Imputation by Chained Equation (MICE), Deep Learning
    • more accurate than the mean, median or most frequent
    • Computationally expensive

Unbalanced Data

  • Source more real data
  • Oversampling instances of the minority class or undersampling instances of the majority class
  • Create or synthesize data using techniques like SMOTE (Synthetic Minority Oversampling TEchnique)

Label Encoding and One-hot Encoding

  • Models cannot multiply strings by the learned weights, encoding helps convert strings to numeric values.
  • Label encoding
    • Use Label encoding to provide lookup or map string data values to a numerical values
    • However, the values are random and would impact the model
  • One-hot encoding
    • Use One-hot encoding for Categorical features that have a discrete set of possible values.
    • One-hot encoding provide binary representation by converting data values into features without impacting the relationships
    • a binary vector is created for each categorical feature in the model that represents values as follows:
      • For values that apply to the example, set corresponding vector elements to 1.
      • Set all other elements to 0.
    • Multi-hot encoding is when multiple values are 1

Cleaning Data

  • Scaling or Normalization means converting floating-point feature values from their natural range (for example, 100 to 900) into a standard range (for example, 0 to 1 or -1 to +1)

Train a model

  • Model training includes both training and evaluating the model,
  • To train a model, algorithm is needed.
  • Data can be split into training data, validation data and test data
    • Algorithm sees and is directly influenced by the training data
    • Algorithm uses but is indirectly influenced by the validation data
    • Algorithm does not see the testing data during training
  • Training can be performed using normal parameters or features and hyperparameters

Supervised, Unsupervised, Semi-Supervised, and Reinforcement Learning
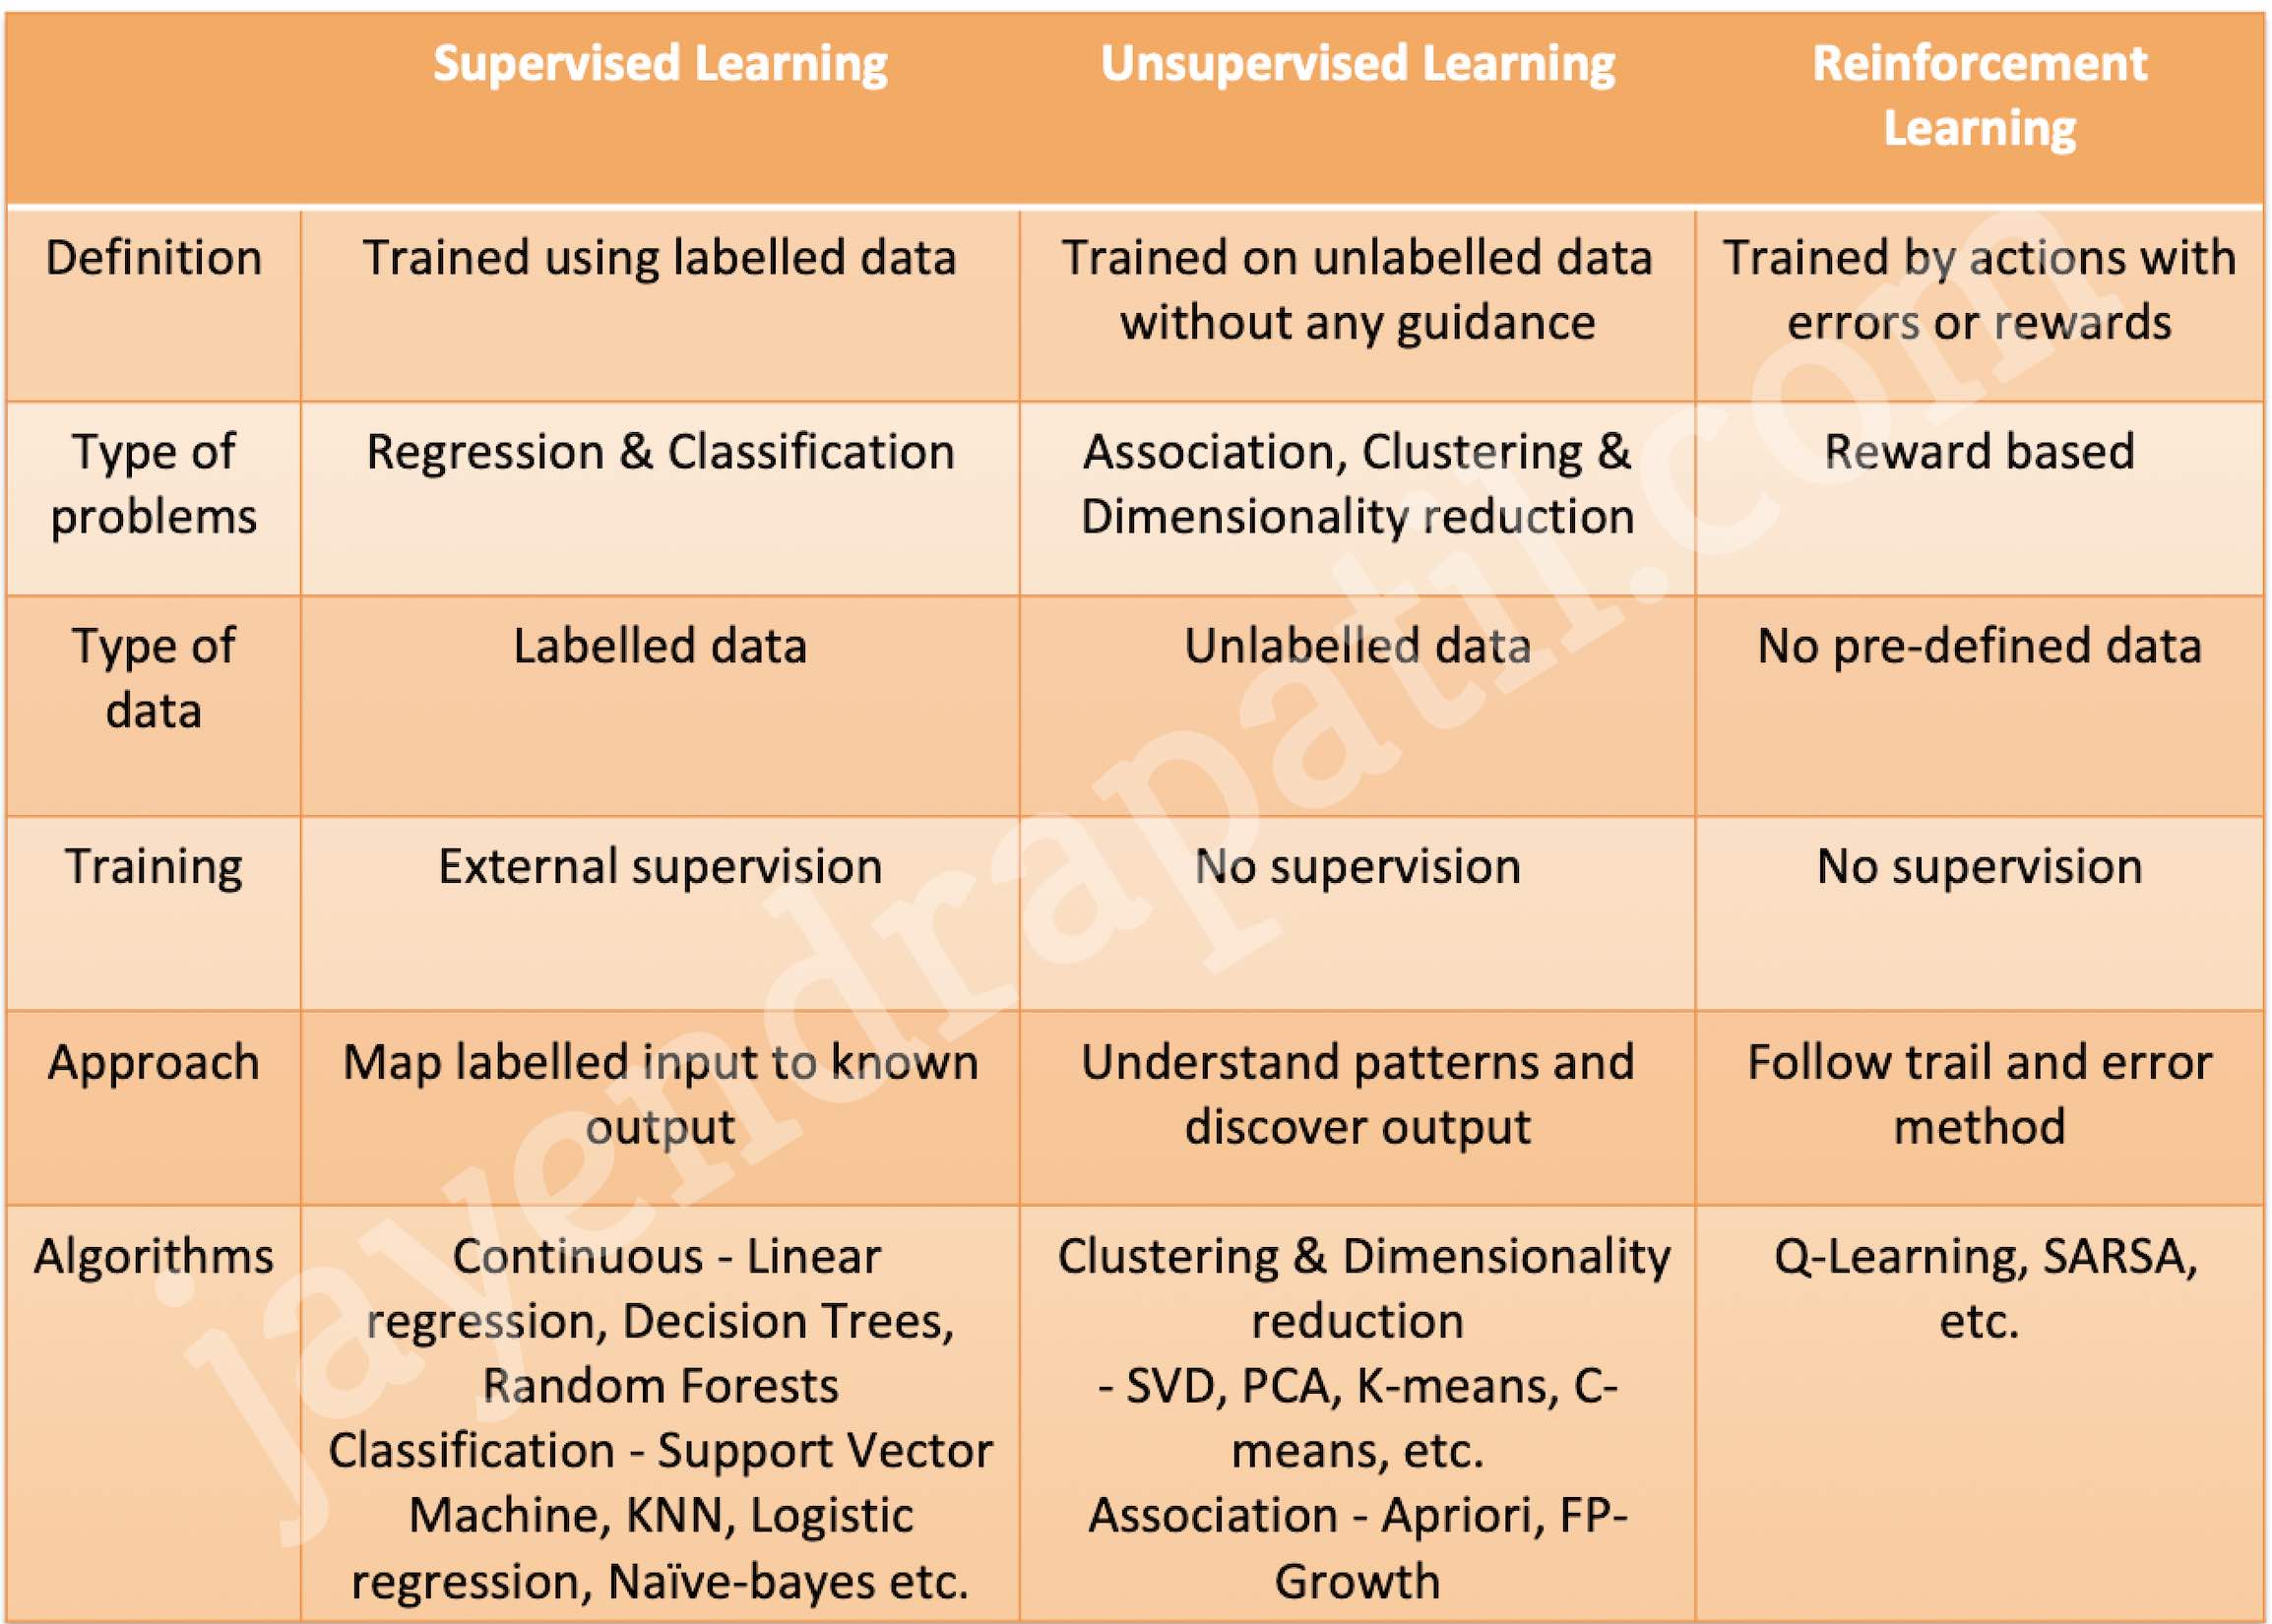
Supervised Learning

  • Uses labeled data — both input features and correct output (target) are provided
  • Model learns mapping between inputs and outputs
  • Types: Classification (categorical output) and Regression (continuous output)
  • Examples: spam detection, image classification, price prediction

Unsupervised Learning

  • Uses unlabeled data — no target variable provided
  • Model discovers hidden patterns or structures in data
  • Types: Clustering, Dimensionality Reduction, Anomaly Detection, Association
  • Examples: customer segmentation, PCA, anomaly detection

Semi-Supervised Learning

  • Combines a small amount of labeled data with a large amount of unlabeled data
  • Useful when labeling data is expensive or time-consuming
  • The model learns from labeled data and generalizes using unlabeled data patterns
  • Examples: medical image classification (few expert-labeled images + many unlabeled)

Self-Supervised Learning

  • A form of unsupervised learning where the model generates its own labels from the input data
  • The foundation of modern Large Language Models (LLMs) and Foundation Models
  • Techniques include masked language modeling (predict missing words) and next-token prediction
  • Enables pre-training on massive unlabeled datasets before fine-tuning on specific tasks
  • Examples: BERT (masked word prediction), GPT (next-token prediction)

Reinforcement Learning

  • Agent learns by interacting with an environment and receiving rewards or penalties
  • Goal is to maximize cumulative reward through trial and error
  • Key concepts: Agent, Environment, State, Action, Reward, Policy
  • Used in robotics, game playing, autonomous vehicles, recommendation systems
  • Reinforcement Learning from Human Feedback (RLHF) — used to fine-tune LLMs based on human preference rankings (key technique behind ChatGPT and similar models)

Splitting and Randomization

  • Always randomize the data before splitting

Hyperparameters

  • influence how the training occurs
  • Common hyperparameters are learning rate, epoch, batch size
  • Learning rate
    • size of the step taken during gradient descent optimization
    • Large learning rates can overshoot the correct solution
    • Small learning rates increase training time
  • Batch size
    • number of samples used to train at any one time
    • can be all (batch), one (stochastic), or some (mini-batch)
    • calculable from infrastructure
    • Small batch sizes tend to not get stuck in local minima
    • Large batch sizes can converge on the wrong solution at random.
  • Epochs
    • number of times the algorithm processes the entire training data
    • each epoch or run can see the model get closer to the desired state
  • depends on algorithm used

Evaluating the model

After training the model, evaluate it to determine whether the accuracy of the inferences is acceptable.

ML Model Insights

  • For binary classification models use accuracy metric called Area Under the (Receiver Operating Characteristic) Curve (AUC). AUC measures the ability of the model to predict a higher score for positive examples as compared to negative examples.
  • For regression tasks, use the industry standard root mean square error (RMSE) metric. It is a distance measure between the predicted numeric target and the actual numeric answer (ground truth). The smaller the value of the RMSE, the better is the predictive accuracy of the model.

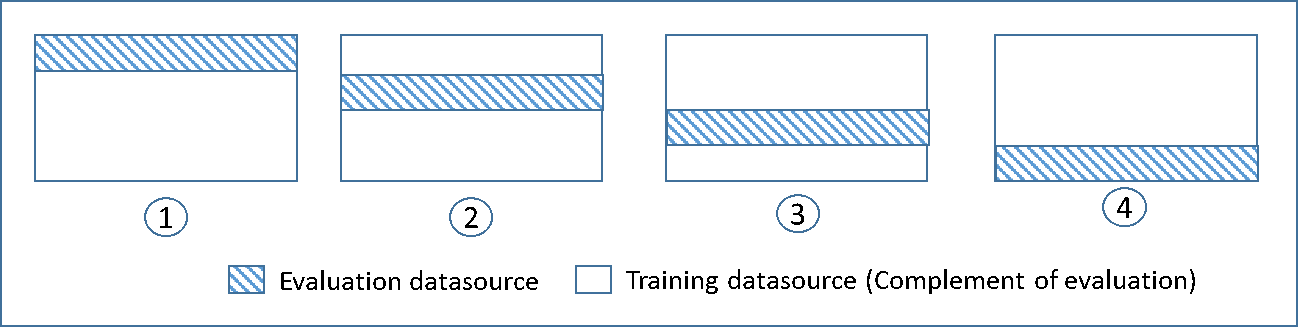
Cross-Validation

  • is a technique for evaluating ML models by training several ML models on subsets of the available input data and evaluating them on the complementary subset of the data.
  • Use cross-validation to detect overfitting, ie, failing to generalize a pattern.
  • there is no separate validation data, involves splitting the training data into chunks of validation data and use it for validation
Optimization

  • Gradient Descent is used to optimize many different types of machine learning algorithms
  • Step size sets Learning rate
    • If the learning rate is too large, the minimum slope might be missed and the graph would oscillate
    • If the learning rate is too small, it requires too many steps which would take the process longer and is less efficient

Underfitting

  • Model is underfitting the training data when the model performs poorly on the training data because the model is unable to capture the relationship between the input examples (often called X) and the target values (often called Y).
  • To increase model flexibility
    • Add new domain-specific features and more feature Cartesian products, and change the types of feature processing used (e.g., increasing n-grams size)
    • Regularization – Decrease the amount of regularization used
    • Increase the amount of training data examples.
    • Increase the number of passes on the existing training data.

Overfitting

  • Model is overfitting the training data when the model performs well on the training data but does not perform well on the evaluation data because the model is memorizing the data it has seen and is unable to generalize to unseen examples.
  • To increase model flexibility
    • Feature selection: consider using fewer feature combinations, decrease n-grams size, and decrease the number of numeric attribute bins.
    • Simplify the model, by reducing the number of layers.
    • Regularization – technique to reduce the complexity of the model. Increase the amount of regularization used.
    • Early Stopping – a form of regularization while training a model with an iterative method, such as gradient descent.
    • Data Augmentation – process of artificially generating new data from existing data, primarily to train new ML models.
    • Dropout is a regularization technique that prevents overfitting.

Deep Learning and Neural Networks

  • Deep Learning is a subset of machine learning that uses neural networks with multiple layers (deep neural networks) to learn complex patterns
  • Excels at tasks involving unstructured data (images, text, audio)
  • Requires large amounts of data and significant compute resources

Neural Network Fundamentals

  • Composed of layers: Input Layer, Hidden Layers, and Output Layer
  • Each neuron applies weights, bias, and an activation function to its inputs
  • Common activation functions: ReLU, Sigmoid, Tanh, Softmax
  • Backpropagation — algorithm used to calculate gradients and update weights during training
  • A network with 2+ hidden layers is considered a “deep” neural network

Types of Neural Networks

Convolutional Neural Networks (CNNs)

  • Specialized for processing grid-like data (images, spatial data)
  • Uses convolutional layers with filters/kernels to detect features (edges, shapes, objects)
  • Key layers: Convolutional, Pooling (Max/Average), Fully Connected
  • Use cases: image classification, object detection, computer vision

Recurrent Neural Networks (RNNs)

  • Designed for sequential data (time series, text, speech)
  • Maintains internal state (memory) that captures information from previous time steps
  • LSTM (Long Short-Term Memory) — addresses vanishing gradient problem with gates (forget, input, output)
  • GRU (Gated Recurrent Unit) — simplified version of LSTM with fewer parameters
  • Largely superseded by Transformers for NLP tasks due to inability to parallelize

Transformers

  • Architecture introduced in “Attention Is All You Need” (2017) — foundation of modern LLMs
  • Processes entire input sequences in parallel using self-attention mechanism
  • Key innovation: Attention mechanism allows each token to attend to every other token regardless of distance
  • Components: Multi-Head Attention, Positional Encoding, Feed-Forward Layers, Layer Normalization
  • Encoder — processes input and creates representations (BERT-style models)
  • Decoder — generates output tokens auto-regressively (GPT-style models)
  • Encoder-Decoder — used for sequence-to-sequence tasks (T5, translation)
  • Use cases: NLP, text generation, translation, code generation, image generation

Generative Adversarial Networks (GANs)

  • Two networks compete: Generator (creates synthetic data) vs Discriminator (detects fake data)
  • Training improves both networks iteratively
  • Use cases: image generation, style transfer, data augmentation

Generative AI and Foundation Models

  • Generative AI is a subset of deep learning that creates new content (text, images, code, audio, video) based on patterns learned from training data
  • Foundation Models (FMs) are large pre-trained models trained on broad datasets that can be adapted for many downstream tasks
  • Examples: GPT-4, Claude, Amazon Titan, Amazon Nova, Llama, Gemini

Large Language Models (LLMs)

  • Foundation models trained on massive text corpora using self-supervised learning
  • Based on the Transformer architecture
  • Capabilities: text generation, summarization, translation, code generation, reasoning
  • Key characteristics:
    • Parameters — learned weights (billions to trillions); more parameters generally = more capability
    • Context window — maximum number of tokens the model can process at once
    • Tokens — basic units of text (words or sub-words) the model processes
    • Temperature — controls randomness of output (0 = deterministic, higher = more creative)

Customizing Foundation Models

Prompt Engineering

  • Crafting input prompts to guide model output without changing model weights
  • Zero-shot — no examples provided in prompt
  • Few-shot — providing examples in the prompt to guide the response
  • Chain-of-thought — guiding model to show reasoning steps
  • No training required; fastest and cheapest customization method

Retrieval-Augmented Generation (RAG)

  • Combines retrieval of external knowledge with generation of responses
  • Retrieves relevant documents from a knowledge base and includes them in the prompt context
  • Reduces hallucinations by grounding responses in factual data
  • No model retraining required; knowledge base can be updated independently
  • Components: Document store, Embedding model, Vector database, Retriever, Generator
  • AWS service: Amazon Bedrock Knowledge Bases

Fine-Tuning

  • Further training a pre-trained model on a task-specific labeled dataset
  • Updates model weights to specialize for specific domain or task
  • Requires labeled training data and compute resources
  • Types:
    • Full fine-tuning — updates all model parameters (expensive)
    • Parameter-Efficient Fine-Tuning (PEFT) — updates only a small subset of parameters
    • LoRA (Low-Rank Adaptation) — adds small trainable matrices to frozen model layers
  • AWS service: Amazon Bedrock and Amazon SageMaker AI

Continued Pre-Training

  • Training a foundation model on additional domain-specific unlabeled data
  • Teaches the model new domain knowledge (medical, legal, financial terminology)
  • More expensive than fine-tuning but creates deeper domain understanding

Transfer Learning

  • Technique of using a model trained on one task as the starting point for a related task
  • Reduces training time and data requirements significantly
  • Foundation models are the ultimate form of transfer learning — pre-trained on broad data, then adapted
  • Approaches: Feature extraction (freeze base layers) or Fine-tuning (update some/all layers)

Agentic AI

  • AI systems that can autonomously plan, reason, and take actions to accomplish goals
  • Uses tools, APIs, and knowledge bases to complete multi-step tasks
  • Key components: Planning, Memory, Tool use, Reasoning
  • AWS service: Amazon Bedrock Agents, Amazon Bedrock AgentCore

Classification Model Evaluation

Confusion Matrix

  • Confusion matrix represents the percentage of times each label was predicted in the training set during evaluation
  • An NxN table that summarizes how successful a classification model’s predictions were; that is, the correlation between the label and the model’s classification.
  • One axis of a confusion matrix is the label that the model predicted, and the other axis is the actual label.
  • N represents the number of classes. In a binary classification problem, N=2
    • For example, here is a sample confusion matrix for a binary classification problem:
Tumor (predicted) Non-Tumor (predicted)
Tumor (actual) 18 (True Positives) 1 (False Negatives)
Non-Tumor (actual) 6 (False Positives) 452 (True Negatives)
    • Confusion matrix shows that of the 19 samples that actually had tumors, the model correctly classified 18 as having tumors (18 true positives), and incorrectly classified 1 as not having a tumor (1 false negative).
    • Similarly, of 458 samples that actually did not have tumors, 452 were correctly classified (452 true negatives) and 6 were incorrectly classified (6 false positives).
  • Confusion matrix for a multi-class classification problem can help you determine mistake patterns. For example, a confusion matrix could reveal that a model trained to recognize handwritten digits tends to mistakenly predict 9 instead of 4, or 1 instead of 7.

Accuracy, Precision, Recall (Sensitivity) and Specificity

Accuracy

  • A metric for classification models, that identifies fraction of predictions that a classification model got right.
  • In Binary classification, calculated as (True Positives+True Negatives)/Total Number Of Examples
  • In Multi-class classification, calculated as Correct Predictions/Total Number Of Examples

Precision

  • A metric for classification models. that identifies the frequency with which a model was correct when predicting the positive class.
  • Calculated as True Positives/(True Positives + False Positives)

Recall – Sensitivity – True Positive Rate (TPR)

  • A metric for classification models that answers the following question: Out of all the possible positive labels, how many did the model correctly identify i.e. Number of correct positives out of actual positive results
  • Calculated as True Positives/(True Positives + False Negatives)
  • Important when – False Positives are acceptable as long as ALL positives are found for e.g. it is fine to predict Non-Tumor as Tumor as long as All the Tumors are correctly predicted

Specificity – True Negative Rate (TNR)

  • Number of correct negatives out of actual negative results
  • Calculated as True Negatives/(True Negatives + False Positives)
  • Important when – False Positives are unacceptable; it’s better to have false negatives for e.g. it is not fine to predict Non-Tumor as Tumor;

ROC and AUC

ROC (Receiver Operating Characteristic) Curve

  • An ROC curve (receiver operating characteristic curve) is curve of true positive rate vs. false positive rate at different classification thresholds.
  • An ROC curve is a graph showing the performance of a classification model at all classification thresholds.
  • An ROC curve plots True Positive Rate (TPR) vs. False Positive Rate (FPR) at different classification thresholds. Lowering the classification threshold classifies more items as positive, thus increasing both False Positives and True Positives.

    ROC Curve showing TP Rate vs. FP Rate at different classification thresholds.

AUC (Area under the ROC curve)

  • AUC stands for “Area under the ROC Curve.”
  • AUC measures the entire two-dimensional area underneath the entire ROC curve (think integral calculus) from (0,0) to (1,1).
  • AUC provides an aggregate measure of performance across all possible classification thresholds.
  • One way of interpreting AUC is as the probability that the model ranks a random positive example more highly than a random negative example.

AUC (Area under the ROC Curve).

F1 Score

  • F1 score (also F-score or F-measure) is a measure of a test’s accuracy.
  • It considers both the precision p and the recall r of the test to compute the score: p is the number of correct positive results divided by the number of all positive results returned by the classifier, and r is the number of correct positive results divided by the number of all relevant samples (all samples that should have been identified as positive).
  • Calculated as: F1 = 2 × (Precision × Recall) / (Precision + Recall)
  • Ranges from 0 to 1, with 1 being perfect precision and recall
  • Useful when you need a balance between precision and recall, especially with imbalanced datasets

Generative AI Evaluation Metrics

  • Traditional ML metrics (accuracy, F1) are insufficient for evaluating generative AI outputs
  • Generative AI requires metrics that measure quality, safety, relevance, and factual accuracy

Text Generation Metrics

BLEU (Bilingual Evaluation Understudy)

  • Measures n-gram overlap between generated text and reference text
  • Ranges from 0 to 1 (higher is better)
  • Originally designed for machine translation evaluation
  • Limitation: only measures lexical similarity, not semantic meaning

ROUGE (Recall-Oriented Understudy for Gisting Evaluation)

  • Measures overlap between generated summary and reference summary
  • ROUGE-N — n-gram overlap (ROUGE-1 = unigrams, ROUGE-2 = bigrams)
  • ROUGE-L — longest common subsequence
  • Commonly used for summarization tasks

Perplexity

  • Measures how well a model predicts a sequence of words
  • Lower perplexity = better model (model is less “surprised” by the text)
  • Useful for comparing language models but doesn’t directly measure output quality

BERTScore

  • Uses contextual embeddings to measure semantic similarity between generated and reference text
  • Better than BLEU/ROUGE at capturing meaning rather than just word overlap

Generative AI Safety Metrics

Hallucination Rate

  • Measures how often a model generates factually incorrect or fabricated information
  • Critical metric for production deployments
  • Mitigated by RAG, grounding, and guardrails

Groundedness

  • Measures whether model responses are supported by provided context/source documents
  • Key metric for RAG systems

Toxicity and Content Safety

  • Measures presence of harmful, biased, or inappropriate content in outputs
  • AWS service: Amazon Bedrock Guardrails for content filtering

Human Evaluation and LLM-as-a-Judge

  • Human evaluation remains the gold standard for assessing quality, helpfulness, and safety
  • LLM-as-a-Judge — using a capable LLM to evaluate outputs of another model (scalable alternative to human evaluation)
  • AWS service: Amazon Bedrock Evaluations for automated model evaluation

Responsible AI and ML Fairness

  • Ensuring AI systems are fair, transparent, accountable, and safe
  • Regulatory frameworks: EU AI Act, ISO 42001, NIST AI RMF

Bias in Machine Learning

  • Data Bias — bias present in training data (sampling bias, historical bias, measurement bias)
  • Algorithmic Bias — bias introduced by the model or training process
  • Selection Bias — non-representative training data
  • Detection: AWS Amazon SageMaker Clarify provides pre-training and post-training bias detection metrics

Explainability and Interpretability

  • Explainability — ability to understand why a model made a specific prediction
  • Techniques: SHAP (SHapley Additive exPlanations), feature importance, attention visualization
  • AWS service: Amazon SageMaker Clarify for model explainability
  • Critical for regulated industries (healthcare, finance) where decisions must be justified

Model Governance

  • Tracking model lineage, versioning, and approval workflows
  • Model cards documenting intended use, limitations, and evaluation results
  • AWS service: Amazon SageMaker Model Registry and SageMaker Data & AI Governance

Deploy the model

  • Re-engineer a model before integrating it with the application and deploy it.
  • Can be deployed as a Batch or as a Service (real-time endpoint)
  • Model Monitoring — continuously track model performance in production to detect drift
    • Data Drift — input data distribution changes over time compared to training data
    • Model Drift (Concept Drift) — relationship between input and output changes over time
    • Requires retraining or updating the model when drift is detected
  • A/B Testing — deploying multiple model variants to compare performance with real traffic
  • Shadow Deployment — running new model alongside production model without serving its predictions to users

AWS Machine Learning Services Summary

  • Amazon SageMaker AI — fully managed service to build, train, and deploy ML models at scale
  • Amazon Bedrock — managed service to build generative AI applications using foundation models (Amazon Titan, Amazon Nova, Claude, Llama, etc.)
  • Amazon Bedrock Knowledge Bases — managed RAG service
  • Amazon Bedrock Agents — build autonomous AI agents
  • Amazon Bedrock Guardrails — content filtering and safety controls
  • Amazon Q Developer — AI-powered coding assistant
  • Amazon SageMaker Clarify — bias detection and model explainability
  • Amazon Comprehend — NLP service for text analysis
  • Amazon Rekognition — computer vision service
  • Amazon Transcribe — speech-to-text
  • Amazon Polly — text-to-speech
  • Amazon Translate — language translation
References

RDS Blue/Green Deployments – Zero-Downtime Updates

RDS Blue/Green Deployment

Amazon RDS Blue/Green Deployments

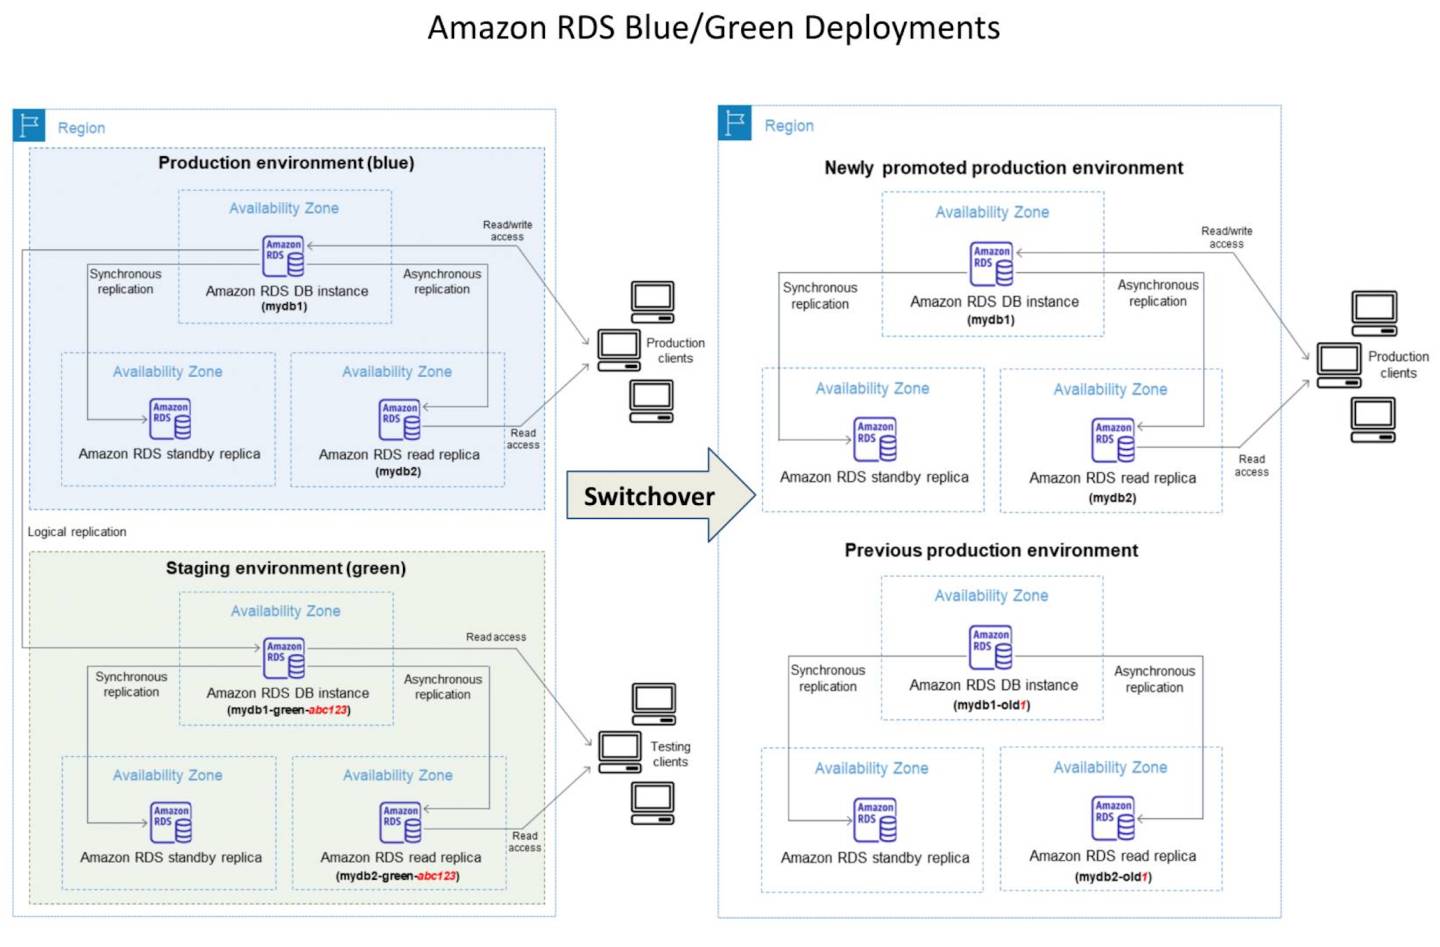
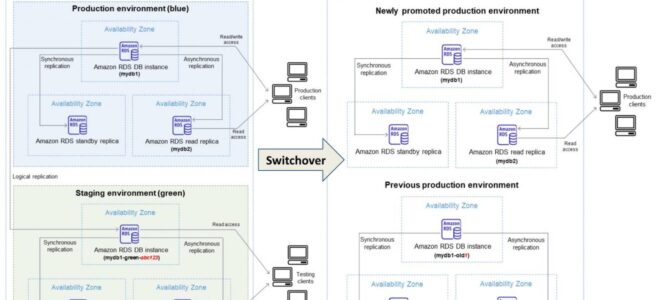
  • Amazon RDS Blue/Green Deployments help make and test database changes before implementing them in a production environment.
  • RDS Blue/Green Deployment has the blue environment as the current production environment and the green environment as the staging environment.
  • RDS Blue/Green Deployment creates a staging or green environment that exactly copies the production environment.
  • Green environment is a copy of the topology of the production environment and includes the features used by the DB instance including the Multi-AZ deployment, read replicas, the storage configuration, DB snapshots, automated backups, Performance Insights, and Enhanced Monitoring.
  • Green environment or the staging environment always stays in sync with the current production environment using logical replication (for major version upgrades) or physical replication (for minor version upgrades in PostgreSQL).
  • RDS DB instances in the green environment can be changed without affecting production workloads. Changes can include the upgrade of major or minor DB engine versions, upgrade of underlying file system configuration, or change of database parameters in the staging environment.
  • Changes can be thoroughly tested in the green environment and when ready, the environments can be switched over to promote the green environment to be the new production environment.
  • Switchover typically takes under five seconds for single-Region configurations with no data loss and no need for application changes. Applications using the AWS Advanced JDBC Driver typically see two seconds or lower downtime.
  • Blue/Green Deployments are supported for RDS for MariaDB, RDS for MySQL, and RDS for PostgreSQL.
  • For Amazon Aurora, Blue/Green Deployments are supported for Aurora MySQL, Aurora PostgreSQL, and Aurora Global Database.

RDS Blue/Green Deployment

RDS Blue/Green Deployments Benefits

  • Easily create a production-ready staging environment.
  • Automatically replicate database changes from the production environment to the staging environment.
  • Test database changes in a safe staging environment without affecting the production environment.
  • Stay current with database patches and system updates.
  • Implement and test newer database features.
  • Switch over your staging environment to be the new production environment without changes to your application.
  • Safely switch over through the use of built-in switchover guardrails.
  • Eliminate data loss during switchover.
  • Switch over quickly, typically under five seconds for single-Region configurations.

RDS Blue/Green Deployment Switchover

  • A switchover transitions the green environment to be the new production environment.
  • Before switchover, production traffic is routed to the blue environment. After switchover, production traffic is routed to the green environment.
  • RDS renames the DB instances in the green environment to match the corresponding blue environment names, and renames the blue environment instances by appending -oldN to the current name.
  • Endpoints in the green environment are renamed to match the blue environment so no application changes are required.
  • A switchover timeout period can be specified between 30 seconds and 3,600 seconds (one hour). Default is 300 seconds (five minutes). If switchover takes longer, changes are rolled back.

Switchover Actions

  • Runs guardrail checks to verify both environments are ready for switchover.
  • Stops new write operations on the primary DB instance in both environments.
  • Drops connections to the DB instances in both environments and disallows new connections.
  • Waits for replication to catch up in the green environment so it is in sync with the blue environment.
  • Renames DB instances in both environments (green gets production names, blue gets -oldN suffix).
  • Allows connections to databases in both environments.
  • Allows write operations on the primary DB instance in the new production environment.

Switchover Guardrails

  • Amazon RDS runs guardrail checks to test the readiness of both environments before switchover.
  • Green environment checks:
    • Replication health – Checks if green primary DB instance replication status is healthy.
    • Replication lag – Checks if the replica lag is within allowable limits based on the specified timeout period.
    • Active writes – Makes sure there are no active writes on the green primary DB instance.
  • Blue environment checks:
    • External replication – Makes sure the blue environment isn’t a self-managed logical source or replica.
    • Long-running active writes – Makes sure there are no long-running active writes on the blue primary DB instance.
    • Long-running DDL statements – Makes sure there are no long-running DDL statements on the blue primary DB instance.
    • Unsupported PostgreSQL changes (logical replication) – Makes sure no DDL changes or large object modifications have been performed.
  • If guardrails fail, the switchover is blocked and environments remain unchanged.

After Switchover

  • DB instances in the previous blue environment are retained (standard costs apply).
  • Replication between blue and green environments stops.
  • The old blue environment DB instances are read-only until the read_only parameter (MySQL) or default_transaction_read_only parameter (PostgreSQL) is set to 0.
  • Resource IDs don’t change during switchover, but names do. Update resource IDs used in IAM policies, Performance Insights, CloudTrail, and AWS Backup.

RDS Proxy with Blue/Green Deployments

  • (New – April 2026) Amazon RDS Blue/Green Deployments now supports Amazon RDS Proxy, enabling faster application recovery during switchover by eliminating DNS propagation delays.
  • During switchover, RDS Proxy actively monitors database instances and detects when the Green environment becomes the new production environment.
  • RDS Proxy quickly redirects connections to the Green environment, enabling faster application recovery without driver modifications or application changes.
  • During the transitional period, the Blue database enters read-only mode before Green environment is promoted. RDS Proxy continues routing connections to the blue database during this period.
  • Once switchover is detected, the proxy automatically routes traffic to the newly promoted green environment.
  • When the Green environment is promoted, existing connections to the proxy are dropped and applications must re-establish connections.
  • Available for Aurora MySQL, Aurora PostgreSQL, RDS for MySQL, RDS for PostgreSQL, and RDS for MariaDB in all commercial AWS Regions where RDS Proxy is available.
  • Limitation: RDS Proxy with Blue/Green Deployments is not supported for Aurora Global Databases.
  • Note: The blue cluster must be registered with the proxy before creating a blue/green deployment. If a deployment already exists for a given blue cluster, registering it to RDS Proxy will be blocked.

AWS Advanced JDBC Driver with Blue/Green Deployments

  • (New – January/February 2026) Blue/Green Deployments support the AWS Advanced JDBC Driver (for PostgreSQL) as a smart driver alternative for faster switchover.
  • The AWS Advanced JDBC Driver detects topology changes and redirects connections to the new production environment without waiting for DNS propagation.
  • Applications using the AWS Advanced JDBC Driver typically see two seconds or lower downtime during switchover.
  • The blue/green deployment plugin in the driver provides automatic connection management during database switchovers.
  • Note: The AWS JDBC Driver for MySQL is NOT supported for blue/green deployments.

PostgreSQL Replication Methods

  • (Updated – November 2024) RDS for PostgreSQL Blue/Green Deployments now use physical replication by default for minor version upgrades.
  • Physical replication is used when no major version upgrade is specified at creation time.
  • Logical replication is used when a major version upgrade is specified during blue/green deployment creation.
  • Physical replication benefits:
    • Overcomes most limitations of logical replication.
    • Well-suited for minor version upgrades, schema changes (DDL) in the blue environment, and storage adjustments.
    • Does not support table modifications on the green instance (green is strictly read-only).
  • Logical replication limitations:
    • DDL statements (CREATE TABLE, CREATE SCHEMA) are not replicated from blue to green.
    • DCL statements (GRANT, REVOKE) are not replicated.
    • Large objects in the blue environment are not replicated to the green environment.
    • Unlogged tables are not replicated.
    • Materialized views are not automatically refreshed in the green environment.
    • UPDATE and DELETE operations require tables to have a primary key.
    • The apply process is single-threaded, which may cause lag with high write throughput.

Aurora Global Database Support

  • (New – November 2025) RDS Blue/Green Deployments now supports Aurora Global Database for safer, simpler, and faster updates.
  • Blue/Green Deployments for Aurora Global Database creates a staging (green) environment that mirrors the production (blue) Aurora Global Database, including primary and all secondary regions.
  • Eliminates complex cross-Region orchestration and manual endpoint coordination that was previously required for self-managed multi-Region blue/green deployments.
  • Switchover safely using built-in switchover guardrails with downtime typically under one minute for global configurations.
  • Available for Aurora MySQL and Aurora PostgreSQL Global Database configurations.

RDS Blue/Green Deployments Limitations

  • Blue/Green Deployments are supported only for RDS for MariaDB, RDS for MySQL, and RDS for PostgreSQL (not supported for RDS for Oracle or RDS for SQL Server).
  • Blue/Green Deployments don’t support managing master user passwords with AWS Secrets Manager.
  • If dedicated log volume (DLV) is enabled on the blue database, it must be enabled on all DB instances, including read replicas.
  • During switchover, zero-ETL integrations with Amazon Redshift must be deleted first, then recreated after switchover.
  • The Event Scheduler (event_scheduler parameter) must be disabled on the green environment when creating a deployment.
  • Cannot change an unencrypted DB instance into an encrypted one (or vice versa).
  • Cannot change a blue DB instance to a higher engine version than its corresponding green DB instance.
  • Not supported for:
    • Cascading read replicas
    • Cross-Region read replicas
    • CloudFormation
    • Multi-AZ DB cluster deployments (supported for Multi-AZ DB instance deployments)
  • After switchover, AWS DMS replication tasks can’t resume because the checkpoint from the blue environment is invalid in the green environment. You must recreate the DMS task.

RDS Blue/Green Deployments Best Practices

  • Thoroughly test resources in the green environment before switchover.
  • Monitor relevant CloudWatch metrics (DatabaseConnections, ReplicaLag) before switchover.
  • Schedule switchover during lowest traffic periods.
  • Ensure replica lag is close to zero before initiating switchover.
  • Ensure network and client DNS cache TTL is not set beyond five seconds.
  • Ensure data loading is complete before switchover (lazy loading/storage initialization).
  • For PostgreSQL with logical replication, run ANALYZE operation to refresh pg_statistics before switchover.
  • Reduce active connections to minimum necessary before switchover for faster completion.
  • Verify that the application does not override the default_transaction_read_only parameter at the session level (for PostgreSQL).

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. A company runs a critical production database on Amazon RDS for PostgreSQL with Multi-AZ deployment. They need to perform a major version upgrade with minimal downtime and no data loss. The application connects directly to the database endpoint. Which approach provides the LOWEST downtime for this upgrade?
    1. Create a read replica, promote it, and point the application to the new instance
    2. Use RDS Blue/Green Deployments to create a staging environment, test the upgrade, and switchover
    3. Take a snapshot, restore it with the new engine version, and update the application endpoint
    4. Perform an in-place major version upgrade during a maintenance window

    Answer: b. RDS Blue/Green Deployments create a staging environment with the upgraded version, keep it in sync via replication, and perform switchover with typically under 5 seconds downtime for single-Region configurations.

  2. A database administrator is planning to use Amazon RDS Blue/Green Deployments for a minor version upgrade on an RDS for PostgreSQL instance. Which type of replication does RDS use to keep the green environment in sync with the blue environment for this scenario?
    1. Logical replication
    2. Physical replication
    3. AWS Database Migration Service
    4. Snapshot-based synchronization

    Answer: b. Since November 2024, RDS Blue/Green Deployments for PostgreSQL minor version upgrades use physical replication by default. Logical replication is used when a major version upgrade is specified.

  3. A company wants to minimize application downtime during an RDS Blue/Green Deployment switchover. Their application uses connection pooling. Which TWO approaches reduce switchover downtime? (Select TWO)
    1. Use Amazon RDS Proxy with the blue/green deployment
    2. Increase the switchover timeout to maximum
    3. Use the AWS Advanced JDBC Driver with the blue/green deployment plugin
    4. Enable Multi-AZ on the green environment
    5. Increase the DNS TTL to 300 seconds

    Answer: a, c. RDS Proxy and the AWS Advanced JDBC Driver both detect topology changes during switchover and redirect connections without waiting for DNS propagation, reducing downtime. RDS Proxy provides sub-5-second recovery, while the JDBC Driver provides ~2-second recovery.

  4. A company uses Amazon RDS Blue/Green Deployments with RDS for MySQL. During the switchover, which actions does Amazon RDS perform? (Select THREE)
    1. Runs guardrail checks to verify both environments are ready
    2. Stops new write operations on the primary DB instance in both environments
    3. Creates a new snapshot of the blue environment
    4. Deletes the blue environment instances
    5. Waits for replication to catch up in the green environment
    6. Upgrades the engine version automatically

    Answer: a, b, e. During switchover, RDS runs guardrail checks, stops writes on both environments, drops connections, waits for replication to catch up, renames instances, and then allows connections and writes on the new production environment. The blue environment is NOT deleted – it is retained with -oldN suffix.

  5. Which of the following are limitations of Amazon RDS Blue/Green Deployments? (Select THREE)
    1. Not supported for RDS for Oracle
    2. Not supported for Multi-AZ DB instance deployments
    3. Not supported for cross-Region read replicas
    4. Cannot change an unencrypted DB instance to an encrypted one
    5. Not supported for RDS for PostgreSQL
    6. Not supported for Multi-AZ DB cluster deployments

    Answer: a, c, d. Blue/Green Deployments don’t support RDS for Oracle (or SQL Server), cross-Region read replicas, or changing encryption status. They DO support Multi-AZ DB instance deployments (not cluster deployments) and RDS for PostgreSQL.

  6. An organization uses Amazon Aurora Global Database for their multi-Region application. They need to perform an engine version upgrade. How can they use Blue/Green Deployments for this scenario?
    1. Blue/Green Deployments don’t support Aurora Global Database
    2. Create separate Blue/Green Deployments in each Region and coordinate switchover manually
    3. Use fully managed Blue/Green Deployments for Aurora Global Database which mirrors primary and all secondary regions
    4. Convert to single-Region Aurora, perform Blue/Green Deployment, then recreate Global Database

    Answer: c. Since November 2025, RDS Blue/Green Deployments supports Aurora Global Database. It creates a staging (green) environment that mirrors the production (blue) Aurora Global Database, including primary and all secondary regions, with built-in switchover guardrails.

References

AWS RDS Security

AWS RDS Security

  • AWS RDS Security provides multiple features
    • DB instance can be hosted in a VPC for the greatest possible network access control.
    • IAM policies can be used to assign permissions that determine who is allowed to manage RDS resources.
    • Security groups allow control of what IP addresses or EC2 instances can connect to the databases on a DB instance.
    • RDS supports encryption in transit using SSL/TLS connections
    • RDS supports encryption at rest to secure instances and snapshots at rest.
    • Network encryption and transparent data encryption (TDE) with Oracle DB instances
    • Authentication can be implemented using Password, Kerberos, and IAM database authentication.
    • Database Activity Streams provide near real-time monitoring and auditing of database activity.
    • RDS Proxy provides connection pooling with IAM authentication and Secrets Manager integration.

RDS IAM and Access Control

  • IAM can be used to control which RDS operations each individual user has permission to call.
  • IAM policies can grant or deny access to specific RDS resources based on conditions such as tags, IP addresses, or VPC.
  • Service-linked roles allow RDS to make calls to other AWS services on your behalf.

RDS Authentication Methods

  • RDS supports multiple authentication methods:
    • Password authentication – Traditional database username/password.
    • IAM database authentication – Token-based authentication using IAM credentials (MySQL, PostgreSQL, MariaDB).
    • Kerberos authentication – Single sign-on using Microsoft Active Directory. Supported for Db2, PostgreSQL, MySQL, Oracle, and SQL Server.
  • Kerberos authentication integrates with AWS Managed Microsoft AD or on-premises AD via forest trust for centralized authentication.

RDS Encryption at Rest

  • RDS encrypted instances use the industry-standard AES-256 encryption algorithm to encrypt data on the server that hosts the RDS instance.
  • RDS handles authentication of access and decryption of the data with a minimal impact on performance, and with no need to modify the database client applications
  • Data at Rest Encryption
    • can be enabled on RDS instances to encrypt the underlying storage
    • encryption keys are managed by KMS
    • can be enabled only during instance creation
    • once enabled, the encryption keys cannot be changed
    • if the key is lost, the DB can only be restored from the backup
    • supports both AWS managed keys and customer managed keys (CMKs)
    • supports multi-Region KMS keys for cross-region snapshot copy and disaster recovery scenarios
  • Once encryption is enabled for an RDS instance,
    • logs are encrypted
    • snapshots are encrypted
    • automated backups are encrypted
    • read replicas are encrypted
  • Encrypted snapshots can be copied to another region by specifying a KMS key valid in the destination AWS Region. It can be a Region-specific KMS key, or a multi-Region key.
  • Cross-Region and Cross-Account Snapshot Copy (Sep 2025) – RDS now supports copying snapshots across Regions and accounts directly in a single step, without performing it sequentially as two separate copies.
  • RDS DB Snapshot considerations
    • DB snapshot encrypted using a KMS encryption key can be copied
    • Copying an encrypted DB snapshot results in an encrypted copy of the DB snapshot
    • When copying, the DB snapshot can either be encrypted with the same KMS encryption key as the original DB snapshot, or a different KMS encryption key to encrypt the copy of the DB snapshot.
    • An unencrypted DB snapshot can be copied to an encrypted snapshot, to add encryption to a previously unencrypted DB instance.
    • Encrypted snapshot can be restored only to an encrypted DB instance
    • If a KMS encryption key is specified when restoring from an unencrypted DB cluster snapshot, the restored DB cluster is encrypted using the specified KMS encryption key
    • Copying an encrypted snapshot shared from another AWS account requires access to the KMS encryption key used to encrypt the DB snapshot.
  • Transparent Data Encryption (TDE)
    • Automatically encrypts the data before it is written to the underlying storage device and decrypts when it is read from the storage device
    • is supported by Oracle and SQL Server
      • Oracle requires key storage outside of the KMS and integrates with CloudHSM for this
      • SQL Server requires a key but is managed by RDS

RDS Encryption in Transit – SSL/TLS

  • Encrypt connections using SSL/TLS for data in transit between the applications and the DB instance
  • RDS creates an SSL certificate and installs the certificate on the DB instance when RDS provisions the instance.
  • SSL certificates are signed by a certificate authority. SSL certificate includes the DB instance endpoint as the Common Name (CN) for the SSL certificate to guard against spoofing attacks
  • While SSL offers security benefits, be aware that SSL/TLS encryption is a compute-intensive operation and will increase the latency of the database connection.
  • For encrypted and unencrypted DB instances, data that is in transit between the source and the read replicas is encrypted, even when replicating across AWS Regions.
  • Certificate Authority (CA) Updates
    • The older rds-ca-2019 certificates expired in August 2024.
    • AWS introduced new CA certificates in December 2022:
      • rds-ca-rsa2048-g1 – RSA 2048-bit key, valid for 40 years (default for new instances since January 2024)
      • rds-ca-rsa4096-g1 – RSA 4096-bit key, valid for 100 years
      • rds-ca-ecc384-g1 – ECC 384-bit key, valid for 100 years
    • Using the new CA certificates, Amazon RDS manages automatic rotation of the DB server certificate before it expires.
    • New DB instances created after January 26, 2024 use rds-ca-rsa2048-g1 by default.
  • RDS supports enforcing SSL/TLS connections using parameter groups (e.g., rds.force_ssl = 1 for PostgreSQL, require_secure_transport = ON for MySQL).

IAM Database Authentication

  • IAM database authentication works with MySQL, PostgreSQL, and MariaDB.
  • IAM database authentication prevents the need to store static user credentials in the database because authentication is managed externally using IAM.
  • Authorization still happens within RDS (not IAM).
  • IAM database authentication does not require a password but needs an authentication token
  • An authentication token is a unique string of characters that RDS generates on request.
  • Authentication tokens are generated using AWS Signature Version 4.
  • Each Authentication token has a lifetime of 15 minutes
  • IAM database authentication provides the following benefits:
    • Network traffic to and from the database is encrypted using SSL/TLS.
    • Helps centrally manage access to the database resources, instead of managing access individually on each DB instance.
    • Enables using IAM Roles to access the database instead of a password, for greater security.
  • Enhanced Observability (Feb 2025) – RDS IAM DB Authentication now provides metrics and logs for improved troubleshooting:
    • CloudWatch metrics for IAM DB Auth connection attempts, successes, and failures.
    • IAM DB Auth error logs can be exported to CloudWatch Logs for investigation and resolution of authentication issues.

RDS Proxy Security

  • RDS Proxy is a fully managed, highly available database proxy that makes applications more scalable, resilient, and secure.
  • RDS Proxy sits between the application and the database, pooling and sharing established database connections.
  • Security features of RDS Proxy:
    • IAM Authentication – Enforces IAM authentication for client-to-proxy connections, eliminating the need for database credentials in application code.
    • Secrets Manager Integration – Proxy retrieves database credentials from AWS Secrets Manager, and you never need to expose credentials to your application.
    • TLS/SSL Enforcement – Supports encrypted connections between client and proxy, and between proxy and database.
    • VPC Security – RDS Proxy runs within your VPC and can be restricted using security groups.
  • End-to-End IAM Authentication (Sep 2025) – RDS Proxy now supports end-to-end IAM authentication where both client-to-proxy and proxy-to-database connections use IAM authentication, providing a fully passwordless database access solution.
  • RDS Proxy automatically handles failover, routing requests to the new primary instance without disrupting application connections.

Database Activity Streams

  • Database Activity Streams provide a near real-time stream of database activity for monitoring and auditing.
  • Supported for RDS for Oracle and RDS for SQL Server (also Aurora PostgreSQL and Aurora MySQL).
  • How it works:
    • RDS pushes database activity events to an Amazon Kinesis Data Stream in near real time.
    • The Kinesis stream is created automatically when enabling the feature.
    • From Kinesis, configure services like Amazon Data Firehose and Lambda to consume, store, and analyze the data.
  • Key benefits:
    • Separation of Duties – DBAs cannot access or modify the activity stream; encryption is managed via KMS keys controlled by security teams.
    • Compliance – Helps meet regulatory and compliance requirements for database auditing (SOX, PCI, HIPAA).
    • Integration – Works with partner security tools like IBM Guardium, Imperva, and McAfee for automated alerting.
  • Operates in asynchronous mode – database activity is recorded without impacting database performance (with a small delay).
  • Use of Database Activity Streams is free; you pay only for the underlying Kinesis data stream.

RDS Security Groups

  • Security groups control the access that traffic has in and out of a DB instance
  • VPC security groups act like a firewall controlling network access to your DB instance.
  • VPC security groups can be configured and associated with the DB instance to allow access from an IP address range, port, or EC2 security group
  • Database security groups default to a “deny all” access mode and customers must specifically authorize network ingress.
  • RDS supports dual-stack mode (IPv4 and IPv6) for DB instances in VPCs, including publicly accessible databases (Oct 2025 expansion).

RDS Secrets Manager Integration

  • RDS supports AWS Secrets Manager to manage and automatically rotate database credentials.
  • Native RDS Integration with Secrets Manager (2023+)
    • RDS offers built-in integration where Amazon RDS manages the master database credentials in Secrets Manager automatically.
    • When enabled, RDS generates the password, stores it as an encrypted managed secret, and rotates it automatically on a configurable schedule.
    • You never see or manage the master password directly.
    • Can be enabled during instance creation or later by modifying the instance.
    • The managed secret is encrypted with a KMS key you own and control.
  • Custom Secrets Manager rotation (for non-master credentials):
    • Uses a Lambda function to rotate credentials.
    • Built-in rotation templates for MySQL, PostgreSQL, MariaDB, Oracle, SQL Server, and Db2.
    • Supports single-user and multi-user rotation strategies.
  • Secrets Manager benefits:
    • Rotate secrets safely without disrupting applications.
    • Manage secrets centrally with fine-grained IAM policies.
    • Encrypt secrets with KMS keys you own and control.
    • Audit access via CloudTrail integration.
    • Pay as you go – per secret stored and API calls made.

Master User Account Privileges

  • When you create a new DB instance, the default master user that is used gets certain privileges for that DB instance
  • Subsequently, other users with permissions can be created.
  • Master user credentials can now be managed by AWS Secrets Manager for improved security (no direct password management).

Event Notification

  • Event notifications can be configured for important events that occur on the DB instance
  • Notifications of a variety of important events that can occur on the RDS instance, such as whether the instance was shut down, a backup was started, a failover occurred, the security group was changed, or your storage space is low can be received
  • RDS sends event notifications via Amazon SNS, and can trigger Lambda functions or other automated responses.

RDS Encrypted DB Instances Limitations

  • RDS Encryption can be enabled only during the creation of an RDS DB instance, not after the DB instance is created.
  • DB instances that are encrypted can’t be modified to disable encryption.
  • Encrypted snapshot of an unencrypted DB instance cannot be created.
  • An unencrypted backup or snapshot can’t be restored to an encrypted DB instance.
  • An unencrypted DB instance or an unencrypted read replica of an encrypted DB instance can’t have an encrypted read replica.
  • DB snapshot of an encrypted DB instance must be encrypted using the same KMS key as the DB instance.
  • Encrypted read replicas must be encrypted with the same KMS key as the source DB instance when both are in the same AWS Region.
  • For encrypting an unencrypted RDS database, the following approaches can be used:
    • Using Snapshots (requires downtime):
      • Create a DB snapshot of the DB instance, which would be unencrypted.
      • Copy the unencrypted DB snapshot to an encrypted snapshot.
      • Restore a DB instance from the encrypted snapshot, which would be an encrypted DB instance.
    • Using AWS DMS (minimal to no downtime): Use AWS Database Migration Service (AWS DMS) to migrate and continuously replicate the data so that the cutover to the new, encrypted database is seamless.

RDS API with Interface Endpoints (AWS PrivateLink)

  • AWS PrivateLink enables you to privately access RDS API operations without an internet gateway, NAT device, VPN connection, or AWS Direct Connect connection.
  • DB instances in the VPC don’t need public IP addresses to communicate with RDS API endpoints to launch, modify, or terminate DB instances.
  • DB instances also don’t need public IP addresses to use any of the available RDS API operations.
  • Traffic between the VPC and RDS doesn’t leave the Amazon network.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. Can I encrypt connections between my application and my DB Instance using SSL?
    1. No
    2. Yes
    3. Only in VPC
    4. Only in certain regions
  2. Which of these configuration or deployment practices is a security risk for RDS?
    1. Storing SQL function code in plaintext
    2. Non-Multi-AZ RDS instance
    3. Having RDS and EC2 instances exist in the same subnet
    4. RDS in a public subnet (Making RDS accessible to the public internet in a public subnet poses a security risk, by making your database directly addressable and spammable. DB instances deployed within a VPC can be configured to be accessible from the Internet or from EC2 instances outside the VPC. If a VPC security group specifies a port access such as TCP port 22, you would not be able to access the DB instance because the firewall for the DB instance provides access only via the IP addresses specified by the DB security groups the instance is a member of and the port defined when the DB instance was created. Refer link)
  3. A company needs to encrypt an existing unencrypted RDS database with minimal downtime. Which approach should they use?
    1. Enable encryption on the existing instance via the console
    2. Create an unencrypted snapshot, copy it as encrypted, and restore
    3. Use AWS DMS to migrate data to a new encrypted RDS instance (AWS DMS enables continuous replication to the encrypted target, minimizing downtime during cutover. The snapshot approach requires downtime during restore.)
    4. Modify the DB instance to add a KMS key
  4. A security team requires near real-time auditing of all database activity on an RDS Oracle instance, with separation of duties ensuring DBAs cannot tamper with audit records. Which feature should they use?
    1. CloudTrail data events for RDS
    2. RDS Enhanced Monitoring
    3. Database Activity Streams (Database Activity Streams push activity to a Kinesis stream encrypted with a KMS key controlled by security teams, ensuring DBAs cannot access or modify audit records.)
    4. RDS Performance Insights
  5. Which authentication methods does Amazon RDS support? (Choose THREE)
    1. Password authentication
    2. IAM database authentication
    3. Kerberos authentication with Active Directory
    4. SAML-based authentication
    5. OAuth 2.0 authentication
  6. A company wants to eliminate database passwords entirely for their serverless application connecting to RDS PostgreSQL through RDS Proxy. Which approach achieves this?
    1. Store credentials in environment variables
    2. Use Secrets Manager integration only
    3. Configure RDS Proxy with end-to-end IAM authentication (Since September 2025, RDS Proxy supports end-to-end IAM authentication where both client-to-proxy and proxy-to-database connections use IAM, providing a fully passwordless solution.)
    4. Use Lambda authorizers with RDS
  7. An organization needs to automatically manage and rotate their RDS master user password without using Lambda functions. Which solution requires the least operational effort?
    1. Create a Secrets Manager secret and configure Lambda rotation
    2. Enable the native RDS integration with Secrets Manager to manage the master user password (RDS natively manages the master password in Secrets Manager including automatic rotation, without requiring custom Lambda functions.)
    3. Use IAM database authentication instead of passwords
    4. Store the password in Systems Manager Parameter Store with rotation
  8. After the rds-ca-2019 certificate expired in August 2024, which certificate authority should new RDS instances use by default?
    1. rds-ca-2019
    2. rds-ca-rsa2048-g1 (New instances created after January 26, 2024 use rds-ca-rsa2048-g1 by default, which is valid for 40 years.)
    3. rds-ca-rsa4096-g1
    4. rds-ca-ecc384-g1

📖 Related: AWS RDS Backup, Snapshots & Restore – Complete Guide

References

RDS Automated Backups vs Manual Snapshots

RDS Automated Backups vs Manual Snapshots

RDS Automated Backups vs Manual Snapshots

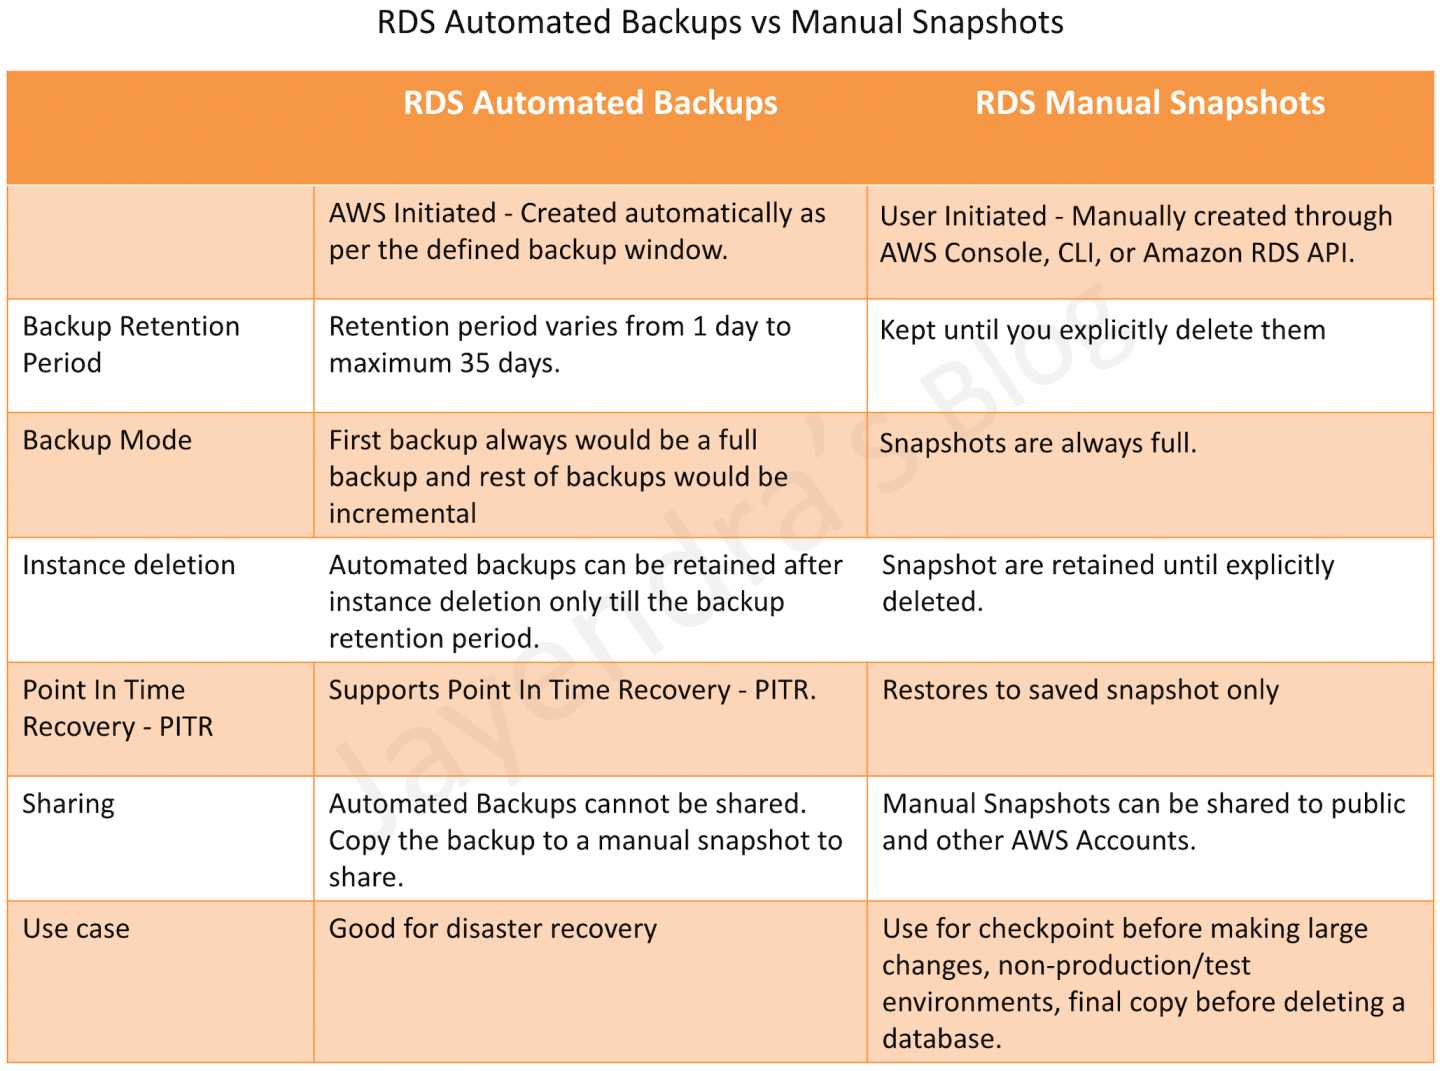
RDS automated backups vs manual snapshots — quick answer: Automated backups are AWS-initiated on a daily backup window, retain 0–35 days, keep transaction logs so they support Point-In-Time Recovery (PITR), and are deleted when the DB instance is deleted (unless you explicitly retain them). Manual snapshots are user-initiated, never expire (kept until you delete them), can be shared and copied across accounts/Regions, but restore only to the snapshot point — no PITR. Rule of thumb: rely on automated backups + PITR for day-to-day recovery; take a manual snapshot before risky changes or to keep a backup beyond 35 days / past instance deletion.
  • Amazon RDS Automated Backups are AWS Initiated. Backups are created automatically as per the defined backup window. Backups are also created when a read replica is created.
  • Amazon RDS DB snapshots are manual, user-initiated backups that enable a DB instance backup to be restored to that specific state at any time.

RDS Automated Backups vs Manual Snapshots

Instance Deletion & Backup Retention Period

  • Amazon RDS Backups can be configured with a retention period varying from 0 to 35 days. Setting to 0 disables automated backups (not recommended for production).
  • RDS Automated Backups are deleted when the DB instance is deleted. However, RDS can be configured to retain the automated backups on RDS instance deletion. These backups would be retained only till their retention window.
  • RDS Snapshots don’t expire and RDS keeps all manual DB snapshots until explicitly deleted and aren’t subject to the backup retention period.

Backup Mode

  • RDS Automated Backups are incremental. The first snapshot of a DB instance contains the data for the full database. Subsequent backups of the same database are incremental, meaning only the data that has changed after the most recent backup is saved.
  • RDS Manual Snapshots are also incremental. Only the blocks on the device that have changed after the most recent snapshot are saved, reducing both the time to create the snapshot and storage costs by not duplicating data.

Point In Time Recovery – PITR

  • RDS Automated Backups with transaction logs help support Point In Time Recovery – PITR. You can restore your DB instance to any second during the retention period, up to the LatestRestorableTime (typically within the last 5 minutes).
  • RDS Snapshots restores to saved snapshot data only. It cannot be used for PITR.

Sharing

  • RDS Automated Backups cannot be shared directly. You can copy the automated backup to a manual snapshot to share.
  • RDS Manual Snapshots can be shared with the public and with up to 20 other AWS Accounts.

Cross-Region & Cross-Account Capabilities

  • Cross-Region Automated Backup Replication – RDS can replicate automated backups (snapshots and transaction logs) to a chosen destination AWS Region, enabling PITR in a secondary Region for disaster recovery. You can replicate up to 20 backups to each destination Region per account.
  • Cross-Region and Cross-Account Snapshot Copy (2025) – RDS now supports copying snapshots across Regions and accounts directly using a single copy action, eliminating the need for sequential copying steps.
  • AWS Backup Single-Action Copy (Oct 2025) – AWS Backup supports copying RDS, Aurora, Neptune, and DocumentDB snapshots across Regions and accounts in a single action.

AWS Backup Integration

  • AWS Backup provides centralized backup management for RDS with custom schedules, retention periods, and lifecycle policies beyond native RDS backup capabilities.
  • AWS Backup Vault Lock – Provides WORM (Write Once Read Many) immutability for backups, preventing any user from deleting backups or changing lifecycle settings. Helps meet compliance requirements.
  • Logically Air-Gapped Vault (GA Aug 2024) – A specialized vault type that stores immutable backup copies in service-owned accounts, encrypted with AWS-owned keys. Supports secure sharing across accounts and direct restore for faster recovery.
  • Multi-AZ Cluster Support (March 2026) – AWS Backup expanded support for RDS Multi-AZ clusters to 17 Regions, including automated lifecycle management and immutable backups with Vault Lock.

Backup Configuration on Restore (Feb 2026)

  • RDS and Aurora now allow you to view and modify the backup retention period and preferred backup window prior to and upon restoring database snapshots, providing visibility into backup configurations before initiating restore operations.

Use case

  • RDS Automated Backups are good for disaster recovery and compliance requirements with PITR capability.
  • Cross-Region Automated Backup Replication is ideal for cross-region disaster recovery with minimal RPO.
  • RDS Snapshots can be used for checkpoint before making large changes, non-production/test environments, and final copy before deleting a database.
  • AWS Backup with Vault Lock is recommended for ransomware protection and regulatory compliance requiring immutable backups.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. You receive a frantic call from a new DBA who accidentally dropped a table containing all your customers. Which Amazon RDS feature will allow you to reliably restore your database within 5 minutes of when the mistake was made?
    1. Multi-AZ RDS
    2. RDS snapshots
    3. RDS read replicas
    4. RDS automated backup
  2. A company requires that their RDS database backups be protected from accidental or malicious deletion, including from administrators with root access. Which AWS solution provides immutable backup protection?
    1. RDS automated backups with 35-day retention
    2. RDS manual snapshots shared to another account
    3. AWS Backup with Vault Lock in compliance mode
    4. Cross-Region automated backup replication
  3. A company needs to restore their RDS database in a secondary AWS Region if the primary Region becomes unavailable, with a Recovery Point Objective (RPO) of minutes. Which feature should they use?
    1. Manual snapshot copy to another Region
    2. Cross-Region Automated Backup Replication
    3. RDS Read Replica in another Region
    4. AWS Backup with cross-account copy

References

RDS Cross-Region Read Replicas – DR & Scaling

Cross-Region Read Replicas

RDS Cross-Region Read Replicas

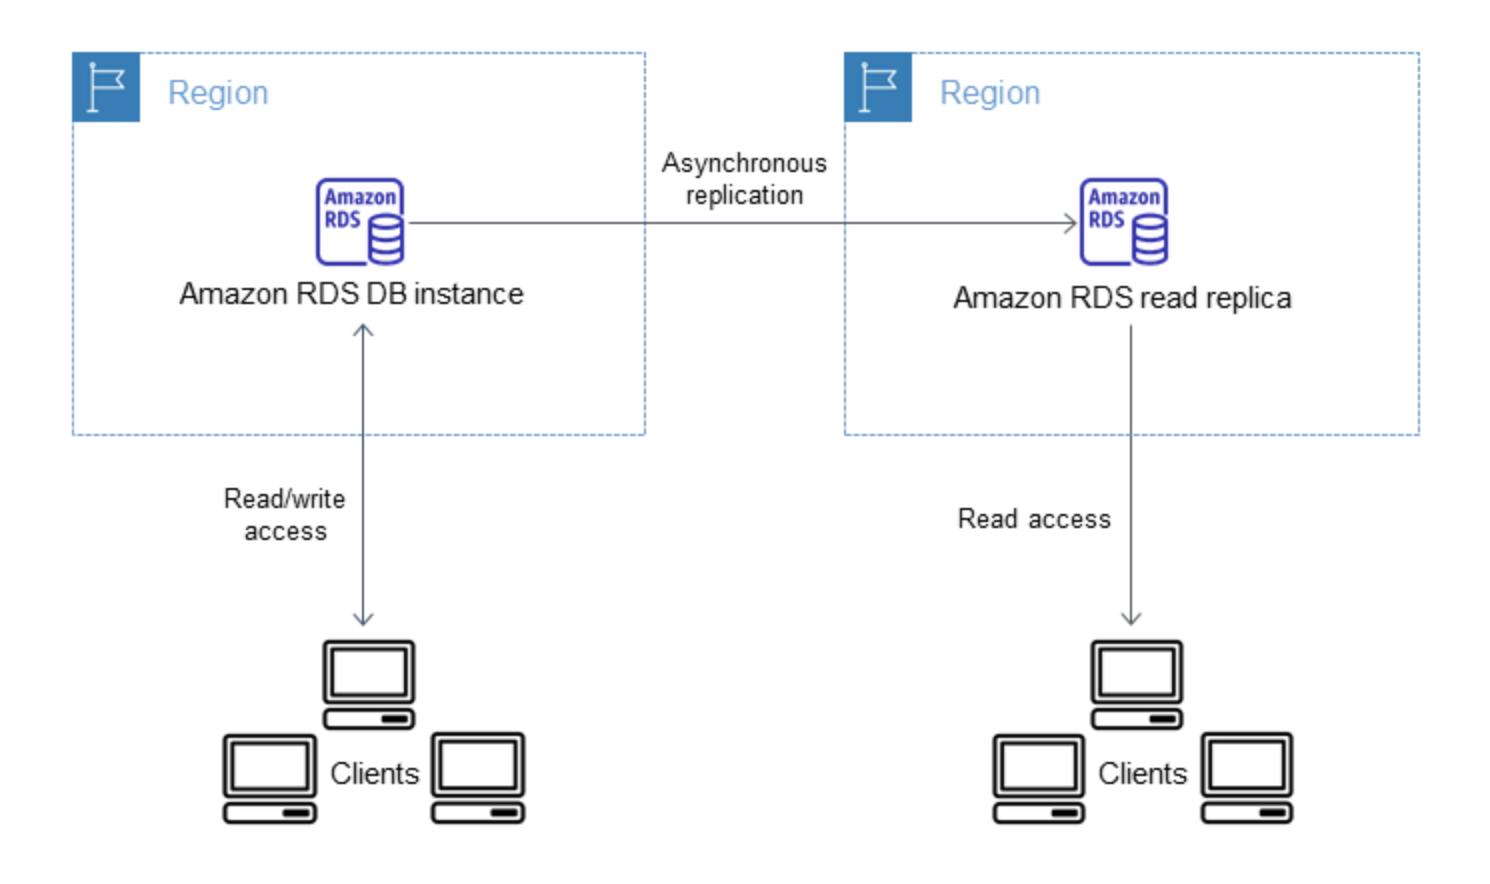
  • RDS Cross-Region Read Replicas create an asynchronously replicated read-only DB instance in a secondary AWS Region.
  • Supported for MySQL, PostgreSQL, MariaDB, Oracle, SQL Server, and Db2
  • Cross-Region Read Replicas help to improve
    • disaster recovery capabilities (reduces RTO and RPO),
    • scale read operations into a region closer to end users,
    • migration from a data center in one region to another region
  • You can create up to 15 in-Region and cross-Region read replicas combined per source DB instance.
  • Due to the limit on the number of access control list (ACL) entries for the source VPC, RDS can’t guarantee more than five cross-Region read replica DB instances.

Cross-Region Read Replicas

RDS Cross-Region Read Replicas Process

  • RDS configures the source DB instance as a replication source and setups the specified read replica in the destination AWS Region.
  • RDS creates an automated DB snapshot of the source DB instance in the source AWS Region.
  • RDS begins a cross-Region snapshot copy for the initial data transfer.
  • RDS then uses the copied DB snapshot for the initial data load on the read replica. When the load is complete the DB snapshot copy is deleted.
  • RDS starts by replicating the changes made to the source instance since the start of the create read replica operation.

RDS Cross-Region Read Replicas Considerations

  • A source DB instance can have cross-region read replicas in multiple AWS Regions.
  • You can create up to 15 in-Region and cross-Region read replicas combined per source DB instance (applies to MySQL, MariaDB, PostgreSQL, Oracle, SQL Server, and Db2).
  • Due to the limit on the number of access control list (ACL) entries for the source VPC, RDS can’t guarantee more than five cross-Region read replica DB instances.
  • Replica lags are higher for Cross-region replicas. This lag time comes from the longer network channels between regional data centers.
  • Read Replica uses the default DB parameter group and DB option group for the specified DB engine when configured from AWS console. For MySQL and Oracle DB engines, you can specify a custom parameter group via CLI/API. For Db2, you must specify a custom parameter group that includes your IBM Site ID and Customer ID.
  • Read Replica uses the default security group.
  • Cross-Region RDS read replica can be created from a source RDS DB instance that is not a read replica of another RDS DB instance for Db2, Microsoft SQL Server, Oracle, and PostgreSQL DB instances (versions lower than 14.1). This limitation doesn’t apply to MariaDB, MySQL, and PostgreSQL 14.1+ DB instances which support cascading cross-region read replicas.
  • Deleting the source for a cross-region read replica will result in
    • read replica promotion for Db2, MariaDB, MySQL, and Oracle DB instances
    • no automatic read replica promotion for PostgreSQL DB instances — the replication status of the read replica is set to terminated. You must promote the read replica manually or delete it.
  • An encrypted read replica in a different AWS Region requires the source DB instance to be encrypted. A KMS key in the destination Region must be specified.
  • You can replicate between the GovCloud (US-East) and GovCloud (US-West) Regions, but not into or out of GovCloud (US).

Cross-Region Cascading Read Replicas

  • MySQL and MariaDB support creating read replicas from other read replicas (cascading), including cross-Region scenarios. This can reduce cross-Region data transfer costs.
  • PostgreSQL 14.1+ supports cross-Region cascading read replicas with up to three levels of cascading.
    • You can create a cross-Region replica from the source, then create same-Region replicas from it.
    • You can also create a same-Region replica from the source, then create cross-Region replicas from it.
  • Cascading replicas help reduce data transfer costs — only the first replica in the chain incurs cross-Region transfer charges.
  • SQL Server, Oracle, and Db2 do not support cascading (creating cross-Region replicas from another replica).

Cross-Region Replication Costs

  • Data transferred for cross-Region replication incurs Amazon RDS data transfer charges.
  • Cross-Region replication actions that generate data transfer out charges:
    • Initial snapshot transfer when creating the read replica
    • Ongoing data modification replication from source to read replica region
  • For MySQL and MariaDB, cascading read replicas can reduce costs — create one cross-Region replica and then create additional replicas from it within the same destination Region (no cross-Region transfer charges for same-Region replication).

Related Cross-Region DR Features (2024-2026 Updates)

Cross-Region Automated Backup Replication

  • RDS supports replicating automated backups (snapshots and transaction logs) to a different AWS Region.
  • Enables point-in-time recovery in the secondary Region with RPO of minutes.
  • You can replicate up to 20 backups to each destination Region per account.
  • Supported for MySQL, PostgreSQL, MariaDB, Oracle, SQL Server, and Db2 (encrypted databases).
  • Not supported for Multi-AZ DB clusters.
  • Expanded to five additional AWS Regions in April 2025.

Cross-Region and Cross-Account Snapshot Copy (September 2025)

  • Amazon RDS now supports copying RDS and Aurora snapshots across Regions and accounts in a single step.
  • Previously required sequential copying (first cross-Region, then cross-account, or vice versa).
  • Protects against ransomware attacks and Region outages by enabling isolated backup environments.

RDS for Db2 Cross-Region Standby Replicas (June 2025)

  • RDS for Db2 introduced cross-Region standby replicas for disaster recovery.
  • Standby replicas don’t accept user connections but provide faster failover for cross-Region DR scenarios.
  • Complements read replicas which are used for read scaling.

RDS for PostgreSQL Delayed Read Replicas (August 2025)

  • Allows specifying a minimum time period that a replica lags behind the source using the recovery_min_apply_delay parameter.
  • Creates a time buffer to protect against accidental data loss (e.g., table drops, unintended modifications).
  • Available with PostgreSQL versions 14.19, 15.14, 16.10, 17.6, and later.
  • Can be promoted to become the new primary for quick recovery within minutes.
  • Works with both in-Region and cross-Region replicas, including cascaded read replicas.

RDS for Oracle Cross-Region Replicas with Additional Storage Volumes (January 2026)

  • Cross-Region replicas for Oracle now support additional storage volumes.
  • Customers can add up to three storage volumes (each up to 64 TiB) in addition to the primary storage volume, totaling up to 256 TiB.
  • Enables scaling Oracle workloads without architecture changes while maintaining cross-Region DR.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. Your company has HQ in Tokyo and branch offices worldwide and is using logistics software with a multi-regional deployment on AWS in Japan, Europe, and US. The logistic software has a 3-tier architecture and uses MySQL 5.6 for data persistence. Each region has deployed its database. In the HQ region, you run an hourly batch process reading data from every region to compute cross-regional reports that are sent by email to all offices this batch process must be completed as fast as possible to optimize logistics quickly. How do you build the database architecture to meet the requirements?
    1. For each regional deployment, use RDS MySQL with a master in the region and a read replica in the HQ region
    2. For each regional deployment, use MySQL on EC2 with a master in the region and send hourly EBS snapshots to the HQ region
    3. For each regional deployment, use RDS MySQL with a master in the region and send hourly RDS snapshots to the HQ region
    4. For each regional deployment, use MySQL on EC2 with a master in the region and use S3 to copy data files hourly to the HQ region
  2. A company has a production database running on RDS for PostgreSQL in us-east-1. They need to provide read access to users in eu-west-1 with minimal latency, and also want the ability to quickly recover from a regional failure. They want to minimize cross-region data transfer costs while having three read replicas available in eu-west-1. What is the most cost-effective architecture?
    1. Create three cross-Region read replicas directly from the source in us-east-1 to eu-west-1
    2. Use Aurora Global Database with three reader instances in eu-west-1
    3. Create one cross-Region read replica in eu-west-1, then create two cascading read replicas from it in the same Region (requires PostgreSQL 14.1+)
    4. Enable cross-Region automated backup replication and restore in eu-west-1 when needed
  3. A solutions architect needs to design a disaster recovery strategy for an RDS for PostgreSQL database. The strategy must allow recovery from accidental data deletions within a 2-hour window while maintaining a separate cross-Region replica for regional failover. Which combination of features provides this capability? (Select TWO)
    1. Enable Multi-AZ deployment in the primary Region
    2. Configure a delayed read replica with recovery_min_apply_delay set to 2 hours
    3. Enable cross-Region automated backup replication
    4. Create a cross-Region read replica for regional failover
    5. Use Aurora Global Database with write forwarding
  4. Which of the following statements about RDS cross-Region read replicas is correct? (Select TWO)
    1. RDS for SQL Server supports cascading cross-Region read replicas
    2. RDS for PostgreSQL 14.1+ supports creating cross-Region read replicas from another read replica (cascading)
    3. When the source is deleted, PostgreSQL cross-Region read replicas are automatically promoted
    4. You can create up to 15 in-Region and cross-Region read replicas combined per source instance
    5. Cross-Region read replicas are synchronously replicated
  5. A company wants to minimize RTO for their RDS for Db2 database during a regional disaster. They need the replica to be ready for immediate failover without serving read traffic. Which approach should they use?
    1. Create a cross-Region read replica and promote it during failover
    2. Create a cross-Region standby replica for faster failover
    3. Enable cross-Region automated backup replication and perform point-in-time recovery
    4. Use AWS DMS for continuous replication to the secondary Region

RDS Multi-AZ vs Read Replica – HA vs Scaling, Key Differences

RDS Multi-AZ vs Read Replica

RDS Multi-AZ vs Read Replica

RDS DB instances replicas can be created in two ways Multi-AZ & Read Replica, which provide high availability, durability, and scalability to RDS.

RDS Multi-AZ vs Read Replica

📌 Update (2025): AWS now offers two Multi-AZ deployment options:

  • Multi-AZ DB Instance – One primary + one standby (non-readable). Failover typically 60–120 seconds.
  • Multi-AZ DB Cluster – One writer + two readable standbys across 3 AZs. Failover typically under 35 seconds. Supported for MySQL and PostgreSQL only.

For a detailed comparison, see RDS Multi-AZ DB Instance vs DB Cluster Deployment.

Purpose

  • Multi-AZ DB Instance deployments provide high availability, durability, and automatic failover support.
  • Multi-AZ DB Cluster deployments provide high availability with readable standbys, faster failover (under 35 seconds), improved write latency, and increased read capacity.
  • Read replicas enable increased scalability and database availability in the case of an AZ failure. Read Replicas allow elastic scaling beyond the capacity constraints of a single DB instance for read-heavy database workloads.

RDS Read Replicas vs Multi-AZ

Region & Availability Zones

  • RDS Multi-AZ DB Instance deployment automatically provisions and manages a standby instance in a different AZ (independent infrastructure in a physically separate location) within the same AWS region.
  • RDS Multi-AZ DB Cluster deployment provisions a writer DB instance and two readable standby DB instances across three different AZs within the same region.
  • RDS Read Replicas can be provisioned within the same AZ, Cross-AZ or even as a Cross-Region replica.

Replication Mode

  • RDS Multi-AZ DB Instance deployment manages a synchronous standby instance in a different AZ.
  • RDS Multi-AZ DB Cluster deployment uses semi-synchronous replication (transaction acknowledged when at least one standby confirms write) for high durability with improved write latency.
  • RDS Read Replicas have data replicated asynchronously from the Primary instance to the read replicas.

Standby Instance can Accept Reads

  • Multi-AZ DB Instance deployment is a high-availability solution and the standby instance does not support read requests.
  • Multi-AZ DB Cluster deployment provides two readable standby instances that can serve read traffic, increasing application read throughput.
  • Read Replica deployment provides readable instances to increase application read-throughput.

Automatic Failover & Failover Time

  • Multi-AZ DB Instance deployment performs an automatic failover to the standby instance without administrative intervention, and the failover time is typically 60–120 seconds based on crash recovery.
    • Planned database maintenance
    • Software patching
    • Rebooting the Primary instance with failover
    • Primary DB instance connectivity or host failure, or an
    • Availability Zone failure
  • Multi-AZ DB Cluster deployment provides automated failover typically under 35 seconds with zero data loss. When combined with RDS Proxy, failover downtime can be reduced to under 1 second.
  • RDS maintains the same endpoint for the DB Instance after a failover, so the application can resume database operation without the need for manual administrative intervention.
  • Read Replica deployment does not provide automatic failover. Read Replica instance needs to be manually promoted to a Standalone instance.

Upgrades

  • For a Multi-AZ DB Instance deployment, database engine version upgrades happen on the Primary instance with downtime of 60–120 seconds for failover.
  • For a Multi-AZ DB Cluster deployment, minor version upgrades can be completed with 35 seconds or less of downtime (under 1 second with RDS Proxy).
  • RDS Blue/Green Deployments provide a safer upgrade mechanism by creating a staging (green) environment, testing changes, and then switching over with typically under 5 seconds of downtime (as of Jan 2026).
  • For Read Replicas, the database engine version upgrade is independent of the Primary instance.

Automated Backups

  • Multi-AZ DB Instance deployment has the Automated Backups taken from the Standby instance (reducing I/O impact on Primary).
  • Multi-AZ DB Cluster deployment takes automated backups from one of the reader instances.
  • Read Replicas do not have any backups configured by default, but automated backups can be enabled on read replicas.

Cascading (Chained) Read Replicas

  • RDS supports creating a Read Replica of another Read Replica (cascading), which helps scale reads without adding overhead to the source DB instance.
  • MySQL: Supports cascading read replicas with up to 3 levels of chaining.
  • PostgreSQL: Supports cascading read replicas from version 14.1 onwards, with up to 3 levels of chaining and 5 replicas per instance (up to 155 total read replicas per source).
  • Cross-Region cascading read replicas are also supported for PostgreSQL.

Delayed Read Replicas (New – 2025)

  • RDS for PostgreSQL now supports delayed read replicas (Aug 2025), allowing you to specify a minimum time period (0 to 24 hours) that a replica lags behind the source.
  • Creates a time buffer that helps protect against accidental data loss from human errors such as table drops or unintended data modifications.
  • When data corruption occurs on primary, the delayed replica can be promoted before the problematic operation is applied, providing recovery within minutes.
  • Configured using the recovery_min_apply_delay parameter.
  • Available with RDS for PostgreSQL versions 14.19, 15.14, 16.10, 17.6 and later.
  • RDS for MySQL also supports delayed replication using the mysql.rds_set_source_delay stored procedure.

RDS Proxy for Improved Failover

  • Amazon RDS Proxy is a fully managed, highly available database proxy that can significantly reduce failover times.
  • RDS Proxy eliminates DNS propagation delay by continuously monitoring both primary and standby instances, allowing faster failover response.
  • When used with Multi-AZ DB Cluster deployments, RDS Proxy can reduce minor version upgrade downtime to under 1 second.
  • RDS Proxy also helps manage connection pooling and reduces database connection overhead for applications using many connections (e.g., Lambda functions).

SQL Server Multi-AZ Replication Technologies

  • RDS for SQL Server supports Multi-AZ using Always On Availability Groups (AGs) for Enterprise and Standard editions.
  • SQL Server Database Mirroring (DBM) was the legacy approach but is deprecated; AWS recommends migrating to Always On AGs.
  • New (Nov 2025): RDS for SQL Server Web Edition now supports Multi-AZ using block-level replication, eliminating the need for more expensive Enterprise/Standard editions for high availability.
  • SQL Server Read Replicas now support cross-region deployment in 16+ additional AWS Regions (Jan 2026) and additional storage volumes up to 256 TiB (May 2026).

Comparison Summary Table

Feature Multi-AZ DB Instance Multi-AZ DB Cluster Read Replica
Purpose High Availability HA + Read Scaling + Low Write Latency Read Scalability
Replication Synchronous Semi-synchronous Asynchronous
Standby Readable No Yes (2 readable standbys) Yes
Failover Time 60–120 seconds Under 35 seconds Manual promotion required
Failover (with RDS Proxy) Improved Under 1 second N/A
Supported Engines All RDS engines MySQL, PostgreSQL only All RDS engines
Number of Standbys 1 2 Up to 5 (15 with cascading)
Cross-Region No No Yes
Automated Backups From standby From reader instance Optional
Data Loss on Failover Zero Zero Potential (async lag)

Related Posts

📖 Related: AWS RDS Backup, Snapshots & Restore – Complete Guide

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. You are running a successful multi-tier web application on AWS and your marketing department has asked you to add a reporting tier to the application. The reporting tier will aggregate and publish status reports every 30 minutes from user-generated information that is being stored in your web applications database. You are currently running a Multi-AZ RDS MySQL instance for the database tier. You also have implemented ElastiCache as a database caching layer between the application tier and database tier. Please select the answer that will allow you to successfully implement the reporting tier with as little impact as possible to your database.
    1. Continually send transaction logs from your master database to an S3 bucket and generate the reports of the S3 bucket using S3 byte range requests.
    2. Generate the reports by querying the synchronously replicated standby RDS MySQL instance maintained through Multi-AZ (Standby instance cannot be used as a scaling solution)
    3. Launch an RDS Read Replica connected to your Multi-AZ master database and generate reports by querying the Read Replica.
    4. Generate the reports by querying the ElastiCache database caching tier. (ElasticCache does not maintain full data and is simply a caching solution)
  2. A company is deploying a new two-tier web application in AWS. The company has limited staff and requires high availability, and the application requires complex queries and table joins. Which configuration provides the solution for the company’s requirements?
    1. MySQL Installed on two Amazon EC2 Instances in a single Availability Zone (does not provide High Availability out of the box)
    2. Amazon RDS for MySQL with Multi-AZ
    3. Amazon ElastiCache (Just a caching solution)
    4. Amazon DynamoDB (Not suitable for complex queries and joins)
  3. Your company is getting ready to do a major public announcement of a social media site on AWS. The website is running on EC2 instances deployed across multiple Availability Zones with a Multi-AZ RDS MySQL Extra Large DB Instance. The site performs a high number of small reads and writes per second and relies on an eventual consistency model. After comprehensive tests you discover that there is read contention on RDS MySQL. Which are the best approaches to meet these requirements? (Choose 2 answers)
    1. Deploy ElastiCache in-memory cache running in each availability zone
    2. Implement sharding to distribute load to multiple RDS MySQL instances (this is only a read contention, the writes work fine)
    3. Increase the RDS MySQL Instance size and Implement provisioned IOPS (not scalable, this is only a read contention, the writes work fine)
    4. Add an RDS MySQL read replica in each availability zone
  4. Your company has HQ in Tokyo and branch offices all over the world and is using logistics software with a multi-regional deployment on AWS in Japan, Europe and US. The logistic software has a 3-tier architecture and currently uses MySQL 5.6 for data persistence. Each region has deployed its own database. In the HQ region you run an hourly batch process reading data from every region to compute cross-regional reports that are sent by email to all offices this batch process must be completed as fast as possible to quickly optimize logistics. How do you build the database architecture in order to meet the requirements?
    1. For each regional deployment, use RDS MySQL with a master in the region and a read replica in the HQ region
    2. For each regional deployment, use MySQL on EC2 with a master in the region and send hourly EBS snapshots to the HQ region
    3. For each regional deployment, use RDS MySQL with a master in the region and send hourly RDS snapshots to the HQ region
    4. For each regional deployment, use MySQL on EC2 with a master in the region and use S3 to copy data files hourly to the HQ region
    5. Use Direct Connect to connect all regional MySQL deployments to the HQ region and reduce network latency for the batch process
  5. What would happen to an RDS (Relational Database Service) Multi-Availability Zone deployment if the primary DB instance fails?
    1. IP of the primary DB Instance is switched to the standby DB Instance.
    2. A new DB instance is created in the standby availability zone.
    3. The canonical name record (CNAME) is changed from primary to standby.
    4. The RDS (Relational Database Service) DB instance reboots.
  6. Your business is building a new application that will store its entire customer database on a RDS MySQL database, and will have various applications and users that will query that data for different purposes. Large analytics jobs on the database are likely to cause other applications to not be able to get the query results they need to, before time out. Also, as your data grows, these analytics jobs will start to take more time, increasing the negative effect on the other applications. How do you solve the contention issues between these different workloads on the same data?
    1. Enable Multi-AZ mode on the RDS instance
    2. Use ElastiCache to offload the analytics job data
    3. Create RDS Read-Replicas for the analytics work
    4. Run the RDS instance on the largest size possible
  7. Will my standby RDS instance be in the same Availability Zone as my primary?
    1. Only for Oracle RDS types
    2. Yes
    3. Only if configured at launch
    4. No
  8. Is creating a Read Replica of another Read Replica supported?
    1. Only in certain regions
    2. Only with MySQL based RDS Yes, for MySQL and PostgreSQL (14.1+). Both support cascading read replicas with up to 3 levels of chaining.
    3. Only for Oracle RDS types
    4. No
  9. A user is planning to set up the Multi-AZ feature of RDS. Which of the below mentioned conditions won’t take advantage of the Multi-AZ feature?
    1. Availability zone outage
    2. A manual failover of the DB instance using Reboot with failover option
    3. Region outage
    4. When the user changes the DB instance’s server type
  10. When you run a DB Instance as a Multi-AZ deployment, the “_____” serves database writes and reads
    1. secondary
    2. backup
    3. stand by
    4. primary
  11. When running my DB Instance as a Multi-AZ deployment, can I use the standby for read or write operations?
    1. Yes
    2. Only with MSSQL based RDS
    3. Only for Oracle RDS instances
    4. No (for Multi-AZ DB Instance deployment. Note: Multi-AZ DB Cluster deployment provides readable standbys)
  12. Read Replicas require a transactional storage engine and are only supported for the _________ storage engine
    1. OracleISAM
    2. MSSQLDB
    3. InnoDB
    4. MyISAM
  13. A user is configuring the Multi-AZ feature of an RDS DB. The user came to know that this RDS DB does not use the AWS technology, but uses server mirroring to achieve replication. Which DB is the user using right now?
    1. MySQL
    2. Oracle
    3. MS SQL (Note: AWS now recommends Always On Availability Groups over Database Mirroring. SQL Server Web Edition uses block-level replication for Multi-AZ as of Nov 2025.)
    4. PostgreSQL
  14. If I have multiple Read Replicas for my master DB Instance and I promote one of them, what happens to the rest of the Read Replicas?
    1. The remaining Read Replicas will still replicate from the older master DB Instance
    2. The remaining Read Replicas will be deleted
    3. The remaining Read Replicas will be combined to one read replica
  15. If you have chosen Multi-AZ deployment, in the event of a planned or unplanned outage of your primary DB Instance, Amazon RDS automatically switches to the standby replica. The automatic failover mechanism simply changes the ______ record of the main DB Instance to point to the standby DB Instance.
    1. DNAME
    2. CNAME
    3. TXT
    4. MX
  1. When automatic failover occurs, Amazon RDS will emit a DB Instance event to inform you that automatic failover occurred. You can use the _____ to return information about events related to your DB Instance
    1. FetchFailure
    2. DescriveFailure
    3. DescribeEvents
    4. FetchEvents
  2. The new DB Instance that is created when you promote a Read Replica retains the backup window period.
    1. TRUE
    2. FALSE
  3. Will I be alerted when automatic failover occurs?
    1. Only if SNS configured
    2. No
    3. Yes
    4. Only if Cloudwatch configured
  4. Can I initiate a “forced failover” for my MySQL Multi-AZ DB Instance deployment?
    1. Only in certain regions
    2. Only in VPC
    3. Yes
    4. No
  5. A user is accessing RDS from an application. The user has enabled the Multi-AZ feature with the MS SQL RDS DB. During a planned outage how will AWS ensure that a switch from DB to a standby replica will not affect access to the application?
    1. RDS will have an internal IP which will redirect all requests to the new DB
    2. RDS uses DNS to switch over to standby replica for seamless transition
    3. The switch over changes Hardware so RDS does not need to worry about access
    4. RDS will have both the DBs running independently and the user has to manually switch over
  6. Which of the following is part of the failover process for a Multi-AZ Amazon Relational Database Service (RDS) instance?
    1. The failed RDS DB instance reboots.
    2. The IP of the primary DB instance is switched to the standby DB instance.
    3. The DNS record for the RDS endpoint is changed from primary to standby.
    4. A new DB instance is created in the standby availability zone.
  7. Which of these is not a reason a Multi-AZ RDS instance will failover?
    1. An Availability Zone outage
    2. A manual failover of the DB instance was initiated using Reboot with failover
    3. To autoscale to a higher instance class (Refer link)
    4. Master database corruption occurs
    5. The primary DB instance fails
  8. You need to scale an RDS deployment. You are operating at 10% writes and 90% reads, based on your logging. How best can you scale this in a simple way?
    1. Create a second master RDS instance and peer the RDS groups.
    2. Cache all the database responses on the read side with CloudFront.
    3. Create read replicas for RDS since the load is mostly reads.
    4. Create a Multi-AZ RDS installs and route read traffic to standby.
  9. How does Amazon RDS multi Availability Zone model work?
    1. A second, standby database is deployed and maintained in a different availability zone from master, using synchronous replication. (Refer link)
    2. A second, standby database is deployed and maintained in a different availability zone from master using asynchronous replication.
    3. A second, standby database is deployed and maintained in a different region from master using asynchronous replication.
    4. A second, standby database is deployed and maintained in a different region from master using synchronous replication.
  10. A customer is running an application in US-West (Northern California) region and wants to setup disaster recovery failover to the Asian Pacific (Singapore) region. The customer is interested in achieving a low Recovery Point Objective (RPO) for an Amazon RDS multi-AZ MySQL database instance. Which approach is best suited to this need?
    1. Synchronous replication
    2. Asynchronous replication
    3. Route53 health checks
    4. Copying of RDS incremental snapshots
  11. A user is using a small MySQL RDS DB. The user is experiencing high latency due to the Multi AZ feature. Which of the below mentioned options may not help the user in this situation?
    1. Schedule the automated back up in non-working hours
    2. Use a large or higher size instance
    3. Use PIOPS
    4. Take a snapshot from standby Replica
  12. Are Reserved Instances available for Multi-AZ Deployments?
    1. Only for Cluster Compute instances
    2. Yes for all instance types
    3. Only for M3 instance types
  13. My Read Replica appears “stuck” after a Multi-AZ failover and is unable to obtain or apply updates from the source DB Instance. What do I do?
    1. You will need to delete the Read Replica and create a new one to replace it.
    2. You will need to disassociate the DB Engine and re-associate it.
    3. The instance should be deployed to Single AZ and then moved to Multi-AZ once again
    4. You will need to delete the DB Instance and create a new one to replace it.
  14. What is the charge for the data transfer incurred in replicating data between your primary and standby?
    1. No charge. It is free.
    2. Double the standard data transfer charge
    3. Same as the standard data transfer charge
    4. Half of the standard data transfer charge
  15. A user has enabled the Multi-AZ feature with the MS SQL RDS database server. Which of the below mentioned statements will help the user understand the Multi-AZ feature better?
    1. In a Multi-AZ, AWS runs two DBs in parallel and copies the data asynchronously to the replica copy
    2. In a Multi-AZ, AWS runs two DBs in parallel and copies the data synchronously to the replica copy
    3. In a Multi-AZ, AWS runs just one DB but copies the data synchronously to the standby replica
    4. AWS MS SQL does not support the Multi-AZ feature
  16. A company is running a batch analysis every hour on their main transactional DB running on an RDS MySQL instance to populate their central Data Warehouse running on Redshift. During the execution of the batch their transactional applications are very slow. When the batch completes they need to update the top management dashboard with the new data. The dashboard is produced by another system running on-premises that is currently started when a manually sent email notifies that an update is required The on-premises system cannot be modified because is managed by another team. How would you optimize this scenario to solve performance issues and automate the process as much as possible?
    1. Replace RDS with Redshift for the batch analysis and SNS to notify the on-premises system to update the dashboard
    2. Replace RDS with Redshift for the batch analysis and SQS to send a message to the on-premises system to update the dashboard
    3. Create an RDS Read Replica for the batch analysis and SNS to notify the on-premises system to update the dashboard
    4. Create an RDS Read Replica for the batch analysis and SQS to send a message to the on-premises system to update the dashboard.

New Practice Questions (Multi-AZ DB Cluster & Recent Features)

  1. A company needs a highly available MySQL database with the fastest possible automatic failover time and the ability to offload read queries to standby instances. Which RDS deployment option should they choose?
    1. Multi-AZ DB Instance deployment with Read Replicas
    2. Single-AZ with automated backups
    3. Multi-AZ DB Cluster deployment
    4. Aurora Global Database
  2. What is the typical failover time for an RDS Multi-AZ DB Cluster deployment?
    1. 60–120 seconds
    2. 5–10 minutes
    3. Under 35 seconds
    4. Under 5 seconds
  3. Which replication method does the RDS Multi-AZ DB Cluster deployment use?
    1. Asynchronous replication
    2. Synchronous replication
    3. Semi-synchronous replication
    4. Logical replication
  4. A database administrator wants to protect against accidental table drops by maintaining a replica that lags behind the primary by 1 hour. Which RDS feature should they use?
    1. Multi-AZ DB Instance standby
    2. Cross-Region Read Replica
    3. Delayed Read Replica
    4. Blue/Green Deployment
  5. Which of the following DB engines support Multi-AZ DB Cluster deployments? (Choose 2)
    1. Oracle
    2. MySQL
    3. SQL Server
    4. PostgreSQL
    5. MariaDB
  6. How can you reduce RDS Multi-AZ DB Cluster minor version upgrade downtime to under 1 second?
    1. Use Blue/Green Deployments
    2. Use Amazon RDS Proxy
    3. Use cross-region read replicas
    4. Use ElastiCache for connection pooling

AWS RDS Snapshots, Backup & Restore – Recovery Options

RDS Automated Backups vs Manual Snapshots

RDS BackUp, Restore and Snapshots

  • RDS creates a storage volume snapshot of the DB instance, backing up the entire DB instance and not just individual databases.
  • RDS provides two different methods Automated and Manual for backing up the DB instances.
  • RDS backups are stored securely in Amazon S3.

Automated backups

  • Backups of the DB instance are automatically created and retained.
  • RDS Backups are incremental. The first snapshot of a DB instance contains the data for the full database. Subsequent snapshots of the same database are incremental, which means that only the data that has changed after your most recent snapshot is saved.
  • Automated backups are enabled by default for a new DB instance.
  • Automated backups occur during a daily user-configurable period of time, known as the preferred backup window.
    • If a preferred backup window is not specified when a DB instance is created, RDS assigns a default 30-minute backup window which is selected at random from an 8-hour block of time per region.
    • Changes to the backup window take effect immediately.
    • Backup window cannot overlap with the weekly maintenance window for the DB instance.
  • Backups created during the backup window are retained for a user-configurable number of days, known as the backup retention period
    • If the backup retention period is not set, RDS defaults the period retention period to one day, if created using RDS API or the AWS CLI, or seven days if created from AWS Console.
    • Backup retention period can be modified with valid values are 0 (for no backup retention) to a maximum of 35 days.
  • Manual snapshot limits (100 per region) do not apply to automated backups.
  • If the backup requires more time than allotted to the backup window, the backup will continue to completion.
  • An immediate outage occurs if the backup retention period is changed
    • from 0 to a non-zero value as the first backup occurs immediately or
    • from a non-zero value to 0 as it turns off automatic backups, and deletes all existing automated backups for the instance.
  • RDS uses the periodic data backups in conjunction with the transaction logs to enable restoration of the DB Instance to any second during the retention period, up to the LatestRestorableTime (typically up to the last few minutes).
  • During the backup window,
    • for Single AZ instance, storage I/O may be briefly suspended while the backup process initializes (typically under a few seconds) and a brief period of elevated latency might be experienced.
    • for Multi-AZ DB deployments, there is No I/O suspension since the backup is taken from the standby instance
  • The first backup is a full backup, while the others are incremental.
  • Automated backups don’t occur while a DB snapshot copy is running in the same AWS Region for the same database.
  • Automated DB backups are deleted when
    • the retention period expires
    • the automated DB backups for a DB instance are disabled
    • the DB instance is deleted
  • When a DB instance is deleted,
    • a final DB snapshot can be created upon deletion; which can be used to restore the deleted DB instance at a later date.
    • RDS retains the final user-created DB snapshot along with all other manually created DB snapshots
    • all automated backups are deleted and cannot be recovered
  • NOTE: RDS can be configured to retain the automated backups on RDS instance deletion.
  • For the MySQL DB engine, automated backups are only supported for the InnoDB storage engine. Use of these features with other MySQL storage engines, including MyISAM, can lead to unreliable behavior while restoring from backups.

Point-In-Time Recovery

  • In addition to the daily automated backup, RDS archives database change logs. This enables recovery of the database to any point in time during the backup retention period, up to the last five minutes of database usage.
  • Disabling automated backups also disables point-in-time recovery
  • RDS stores multiple copies of the data, but for Single-AZ DB instances these copies are stored in a single availability zone.
  • If for any reason a Single-AZ DB instance becomes unusable, point-in-time recovery can be used to launch a new DB instance with the latest restorable data

Cross-Region Automated Backup Replication

  • RDS supports replicating automated backups to another AWS Region for disaster recovery.
  • With Cross-Region Automated Backup replication, RDS replicates snapshots and transaction logs to the chosen destination AWS Region.
  • In the event the primary AWS Region becomes unavailable, the automated backup can be restored to a point in time in the secondary AWS Region to quickly resume operations.
  • You can replicate up to 20 backups to each destination AWS Region for each AWS account.
  • Cross-Region automated backup replication is not supported for Multi-AZ DB clusters.
  • Provides cross-Region DR capability with RPO of minutes.
  • Available for RDS for MySQL, PostgreSQL, MariaDB, Oracle, SQL Server, and Db2.

DB Snapshots (User Initiated – Manual)

  • DB snapshots are manual, user-initiated backups that enable a DB instance backup to a known state, and restore to that specific state at any time.
  • RDS keeps all manual DB snapshots until explicitly deleted.
  • Manual DB snapshots have a limit of 100 per region (can be increased by requesting a quota increase).

DB Snapshots Creation

  • DB snapshot is a user-initiated storage volume snapshot of DB instance, backing up the entire DB instance and not just individual databases.
  • DB snapshots enable backing up of the DB instance in a known state as needed, and can then be restored to that specific state at any time.
  • DB snapshots are kept until explicitly deleted.
  • Creating DB snapshot on a Single-AZ DB instance results in a brief I/O suspension that typically lasts no more than a few minutes.
  • Multi-AZ DB instances are not affected by this I/O suspension since the backup is taken on the standby instance

DB Snapshot Restore

  • DB instance can be restored to any specific time during this retention period, creating a new DB instance.
  • DB restore creates a New DB instance with a different endpoint.
  • RDS uses the periodic data backups in conjunction with the transaction logs to enable restoration of the DB Instance to any second during the retention period, up to the LatestRestorableTime (typically up to the last few minutes).
  • Option group associated with the DB snapshot is associated with the restored DB instance once it is created. However, the option group is associated with the VPC, so would apply only when the instance is restored in the same VPC as the DB snapshot.
  • Default DB parameter and security groups are associated with the restored instance. After the restoration is complete, any custom DB parameter or security groups used by the restored instance should be associated explicitly.
  • A DB instance can be restored with a different storage type than the source DB snapshot. In this case, the restoration process will be slower because of the additional work required to migrate the data to the new storage type e.g. from GP2 to Provisioned IOPS
  • A DB instance can be restored with a different edition of the DB engine only if the DB snapshot has the required storage allocated for the new edition for e.g., to change from SQL Server Web Edition to SQL Server Standard Edition, the DB snapshot must have been created from a SQL Server DB instance that had at least 200 GB of allocated storage, which is the minimum allocated storage for SQL Server Standard edition
  • NEW (Feb 2026): RDS now supports viewing and modifying backup retention period and preferred backup window settings prior to and upon restoring database snapshots, providing visibility into backup configurations before initiating restore operations.

DB Snapshot Copy

  • RDS supports two types of DB snapshot copying.
    • Copy an automated DB snapshot to create a manual DB snapshot in the same AWS region. Manual DB snapshots are not deleted automatically and can be kept indefinitely.
    • Copy either an automated or manual DB snapshot from one region to another region. By copying the DB snapshot to another region, a manual DB snapshot is created that is retained in that region
  • For each AWS account, you can copy up to 20 DB snapshots at a time from one AWS Region to another.
  • Automated backups cannot be shared. They need to be copied to a manual snapshot, and the manual snapshot can be shared.
  • Manual DB snapshots can be shared with other AWS accounts and snapshots shared can be copied by other AWS accounts.
  • Snapshot Copy Encryption
    • DB snapshot that has been encrypted using an AWS Key Management Service (AWS KMS) encryption key can be copied.
    • Copying an encrypted DB snapshot results in an encrypted copy of the DB snapshot
    • When copying, DB snapshot can either be encrypted with the same KMS encryption key as the original DB snapshot, or a different KMS encryption key to encrypt the copy of the DB snapshot.
    • An unencrypted DB snapshot can be copied to an encrypted snapshot, a quick way to add encryption to a previously unencrypted DB instance.
    • Encrypted snapshot can be restored only to an encrypted DB instance.
    • If a KMS encryption key is specified when restoring from an unencrypted DB cluster snapshot, the restored DB cluster is encrypted using the specified KMS encryption key.
    • Copying an encrypted snapshot shared from another AWS account requires access to the KMS encryption key that was used to encrypt the DB snapshot.
    • AWS supports copying encrypted DB snapshots between accounts and across multiple regions seamlessly.
  • NEW (Oct 2025): AWS Backup now supports copying database snapshots across AWS Regions and accounts using a single copy action. This feature supports Amazon RDS, Aurora, Neptune, and DocumentDB snapshots, eliminating the need for sequential copying steps.

DB Snapshot Sharing

  • Manual DB snapshots or DB cluster snapshots can be shared with up to 20 other AWS accounts.
  • Manual snapshots shared with other AWS accounts can copy the snapshot, or restore a DB instance or DB cluster from that snapshot.
  • Manual snapshots can also be shared as public, which makes the snapshot available to all AWS accounts. Care should be taken when sharing a snapshot as public so that none of the private information is included
  • Shared snapshot can be copied to another region.
  • However, following limitations apply when sharing manual snapshots with other AWS accounts:
    • When a DB instance or DB cluster is restored from a shared snapshot using the AWS CLI or RDS API, the Amazon Resource Name (ARN) of the shared snapshot as the snapshot identifier should be specified.
    • DB snapshot that uses an option group with permanent or persistent options cannot be shared.
    • A permanent option cannot be removed from an option group. Option groups with persistent options cannot be removed from a DB instance once the option group has been assigned to the DB instance.
  • DB snapshots that have been encrypted “at rest” using the AES-256 encryption algorithm can be shared
  • Users can only copy encrypted DB snapshots if they have access to the AWS Key Management Service (AWS KMS) encryption key that was used to encrypt the DB snapshot.
  • AWS KMS encryption keys can be shared with another AWS account by adding the other account to the KMS key policy.
  • However, KMS key policy must first be updated by adding any accounts to share the snapshot with, before sharing an encrypted DB snapshot
  • NEW (2026): RDS for Oracle and SQL Server now support cross-account snapshot sharing for database instances with additional storage volumes (up to 256 TiB total across multiple volumes).

DB Snapshot Export to S3

  • RDS can export DB snapshot data to an Amazon S3 bucket in Apache Parquet format.
  • Supported engines: RDS for PostgreSQL, RDS for MySQL, RDS for MariaDB, Aurora PostgreSQL-Compatible, and Aurora MySQL.
  • By default, all data in the snapshot is exported. However, you can choose to export specific sets of databases, schemas, or tables.
  • After export, the data can be analyzed directly using tools like Amazon Athena or Amazon Redshift Spectrum.
  • Useful for data archiving, compliance, analytics, and machine learning use cases.
  • Export eliminates the need to restore a snapshot to query data, reducing costs and complexity.
  • Supported for Multi-AZ deployments with two readable standbys (since June 2024).

AWS Backup Integration

  • AWS Backup provides a centralized, policy-based backup service for RDS instances.
  • Periodic snapshots created by AWS Backup are considered manual backups in Amazon RDS and are taken according to backup plan schedules.
  • AWS Backup Vault Lock provides Write Once Read Many (WORM) immutability for backup data through retention policies, protecting against accidental or malicious deletion.
  • Logically Air-Gapped Vaults (GA Aug 2024): Stores immutable backup copies that are locked by default and further protected through encryption using AWS-owned keys. Provides ransomware protection by isolating backups in service-owned accounts.
  • AWS Backup supports RDS Multi-AZ clusters across 17 Regions (expanded March 2026), providing lifecycle management and immutable backups.
  • Single-Action Cross-Region/Cross-Account Copy (Oct 2025): Copy RDS snapshots across regions and accounts in one step, eliminating sequential copying.

RDS Automated Backups vs Manual Snapshots

RDS Automated Backups vs Manual Snapshots

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. Amazon RDS automated backups and DB Snapshots are currently supported for only the __________ storage engine
    1. InnoDB
    2. MyISAM
  2. Automated backups are enabled by default for a new DB Instance.
    1. TRUE
    2. FALSE
  3. Amazon RDS DB snapshots and automated backups are stored in
    1. Amazon S3
    2. Amazon EBS Volume
    3. Amazon RDS
    4. Amazon EMR
  4. You receive a frantic call from a new DBA who accidentally dropped a table containing all your customers. Which Amazon RDS feature will allow you to reliably restore your database to within 5 minutes of when the mistake was made?
    1. Multi-AZ RDS
    2. RDS snapshots
    3. RDS read replicas
    4. RDS automated backup
  5. Disabling automated backups ______ disable the point-in-time recovery.
    1. if configured to can
    2. will never
    3. will
  6. Changes to the backup window take effect ______.
    1. from the next billing cycle
    2. after 30 minutes
    3. immediately
    4. after 24 hours
  7. You can modify the backup retention period; valid values are 0 (for no backup retention) to a maximum of ___________ days.
    1. 45
    2. 35
    3. 15
    4. 5
  8. Amazon RDS automated backups and DB Snapshots are currently supported for only the ______ storage engine
    1. MyISAM
    2. InnoDB
  9. What happens to the I/O operations while you take a database snapshot?
    1. I/O operations to the database are suspended for a few minutes while the backup is in progress.
    2. I/O operations to the database are sent to a Replica (if available) for a few minutes while the backup is in progress.
    3. I/O operations will be functioning normally
    4. I/O operations to the database are suspended for an hour while the backup is in progress
  10. True or False: When you perform a restore operation to a point in time or from a DB Snapshot, a new DB Instance is created with a new endpoint.
    1. FALSE
    2. TRUE
  11. True or False: Manually created DB Snapshots are deleted after the DB Instance is deleted.
    1. TRUE
    2. FALSE
  12. A user is running a MySQL RDS instance. The user will not use the DB for the next 3 months. How can the user save costs?
    1. Pause the RDS activities from CLI until it is required in the future
    2. Stop the RDS instance
    3. Create a snapshot of RDS to launch in the future and terminate the instance now
    4. Change the instance size to micro
  13. A company needs to ensure their RDS database backups are protected from ransomware and accidental deletion. Which AWS service feature provides immutable, WORM-compliant backup storage?
    1. RDS automated backup retention
    2. RDS Multi-AZ deployment
    3. AWS Backup Vault Lock
    4. RDS snapshot sharing
  14. A disaster recovery team needs to be able to restore their RDS database in a secondary AWS Region. Which RDS feature provides cross-Region point-in-time recovery capability?
    1. RDS Read Replicas
    2. Cross-Region Automated Backup Replication
    3. RDS Manual Snapshot Copy
    4. RDS Multi-AZ Deployment
  15. An analytics team needs to query data from an RDS snapshot without restoring the entire database. What is the most cost-effective approach?
    1. Restore the snapshot to a new RDS instance and run queries
    2. Export the snapshot data to S3 in Parquet format and use Athena to query
    3. Create a read replica from the snapshot
    4. Copy the snapshot to another region and restore there

References

AWS RDS Multi-AZ – DB Instance vs DB Cluster Deployment

RDS Multi-AZ DB Instance vs DB Cluster

RDS Multi-AZ DB Instance vs DB Cluster

  • RDS Multi-AZ deployments provide high availability and automatic failover support for DB instances
  • Multi-AZ helps improve the durability and availability of a critical system, enhancing availability during planned system maintenance, DB instance failure, and Availability Zone disruption.
  • A Multi-AZ DB instance deployment has one standby DB instance that provides failover support but doesn’t serve read traffic.
  • A Multi-AZ DB cluster deployment has two standby DB instances that provide failover support and can also serve read traffic.

RDS Multi-AZ DB Instance vs DB Cluster

Instances & Availability Zones

  • A Single AZ instance creates a single DB instance in any specified AZ.
  • A Multi-AZ DB Instance deployment creates a Primary and a Standby instance in two different AZs
  • A Multi-AZ DB Cluster deployment creates a Primary Writer and two Readable Standby instances in three different AZs

Replication Mode

  • Multi-AZ DB instance deployment synchronously replicates the data from the primary DB instance to a standby instance in a different AZ.
  • Multi-AZ DB cluster deployment semi-synchronously replicates data from the writer DB instance to both reader DB instances using the DB engine’s native replication capabilities.

Standby Instance can Accept Reads

  • Multi-AZ DB instance deployment is a high-availability solution and the standby instance does not support requests.
  • Multi-AZ DB cluster deployment provides readable standby instances to increase application read-throughput.

Commit Latency

  • Single AZ instance has the lowest commit latency.
  • Multi-AZ DB instance deployment has a high commit latency as compared to the Single AZ instance as the data needs to be synchronously replicated to the standby instance.
  • Multi-AZ DB cluster deployment provides up to 2x faster transaction commit latency compared to Multi-AZ DB instance as it performs semi-synchronous replication.

Automatic Failover & Failover Time

  • Single AZ instances do not support automatic failover and failure would result in data loss. Use point-in-time recovery with backups to restore the database.
  • Multi-AZ DB instance deployment performs an automatic failover to the standby instance, and the failover time can be up to 120 seconds based on the crash recovery.
  • Multi-AZ DB cluster deployment performs an automatic failover to a reader DB instance in a different AZ, and the failover time is typically under 35 seconds.
  • Using RDS Proxy with Multi-AZ DB cluster can further reduce failover time by bypassing DNS propagation delays.

Maintenance & Upgrades

  • Multi-AZ DB instance deployment requires longer downtime for minor version upgrades as the primary instance must be upgraded.
  • Multi-AZ DB cluster deployment supports minor version upgrades and system maintenance updates with typically 35 seconds or less of write downtime.
  • When combined with RDS Proxy, Multi-AZ DB cluster can achieve minor version upgrades with typically 1 second or less of downtime.

Storage Options

  • Single AZ and Multi-AZ DB instance deployments support General Purpose SSD (gp2, gp3), Provisioned IOPS (io1, io2), and magnetic storage (deprecated April 2026).
  • Multi-AZ DB clusters now support three storage types:
    • General Purpose gp3 (added Feb 2024) – Cost-effective option with up to 64,000 IOPS, suitable for a broad range of workloads.
    • Provisioned IOPS io1 – Up to 256,000 IOPS with consistent single-digit millisecond latency.
    • Provisioned IOPS io2 Block Express (added Mar 2024) – Sub-millisecond latency, 99.999% durability, up to 256,000 IOPS. Best for latency-sensitive mission-critical workloads.

Supported Engines

  • Single AZ and Multi-AZ DB instance deployments support all DB engines
  • Multi-AZ DB clusters are supported only for the MySQL and PostgreSQL DB engines.

Performance Optimizations (Multi-AZ DB Cluster)

  • RDS Optimized Writes – Delivers up to 2x improvement in write transaction throughput by writing only once to the database (bypasses the double-write buffer).
  • RDS Optimized Reads – Provides up to 2x faster complex query processing by using local NVMe-based instance storage for temporary tables.
  • These optimizations are available for Multi-AZ DB cluster deployments with supported instance classes.

Additional Features (Multi-AZ DB Cluster)

  • IAM Database Authentication (Oct 2024) – Centrally manage database access using AWS IAM instead of password-based credentials.
  • Security Certificate Rotation (Mar 2024) – Supports rotation of database security certificates for enhanced security.
  • Stop and Start (Aug 2024) – Multi-AZ DB clusters can be stopped and started, useful for reducing costs in non-production environments.
  • RDS Proxy Support – Enables connection pooling, faster failover, and reduced downtime during maintenance.

Cost

  • Single AZ is the most cost-effective option.
  • Multi-AZ DB Instance deployment costs more than a Single AZ as it maintains a synchronous standby instance.
  • Multi-AZ DB Cluster creates 3 instances. However, with the addition of gp3 storage support (Feb 2024), it is now more cost-effective for workloads that previously required io1 volumes.
  • Multi-AZ DB Cluster can replace a Multi-AZ DB instance plus a separate read replica, potentially reducing total cost while improving performance.

Use Cases

  • Single AZ deployments are suitable for non-critical dev, test environments.
  • Multi-AZ DB instance deployments are suitable for production workloads requiring high availability with simple failover.
  • Multi-AZ DB cluster deployments are suitable for critical production environments requiring high availability, low write latency, read scalability, fast failover (under 35 seconds), and minimal maintenance downtime.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. A company runs a critical production database on Amazon RDS for MySQL. They need high availability with the fastest possible failover time and also require read scalability. Which deployment option best meets these requirements?
    1. Single-AZ DB instance with Read Replicas
    2. Multi-AZ DB instance deployment
    3. Multi-AZ DB cluster deployment
    4. Amazon Aurora with Read Replicas
    Show Answer

    Answer: c – Multi-AZ DB cluster provides failover typically under 35 seconds and readable standby instances for read scaling.

  2. A company uses an RDS Multi-AZ DB cluster and wants to minimize downtime during minor version upgrades. What should they do to achieve less than 1 second of downtime?
    1. Convert to Aurora
    2. Use RDS Proxy in front of the Multi-AZ DB cluster
    3. Use Blue/Green deployments
    4. Take a manual snapshot before upgrade
    Show Answer

    Answer: b – RDS Proxy with Multi-AZ DB cluster reduces minor version upgrade downtime to typically 1 second or less.

  3. Which storage types are supported for RDS Multi-AZ DB cluster deployments? (Select THREE)
    1. General Purpose SSD (gp2)
    2. General Purpose SSD (gp3)
    3. Provisioned IOPS (io1)
    4. Provisioned IOPS (io2 Block Express)
    5. Magnetic storage
    Show Answer

    Answer: b, c, d – Multi-AZ DB clusters support gp3, io1, and io2 Block Express storage volumes.

  4. What is the typical failover time for an RDS Multi-AZ DB cluster deployment?
    1. Under 120 seconds
    2. Under 75 seconds
    3. Under 35 seconds
    4. Under 10 seconds
    Show Answer

    Answer: c – Multi-AZ DB cluster failover is typically under 35 seconds.

References

AWS RDS Multi-AZ DB Instance

RDS Multi-AZ Instance Deployment

RDS Multi-AZ DB Instance Deployment

  • RDS automatically creates a primary DB Instance and synchronously replicates the data to a standby instance in a different AZ.
  • RDS performs an automatic failover to the standby, so that database operations can be resumed as soon as the failover is complete.
  • RDS Multi-AZ deployment maintains the same endpoint for the DB Instance after a failover, so the application can resume database operation without the need for manual administrative intervention.
  • Multi-AZ is a High Availability feature and NOT a scaling solution for read-only scenarios; a standby replica can’t be used to serve read traffic. To service read-only traffic, use a Read Replica or consider Multi-AZ DB Cluster deployment which provides readable standbys.
  • Multi-AZ deployments for MariaDB, MySQL, Oracle, PostgreSQL, and RDS Custom for SQL Server DB instances use Amazon failover technology. SQL Server DB instances use SQL Server Database Mirroring (DBM) or Always On Availability Groups (AGs). SQL Server 2022 Web Edition supports Multi-AZ through block-level replication.

RDS Multi-AZ Instance Deployment

  • In a Multi-AZ deployment,
    • RDS automatically provisions and maintains a synchronous standby replica in a different Availability Zone.
    • Copies of data are stored in different AZs for greater levels of data durability.
    • Primary DB instance is synchronously replicated across Availability Zones to a standby replica to provide
      • data redundancy,
      • eliminate I/O freezes during snapshots and backups
      • and minimize latency spikes during system backups.
    • DB instances may have increased write and commit latency compared to a Single AZ deployment, due to the synchronous data replication
    • Transaction success is returned only if the commit is successful both on the primary and the standby DB
    • There might be a change in latency if the deployment fails over to the standby replica, although AWS is engineered with low-latency network connectivity between Availability Zones.
  • When using the BYOL licensing model, a license for both the primary instance and the standby replica is required
  • For production workloads, it is recommended to use Multi-AZ deployment with Provisioned IOPS and DB instance classes optimized for Provisioned IOPS (e.g., current-generation M5, M6g, M6i, R5, R6g, R6i, or newer Graviton-based instances) for fast, consistent performance.
  • When Single-AZ deployment is modified to a Multi-AZ deployment (for engines other than SQL Server or Amazon Aurora)
    • RDS takes a snapshot of the primary DB instance from the deployment and restores the snapshot into another Availability Zone.
    • RDS then sets up synchronous replication between the primary DB instance and the new instance.
    • This avoids downtime during conversion from Single AZ to Multi-AZ.
  • An existing Single AZ instance can be converted into a Multi-AZ instance by modifying the DB instance without any downtime.

ENA Express for Multi-AZ Replication (2026)

  • As of May 2026, Amazon RDS Multi-AZ instances use ENA Express for replication traffic between Availability Zones.
  • ENA Express uses AWS’s Scalable Reliable Datagram (SRD) protocol to optimize network performance.
  • Delivers up to 25 Gbps single-flow bandwidth for cross-AZ replication traffic with advanced congestion control and multi-pathing capabilities.
  • Reduces latency variability for Multi-AZ deployments and delivers increased write throughput and lower write latencies for write-intensive workloads.
  • SRD improves replication by dynamically distributing traffic across multiple network paths and adapting to congestion in real time.
  • Available at no additional charge for RDS for MariaDB, MySQL, PostgreSQL, Db2, and Oracle.
  • To enable on existing instances, perform a start-stop or scale compute action.

RDS Multi-AZ Failover Process

  • In the event of a planned or unplanned outage of the DB instance,
    • RDS automatically switches to a standby replica in another AZ, if enabled for Multi-AZ.
    • The time taken for the failover to complete depends on the database activity and other conditions at the time the primary DB instance became unavailable.
    • Failover times are typically 60-120 secs. However, large transactions or a lengthy recovery process can increase failover time.
    • Failover mechanism automatically changes the DNS record of the DB instance to point to the standby DB instance.
    • DNS propagation can take up to 35 seconds to complete during failover.
    • Multi-AZ switch is seamless to the applications as there is no change in the endpoint URLs but just needs to re-establish any existing connections to the DB instance.
  • RDS handles failover automatically so that database operations can be resumed as quickly as possible without administrative intervention.
  • Primary DB instance switches over automatically to the standby replica if any of the following conditions occur:
    • Primary Availability Zone outage
    • Loss of network connectivity to primary
    • Primary DB instance fails
    • DB instance’s server type is changed
    • Operating system of the DB instance is undergoing software patching
    • Compute unit failure on the primary
    • Storage failure on the primary
    • A manual failover of the DB instance was initiated using Reboot with failover (also referred to as Forced Failover)
  • If the Multi-AZ DB instance has failed over, can be determined by
    • DB event subscriptions can be set up to notify you via email or SMS that a failover has been initiated.
    • DB events can be viewed via the Amazon RDS console or APIs.
    • The current state of the Multi-AZ deployment can be viewed via the RDS console and APIs.

RDS Proxy for Faster Failover

  • Amazon RDS Proxy can significantly reduce failover downtime for Multi-AZ DB instance deployments.
  • RDS Proxy eliminates the 35-second DNS propagation delay by continuously monitoring both primary and standby instances, allowing it to bypass DNS propagation entirely.
  • As of Dec 2024, AWS has optimized the planned failover process with RDS Proxy:
    • Modify instance class — downtime reduced by up to 4.9x (MariaDB), 4.3x (MySQL), 3.3x (PostgreSQL)
    • OS upgrades — downtime reduced by up to 4.8x (MySQL), 4x (MariaDB), 3.4x (PostgreSQL)
    • Reboot with force failover — downtime reduced by up to 3x (MariaDB), 2.5x (MySQL), 1.5x (PostgreSQL)
  • During maintenance operations, RDS performs maintenance on the standby first, then does a planned failover, then completes maintenance on the old primary — minimizing overall downtime.
  • These improvements are available for RDS for MySQL, MariaDB, and PostgreSQL with no changes needed to workloads.

Multi-AZ DB Instance vs Multi-AZ DB Cluster

RDS Multi-AZ DB Instance vs DB Cluster

  • Multi-AZ DB Instance: One primary + one standby (standby NOT readable). Failover typically 60-120 seconds.
  • Multi-AZ DB Cluster: One writer + two reader instances in three AZs. Readers can serve read traffic. Failover typically under 35 seconds. Supports MySQL and PostgreSQL only.
  • Multi-AZ DB Cluster provides improved commit latency, faster failover, readable standby instances, and lower write latency compared to Multi-AZ DB Instance deployment.
  • Choose Multi-AZ DB Cluster when you need both read scaling and fast failover in a single managed deployment.

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.

References

AWS RDS Multi-AZ DB Cluster

RDS Mulit-AZ DB Cluster

RDS Multi-AZ DB Cluster

  • RDS Multi-AZ DB cluster deployment is a high-availability deployment mode of RDS with two readable standby DB instances.
  • RDS Multi-AZ DB cluster has a writer DB instance and two reader DB instances in three separate AZs in the same AWS Region.
  • Multi-AZ DB clusters provide high availability, increased capacity for read workloads, and lower write latency when compared to Multi-AZ DB instance deployments.
  • Multi-AZ DB clusters aren’t the same as Aurora DB clusters.

RDS Mulit-AZ DB Cluster

  • With a Multi-AZ DB cluster, RDS replicates data from the writer DB instance to both of the reader DB instances using the DB engine’s native replication capabilities.
  • When a change is made on the writer DB instance, it’s sent to each reader DB instance. Acknowledgment from at least one reader DB instance is required for a change to be committed.
  • Reader DB instances act as automatic failover targets and also serve read traffic to increase application read throughput.
  • If an outage occurs on the writer DB instance, RDS manages failover to one of the reader DB instances. RDS does this based on which reader DB instance has the most recent change record.
  • Multi-AZ DB clusters typically have lower write latency when compared to Multi-AZ DB instance deployments.
  • They also allow read-only workloads to run on reader DB instances.
  • Multi-AZ DB clusters support both Provisioned IOPS (io1/io2) and General Purpose gp3 storage volumes, providing flexibility to choose based on performance needs and cost.
  • Supports three types of endpoints:
    • Cluster (Writer) endpoint – connects to the writer DB instance of the DB cluster, which supports both read and write operations.
    • Reader endpoint – connects to either of the two reader DB instances, which support only read operations.
    • Instance endpoint – connects to a specific DB instance within a Multi-AZ DB cluster.

Multi-AZ DB Cluster Key Features

  • IAM Database Authentication (added Oct 2024) – Multi-AZ DB clusters now support AWS IAM database authentication, allowing centralized access management without storing password-based credentials in the database.
  • gp3 Storage Support (added Feb 2024) – Multi-AZ DB clusters support General Purpose gp3 storage volumes with baseline performance of 3,000 IOPS included and ability to scale up to 64,000 IOPS independently of storage capacity.
  • Security Certificate Rotation (added Mar 2024) – Multi-AZ DB clusters support database security certificate rotation for SSL/TLS certificate management.
  • Near-Zero Downtime Minor Version Upgrades (added Nov 2023) – Minor version upgrades and system maintenance updates can be performed with typically 35 seconds or less of downtime, and as low as 1 second when combined with Amazon RDS Proxy.
  • Read Replicas – You can create DB instance read replicas from a Multi-AZ DB cluster. One of the reader instances is always the source of replication, not the writer instance.

Migrating to a Multi-AZ DB Cluster

  • You can migrate from a Single-AZ DB instance or Multi-AZ DB instance deployment to a Multi-AZ DB cluster using a read replica.
  • Create a Multi-AZ DB cluster read replica from your existing DB instance, then promote it to a standalone Multi-AZ DB cluster.
  • This approach minimizes downtime and ensures continuous operation during migration.
  • The Multi-AZ DB cluster read replica must be on the same major version as its source, and the same or higher minor version.
  • You cannot directly upgrade/convert a Single-AZ or Multi-AZ DB instance deployment into a Multi-AZ DB cluster in-place.

Multi-AZ DB Cluster Limitations

  • Multi-AZ DB clusters are supported only for the MySQL and PostgreSQL DB engines.
  • Multi-AZ DB clusters don’t support modifications at the DB instance level because all modifications are done at the DB cluster level.
  • The DB instances in a Multi-AZ DB cluster can’t be added to an active-active cluster.
  • Multi-AZ DB clusters don’t support the following features:
    • IPv6 connections (dual-stack mode)
    • Cross-Region automated backups
    • Kerberos authentication
    • Modifying the port (workaround: restore to a point in time and specify a different port)
    • Option groups
    • Point-in-time-recovery (PITR) for deleted clusters
    • Storage autoscaling by setting the maximum allocated storage (workaround: manually scale storage)
    • Stopping and starting the Multi-AZ DB cluster natively (workaround: delete and restore from snapshot)
    • Copying a snapshot of a Multi-AZ DB cluster
    • Encrypting an unencrypted Multi-AZ DB cluster
  • RDS for PostgreSQL Multi-AZ DB clusters don’t support the aws_s3 and pg_transport extensions.
  • You can’t create a Multi-AZ DB cluster read replica from an existing Multi-AZ DB cluster.

RDS Multi-AZ DB Cluster Failover

  • RDS automatically fails over to a reader DB instance in a different AZ in case of a planned or unplanned outage of the writer DB instance, as quickly as possible without administrative intervention.
  • Failover time taken depends on the database activity and other conditions when the writer DB instance becomes unavailable and is typically under 35 seconds.
  • Failover completes when both reader DB instances have applied outstanding transactions from the failed writer.

Multi-AZ DB Instance vs Multi-AZ DB Cluster

RDS Multi-AZ DB Instance vs DB Cluster

AWS Certification Exam Practice Questions

  • Questions are collected from Internet and the answers are marked as per my knowledge and understanding (which might differ with yours).
  • AWS services are updated everyday and both the answers and questions might be outdated soon, so research accordingly.
  • AWS exam questions are not updated to keep up the pace with AWS updates, so even if the underlying feature has changed the question might not be updated
  • Open to further feedback, discussion and correction.
  1. A company uses Amazon RDS for PostgreSQL in a Multi-AZ DB instance deployment. The database team needs to reduce write latency and also requires read replicas for reporting workloads. Which approach meets these requirements with the LEAST operational overhead?
    1. Create an Aurora PostgreSQL cluster with read replicas
    2. Migrate to a Multi-AZ DB cluster deployment using a read replica, then promote it
    3. Create cross-region read replicas from the existing Multi-AZ DB instance
    4. Enable Enhanced Monitoring to reduce latency
    Show Answer

    Answer: b – Multi-AZ DB clusters provide up to 2x lower write latency and built-in readable standby instances. Migration via read replica promotion minimizes downtime.

  1. A solutions architect is designing a highly available database solution using RDS Multi-AZ DB cluster. The application team wants to use IAM-based authentication instead of database passwords. Which statement is correct?
    1. Multi-AZ DB clusters do not support IAM database authentication
    2. Multi-AZ DB clusters support IAM database authentication for centralized access management
    3. IAM authentication is only supported with Aurora DB clusters
    4. IAM authentication requires Kerberos to be enabled on the cluster
    Show Answer

    Answer: b – As of October 2024, RDS Multi-AZ DB clusters support IAM database authentication.

  1. A company wants to deploy an RDS Multi-AZ DB cluster with cost-effective storage while maintaining good performance for a medium-sized workload. Which storage option should they choose?
    1. General Purpose gp2 storage
    2. Provisioned IOPS io1 storage
    3. General Purpose gp3 storage
    4. Magnetic storage
    Show Answer

    Answer: c – Since February 2024, Multi-AZ DB clusters support gp3 storage which provides baseline 3,000 IOPS included with the storage price, and allows scaling up to 64,000 IOPS independently of capacity.

  1. A DevOps engineer needs to perform a minor version upgrade on an RDS Multi-AZ DB cluster in production with minimal downtime. What is the expected downtime? (Select TWO)
    1. Typically under 35 seconds without a connection proxy
    2. Typically 1 second or less when combined with Amazon RDS Proxy
    3. Zero downtime guaranteed
    4. Several minutes similar to single-AZ deployments
    5. Requires manual failover to minimize downtime
    Show Answer

    Answer: a, b – Multi-AZ DB clusters support minor version upgrades with typically 35 seconds or less of downtime, further reduced to 1 second or less when used with RDS Proxy.

  1. Which of the following features are NOT supported by RDS Multi-AZ DB clusters? (Select THREE)
    1. IAM database authentication
    2. IPv6 connections (dual-stack mode)
    3. General Purpose gp3 storage
    4. Kerberos authentication
    5. Stopping and starting the cluster
    6. Security certificate rotation
    Show Answer

    Answer: b, d, e – Multi-AZ DB clusters still do not support dual-stack mode, Kerberos authentication, or native stop/start. IAM authentication (Oct 2024), gp3 storage (Feb 2024), and certificate rotation (Mar 2024) are now supported.

📖 Related: AWS RDS Backup, Snapshots & Restore – Complete Guide

References